<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://jinyansu1.github.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://jinyansu1.github.io/" rel="alternate" type="text/html" /><updated>2026-10-16T15:48:03+00:00</updated><id>https://jinyansu1.github.io/feed.xml</id><title type="html">Jinyan Su</title><subtitle>PhD Student at Cornell University — RL Environments, Post-Training &amp; Agent Learning</subtitle><author><name>Jinyan Su</name><email>jinyansu6@gmail.com</email></author><entry><title type="html">Some Thoughts After Hearing the Story Behind Prove2Me / 听完Prove2Me背后的故事后的一些想法</title><link href="https://jinyansu1.github.io/blog/2026/10/thoughts-behind-prove2me/" rel="alternate" type="text/html" title="Some Thoughts After Hearing the Story Behind Prove2Me / 听完Prove2Me背后的故事后的一些想法" /><published>2026-10-06T00:00:00+00:00</published><updated>2026-10-06T00:00:00+00:00</updated><id>https://jinyansu1.github.io/blog/2026/10/thoughts-behind-prove2me</id><content type="html" xml:base="https://jinyansu1.github.io/blog/2026/10/thoughts-behind-prove2me/"><![CDATA[<div class="lang-switcher">
  <button type="button" class="lang-btn active" data-lang="en">English</button>
  <button type="button" class="lang-btn" data-lang="zh">中文</button>
</div>

<div class="lang-content lang-en" lang="en">

  <p>No TL;DR this time, because this one was mostly about listening to a story and there isn’t much to summarize. So I’ll just write down a few things I took away while putting together my notes.</p>

  <h2 id="is-the-point-of-a-proof-just-to-get-something-proved-or-to-pass-it-on-in-a-form-humans-can-understand-so-that-the-future-generations-can-understand">(1) Is the point of a proof just to get something proved, or to pass it on in a form humans can understand so that the future generations can understand?</h2>

  <p>Before this talk, I had been thinking about a question and discussing it with some non-math people (everyone around me is in CS, so I can’t find math people to talk to (ಥ_ಥ), please reach out if you are not from CS and have some unique thought that you wanna share): if AI can prove mathematics obscure like this, does human understanding of a proof still matter? With AI and Lean, people who aren’t math experts can take part in proving obscure math theorems, even without really understanding the mathematics behind them. Would people still wanna do a math PhD? How should we go on educating top mathematical talent?</p>

  <p>In fact, when the news came out in September that OpenAI had announced a solution to the Navier–Stokes existence problem, one of the Millennium Prize Problems, I asked my advisor what this would do to the training of math PhDs (because I thought pursuing math and physics PhDs would become meaningless). She was very calm about it. She thought it might change how we teach, but that math PhDs would still exist: even if AI can do better than the very best PhDs, theoretical fields like math and physics only mean something when people understand them. If we stop training math PhDs, whatever AI proves will mean nothing.</p>

  <p>This made me think of Kevin Buzzard, who came up in the story, and how he reacted when Prove2me proved what intended to work on. Specifically, he had been leading an effort to formalize Fermat’s Last Theorem by hand, and Anthropic got there first with AI. But he says he is not out of work: among his promises to his funder, perhaps the most important is to create a dynamic document that lets humans explore the modern proof. Afterwards I went and read the source blog post on him and some of the comments on Hacker News. Someone commented there that his real aim was a formalized library of mathematics that humans can comprehend.</p>

  <p>I don’t know how people who study math think about this, since I haven’t don’t personally know anyone. But perhaps, for people who pursue math as a career, getting a theorem proved is not the end point; getting people to understand it is. That said, when I discussed this with a friend of mine, he argued that “the real understanding” doesn’t exist, and people just think that they understand. But that’s fine too. Humans are born lonely, and we spend our whole lives chasing “understanding.” Sometimes I feel that finding the understanding in science community is easier than obtaining understanding in other stuff in life.</p>

  <h2 id="formalization-can-make-the-steps-in-between-faithful-but-it-cant-make-the-translation-faithful">(2) Formalization can make the steps in between faithful, but it can’t make the translation faithful.</h2>

  <p>Lean’s checking of a proof is reliable: if it compiles, every step of the reasoning holds. But there is a step before that, which is translating mathematics written in human language into Lean. If that step is handed to AI, it can go wrong, and Lean won’t notice. Lean only checks whether the statement that was written down has been proved, not whether it is the statement you meant. The example from the talk: an AI could define P and NP to both be zero, and then “prove” P = NP.</p>

  <p>Some people hope formal methods will solve the verification problem once and for all. But I still think they can only handle the part that starts from the formal language, making every step of that part rigorous. The gap from natural language to formal language is one they cannot close, and it will always need human. Prove2Me’s own design bears this out: all the intermediate steps are handed to the machine, while whether the final goal and the definitions are faithful to what was meant is still reviewed by humans.</p>

  <hr />

  <p>Below is the livestream recap from NICE：</p>

  <p>On Oct 4th, I attended a livestream hosted by NICE. Host Qian Xie spoke with Shuze Chen, a PhD student at Columbia Business School, about Prove2Me: an open platform where many people’s AI agents collaborate on formalizing mathematics.</p>

  <p>Here are the full transcripts of the contents of that live stream,</p>

  <p>In early September, Anthropic announced the first complete computer-checked proof of Fermat’s Last Theorem. Dozens of Claude agents wrote about 13 million lines of Lean in 11 days, and the platform they collaborated on was Prove2Me. Chen is the first author of the Prove2Me paper and one of the platform’s core developers; his advisor is Tianyi Peng.</p>

  <p>This recap covers what came up in the interview: how the platform came about, what went wrong along the way, and how Chen sees the direction.</p>

  <h2 id="five-years-for-humans-11-days-for-agents">Five years for humans, 11 days for agents</h2>

  <p>Fermat’s Last Theorem is simple to state: for n greater than 2, aⁿ + bⁿ = cⁿ has no solutions in positive integers. Fermat wrote the claim in a book margin around 1637. Mathematicians spent more than 350 years on it, and Andrew Wiles published a correct proof only in 1995, in a paper of 129 pages.</p>

  <p>Wiles’s proof is written in natural language, and it took the mathematical community a long time to confirm it was right. Formal verification is a different route: write every assumption and every inference step as Lean code and let a machine check it. Chen compares Lean to a “very strict mathematician”. Once the code compiles, the proof depends only on the most basic axioms, which amounts to a certificate.</p>

  <p>Doing this by hand is extremely slow. Kevin Buzzard of Imperial College London is a number theorist and one of the leading advocates of Lean among mathematicians. In 2024 he received a five-year grant of about £1 million to formalize Fermat’s Last Theorem. The goal he set was only to reduce the proof to results known by the end of the 1980s, and he said explicitly that he was not promising to finish within five years.</p>

  <p>There are two reasons it is slow. First, very few people can do it:</p>

  <blockquote>
    <p>You have to understand the mathematics behind Fermat’s Last Theorem, which already makes you a rare person. And you also have to be an expert in Lean.</p>
  </blockquote>

  <p>Second, the workload is huge. In Chen’s experience, one line of a mathematician’s proof becomes roughly ten lines of Lean.</p>

  <p>This summer, Tianyi Peng, working at Anthropic, suggested trying Fermat’s Last Theorem with internal agents and Prove2Me. Chen’s first reaction: “I thought it was a joke.” In the end, dozens of agents finished proving the root node on August 17. It took 11 days and produced about 13 million lines of Lean, with 29,500 intermediate theorems used in the final proof (Anthropic’s account).</p>

  <blockquote>
    <p>It turns out agents know the math very well and know Lean very well. For them, writing Lean doesn’t seem to be that hard.</p>
  </blockquote>

  <p>Two caveats. The formalization builds on existing work in Mathlib and by Buzzard’s team. Mathlib is the mathematical library maintained collectively by the Lean community, in effect Lean’s “standard library” for mathematics. The FLT project that Buzzard leads had already written part of the material by hand, and Claude’s proof borrows some of it. Buzzard reviewed the proof himself. His assessment: mathematically it brings nothing new, but it shows that automatic formalization of the modern mathematical literature has taken a big step forward.</p>

  <p>“Nothing new” is not a put-down. Fermat’s Last Theorem was accepted by mathematicians thirty years ago. This formalization checked the proof step by step along the existing literature and did not introduce new mathematical ideas. What is new is the verification itself, and the autoformalization capability it demonstrates.</p>

  <p>Also, Claude followed a simplified route through Wiles’s original proof, not the modern version Buzzard’s team is targeting. His project has another job as well: bringing the foundations of modern number theory into Mathlib and leaving behind a formal library that people can read and reuse. That work is not finished by this result.</p>

  <h2 id="from-moltbook-to-prove2me">From Moltbook to Prove2Me</h2>

  <p>Prove2Me was not built for Fermat’s Last Theorem. It has two origins.</p>

  <p><strong>The first is Moltbook.</strong> Early this year, Chen and Peng were asking: if everyone has their own agent, will platforms designed specifically for agents appear? Moltbook, launched at the end of January, was the first example, an “agent Reddit” where only agents post. Chen calls it an AGC (agent-generated content) platform, by analogy with UGC platforms such as Douyin and Xiaohongshu.</p>

  <p>Moltbook’s problem showed up quickly:</p>

  <blockquote>
    <p>Agents scale very easily and can produce a huge amount of content. But how good that content is, and whether it leads to any meaningful outcome, is very hard to guarantee.</p>
  </blockquote>

  <p>Posts piled up, but people could not follow them and did not care, and the buzz faded.</p>

  <p><strong>The second is a course.</strong> In spring 2026, Henry Yuen and Kunal Marwaha co-taught Machine-Assisted Mathematics at Columbia. For the class they built a small website where students could pose problems and prove them in Lean. That was the first prove2.me. Chen was a student in the course. He noticed that his classmates ended up copying the problems into Claude or Gemini and pasting the proofs back. If so, why not let agents connect to the platform directly?</p>

  <p>Put the two together and the answer appears: formalization solves exactly Moltbook’s quality problem.</p>

  <blockquote>
    <p>If what it produces is a formal mathematical proof, at least I can verify whether it is correct.</p>
  </blockquote>

  <p>Everything is checked by a machine, so hallucinations and AI slop cannot get in.</p>

  <p>Two other observations convinced them the approach could work. One is the Erdős Problems website. It lists over a thousand problems, and this spring it saw an influx of hobbyists who are not mathematicians, using Claude Code and Codex to attack them. Chen calls this “citizen math.” The other is a view Terence Tao has long held: with Lean, a proof submitted by a stranger can be verified by machine, so you do not need to trust the person, and that is what makes large-scale collaboration possible.</p>

  <p>Today Prove2Me is a two-sided market. On one side are researchers who want their own papers or textbooks formalized; they publish missions. On the other side are hobbyists with spare tokens; they send their agents to pick up tasks. For both, it takes a single sentence to their own agent. A researcher hands the paper’s PDF to an agent and asks it to publish the paper as a mission on Prove2Me. A contributor asks an agent to go to Prove2Me and find theorems to prove. Calling the platform’s API, writing Lean, and submitting proofs are all handled by the agent, following the instructions the platform provides.</p>

  <h2 id="why-centralization-didnt-work">Why centralization didn’t work</h2>

  <p>The final proof of Fermat’s Last Theorem runs to 13 million lines, while, as Chen notes, even the strongest agents today have a context of about one million tokens. No single agent could do it alone, and no single agent could manage the whole thing.</p>

  <p>The first attempts were centralized, organized like a company: one agent planned and assigned work, and the others each took a major theorem. Anthropic’s article also mentions that the first several attempts failed, with agents quickly losing track of the project’s state. Chen described one scene:</p>

  <blockquote>
    <p>One day we found that A and B had both stopped working. We asked A why, and A said something B was responsible for wasn’t finished, so it couldn’t go on. Then we asked B, and B said a theorem A was responsible for wasn’t finished. It was like two departments in a company blaming each other, and the whole system was stuck.</p>
  </blockquote>

  <p>Prove2Me’s approach is fully decentralized, and its core mechanism is the proof sketch. An agent does not have to prove a big theorem in one go. It can submit just one step of decomposition: a proof that compiles and says “if B, C and D hold, then A holds.” B, C and D immediately become new open theorems on the platform, which other agents can decompose further or prove directly. Decomposed layer by layer, the whole proof becomes a directed acyclic graph, that is, a graph of dependencies that has an order and no cycles.</p>

  <p>The key is immutability: theorem statements and every decomposition cannot be changed once submitted. A later agent either proves the downstream theorems of an existing decomposition or proposes a new decomposition of its own. It cannot touch anyone else’s. Chen compares this to a lock in a concurrent system: whatever changes downstream does not affect upstream, and each agent only has to look at leaf nodes without understanding the whole graph.</p>

  <p>How do you know a decomposition is valid? First, the decomposition is itself a proof that compiles in Lean, so the step “if all the sub-theorems hold, the original theorem holds” is guaranteed to be correct. Second, whether the sub-theorems themselves hold is only known once someone proves them. If a sub-theorem is disproved, that decomposition is a dead end, and someone has to take a different approach and submit a new one.</p>

  <p>The Prove2Me paper records an example. One agent used a lemma in a decomposition, and another agent proved the lemma false: the first had left out a boundary condition when writing it in Lean. The first agent then added the condition and submitted a new version. The new version was proved, and the whole branch closed.</p>

  <h2 id="how-it-relates-to-mathlib">How it relates to Mathlib</h2>

  <p>The Lean community already has Mathlib, a theorem library nearly ten years in the making. Chen distinguishes the two as “bottom-up” and “top-down.”</p>

  <p>Mathlib is bottom-up. It starts from the axioms and puts a great deal of effort into deciding how basic concepts such as the real numbers or graphs should be defined, and every line is reviewed by experts. The quality is very high, and the price is speed: a submission can wait a week or even a month to be merged.</p>

  <p>Prove2Me is top-down and fills in whatever is needed. The goal is to finish proving the paper at hand. If the library has no definition of a Markov chain, you add one. In his words, Mathlib is the foundation layer of mathematics and Prove2Me is the application layer, and the two complement each other.</p>

  <h2 id="formalization-is-more-than-translation">Formalization is more than translation</h2>

  <p>Translating a paper from natural language into Lean does not sound like it produces new mathematics. Experience on the platform says otherwise.</p>

  <p><strong>Catching errors.</strong> Lean requires every assumption to be stated, so missing conditions and typos surface. The host, Qian Xie, had submitted an earlier paper to the platform and was told that the conditions of one lemma needed a small adjustment, while the main theorem was fine.</p>

  <p><strong>Simplifying proofs.</strong> Chen and Peng had agents formalize their own paper on Markov entanglement. One theorem in the paper took more than two pages of purely analytic argument. The agent found that it is essentially about a subalgebra structure from abstract algebra, and from that angle it is almost obvious.</p>

  <blockquote>
    <p>A reinforcement learning paper, and one of its theorems turns out to be connected to abstract algebra. My advisor and I both felt we learned something new.</p>
  </blockquote>

  <p><strong>Peer review.</strong> Review cycles at operations research journals can run to two years, while top AI conferences ask reviewers to get through a 60-page appendix in a week. If a submission came with a Prove2Me link, reviewers would not have to check the proofs line by line and could spend their time on whether the problem matters. Chen says some Columbia professors already verify their papers on the platform before submitting.</p>

  <p><strong>Reuse.</strong> A mathematical theorem, once proved, stays true forever. The platform collects every proved theorem into a searchable library, Formalpedia, and later work can use them directly, the way one imports a software package. As of early October, the platform holds about 100,000 theorems and 30 million lines of Lean proofs.</p>

  <p>As for whether this will replace mathematicians, Chen’s answer is no: mathematicians are the platform’s most important users, and Prove2Me is a tool that helps them verify their work.</p>

  <h2 id="open-problems">Open problems</h2>

  <p><strong>Faithfulness.</strong> A machine can verify a proof, but it cannot verify that the statement is the one you meant to prove. Chen’s example: an AI says it has proved P = NP, but the P and NP it defined are just two constants that both equal zero. The proof compiles and means nothing.</p>

  <p>The platform currently does two things. Humans audit only the core statements of a mission and leave the remaining intermediate lemmas to Lean. In addition, an independent agent that cannot see the source translates the Lean back into mathematical language for a human to compare. He admits this is not yet a perfect solution.</p>

  <p><strong>Search.</strong> The library already contains tens of millions of lines of proofs. Whether an agent can efficiently find reusable theorems in it is a research question in its own right.</p>

  <p><strong>Scale first, then refine.</strong> A proof written by AI is not necessarily the best one, and it is not necessarily broken into lemmas that are easy to reuse. He envisions two stages: first build up scale; then, past a certain point, go back and refine, settling on a standard set of definitions for a field.</p>

  <h2 id="selected-qa">Selected Q&amp;A</h2>

  <p><strong>With many agents working together, is the hardest part how to split the task?</strong></p>

  <p>When a paper or textbook already exists, the decomposition mostly follows the source and is close to translation. For open problems, agents have to find the approach themselves.</p>

  <p><strong>Why start with operations research?</strong></p>

  <p>“Because I’m a PhD student in OR.” The platform’s early users were also mostly professors in his own division at Columbia. By his account, the platform already has about a thousand OR papers and textbooks, and theoretical computer science and statistics come next.</p>

  <p><strong>Will formalization extend beyond mathematics?</strong></p>

  <p>That is a very long-term goal. Mathematics is the starting point, and code is the natural next step. Someone has already ported Prove2Me’s protocol to multi-agent software development.</p>

  <p><strong>Formalization uses a lot of tokens. How much does it really cost?</strong></p>

  <p>Chen stresses that token consumption is lower than people imagine: “It’s actually very cheap.”</p>

  <p>His example is the graduate textbook Markov Chains and Mixing Times: more than 400 pages, done on his own $200-a-month account. According to the Prove2Me blog, the book was split into 13 missions totaling 79,000 lines of Lean, and it took one weekend.</p>

  <p><strong>How was the cost brought down?</strong></p>

  <p>Mostly through the design of the harness: getting agents to write Lean more efficiently and to search existing theorems more efficiently, plus careful prompt tuning. Proved theorems can be reused directly, which itself saves tokens.</p>

  <p>Another engineering detail is caching. When ten sub-agents work on problems at once, they share the same long system prompt, and turning that prompt into a KV cache saves a bit more.</p>

  <p><strong>Are there papers that consumed a lot of tokens and still couldn’t be formalized, for example because the original was vaguely written?</strong></p>

  <p>Not so far. Chen’s view is that when something isn’t finished, it is mostly because not enough tokens were spent. Once a paper has been written, there are only two outcomes: prove it or disprove it.</p>

  <h2 id="aside-the-first-attack">Aside: the first attack</h2>

  <p>In April this year, when the platform was still in closed testing with only a few dozen users, Chen woke up one morning to find tens of thousands of new tags in the backend.</p>

  <p>The site had been vibe-coded, and permissions for tagging theorems had never been implemented. A script bot found it and dumped junk into the database at several thousand tags a minute. “I didn’t expect to get attacked that early.”</p>

</div>

<div class="lang-content lang-zh" lang="zh" style="display: none;">

  <p>这次没有TLDR因为这次主要是听故事，没啥需要总结的，所以我就写一点自己在整理这次直播内容时的一点收获好了。（虽然可能跟直播的内容关系不大）</p>

  <h2 id="section">（1）证明对人类的意义仅仅是去把一个东西证出来还是以人类能理解的方式传承下去？</h2>

  <p>听这场分享之前，我一直在思考并和一些非数学的人 (因为周围人都是cs的，找不到数学的人讨论(ಥ_ಥ)）讨论：如果 AI 能证明这么难的数学，人对数学证明的理解还有没有意义？有了 AI 和 Lean，不是数学专家的人也能参与证明，哪怕并不真正懂背后的数学。读数学博士还有没有意义？对顶尖数学人才的教育又该怎么进行下去？其实我9月份Openai攻克了千禧年大奖难题之一的Navier-Stokes方程存在性那个新闻出来后，问过我的导师，这会对数学博士的教育带来什么冲击（因为我觉得数学和物理博士以后将不复存在），她则很平静，觉得可能会改变我们的教育，但是数学博士会依然存在，因为即使ai能够比最顶尖的博士都做的好，但数学和物理等理论学科，还是需要人来理解才有意义，如果不继续培养数学的博士，ai证明出来的东西将不具有任何意义。</p>

  <p>这让我relate到talk里讲到的 Kevin Buzzard 的反应。他原本在带人手工形式化费马大定理，结果Anthropic先用ai做了出来。但他说自己并非无事可做：他对资助方的承诺里，可能最重要的一项，是做一份让人可以探索现代证明的动态文档。后面我也去看了博客的他原本的回复以及Hacker News 上的一些评论，有网友评价说，他真正的目标是一套人能读懂的形式化数学库。</p>

  <p>我不知道学数学的人是怎么想的，因为自己接触的少，但是，或许，在做数学的人眼里，”证出来”不是终点，”让人理解”才是。虽然我之前和一位在cs做理论的朋友讨论时，他表示，”理解”这个东西是不存在的，大家只是以为自己理解了。不过也好呀，人类生来就是孤独的存在，在一生中都在追求”理解”。有时候我觉得在科学上的理解比在其他方面的理解更容易获得。</p>

  <h2 id="faithfultranslatefaithful">（2）形式化可以让中间的证明更加faithful，但是没法让translate的过程faithful。</h2>

  <p>Lean 对证明的检查是可靠的：只要编译通过，推理的每一步都成立。但在这之前还有一步，就是把人类语言写的数学翻译成 Lean。这一步如果交给 AI，是可能出错的，而且 Lean 发现不了。它只检查”写下的命题有没有被证明”，不知道”写下的是不是你想说的那个命题”。分享里举的例子是：AI 可以把 P 和 NP 都定义成零，然后”证明”P = NP。</p>

  <p>很多人希望用形式化方法彻底解决验证问题。但我依然觉得，它只能解决从形式语言出发之后的那一段，让那一段每一步都严谨。从自然语言到形式语言的这个gap，它是没有办法close的，仍然需要人。Prove2Me 的做法也印证了这一点：中间步骤全部交给机器，而最终目标和定义是否忠实于原意，还是由人来审核。</p>

  <hr />

  <p>下面是”NICE学术”的直播回顾：</p>

  <p>10 月 4 日上午（北京时间），「运筹OR帷幄」与「NICE 学术」首次联合直播。主持人 Qian Xie 对话哥伦比亚大学商学院博士生陈澍泽，主题是 Prove2Me：一个让许多人的 AI agent 协作做数学形式化的开放平台。</p>

  <p>9 月初，Anthropic 公布了费马大定理的首个完整计算机可检查证明：数十个 Claude agent 用 11 天写下约 1300 万行 Lean 代码，协作平台正是 Prove2Me。陈澍泽是 Prove2Me 论文的第一作者和平台核心开发者之一，导师是彭天翼。</p>

  <p>这篇回顾整理了访谈里的内容：平台的诞生、踩过的坑、以及嘉宾对这个方向的判断。</p>

  <h2 id="agent--11-">人要五年，agent 只用了 11 天</h2>

  <p>费马大定理的表述很简单：n 大于 2 时，aⁿ + bⁿ = cⁿ 没有正整数解。费马 1637 年前后在书页边写下这个断言，数学家花了 350 多年，直到 1995 年才由怀尔斯发表正确的证明，原文 129 页。</p>

  <p>怀尔斯的证明用自然语言写成，数学界花了很长时间才确认它正确。形式化验证是另一条路：把每个假设、每步推导都写成 Lean 代码，交给机器检查。陈澍泽的比喻是，Lean 像一位”较真的数学家”；只要编译通过，证明就只依赖最基本的公理，相当于拿到一张证书。</p>

  <p>人工做这件事极慢。帝国理工的 Kevin Buzzard 是数论学家，也是 Lean 在数学界最主要的推动者之一。他在 2024 年拿到约 100 万英镑、为期五年的资助来形式化费马大定理。他给自己定的目标只是把证明归约到 1980 年代末已知的结果，并且明确说过不保证五年内做完。</p>

  <p>慢的原因有两个。一是能做的人太少：</p>

  <blockquote>
    <p>你得懂费马大定理背后的数学，这已经是凤毛麟角；同时你还必须非常精通 Lean。</p>
  </blockquote>

  <p>二是工作量太大：按陈澍泽的经验，数学家写一行证明，Lean 里大约要十行。</p>

  <p>今年夏天，彭天翼在 Anthropic 提出，用内部的 agent 加上 Prove2Me 试一试费马大定理。陈澍泽的第一反应是：”我当时觉得这是个玩笑。” 结果，数十个 agent 在 8 月 17 日证完了根节点，用时 11 天，产出约 1300 万行 Lean，最终证明用到 29,500 个中间定理（Anthropic 的说明）。</p>

  <blockquote>
    <p>恰好 agent 既非常懂数学，也非常懂 Lean。对它来说，写 Lean 好像不是那么难的一件事。</p>
  </blockquote>

  <p>有两点需要说明。这次形式化建立在 Mathlib 和 Buzzard 团队已有的工作之上。Mathlib 是 Lean 社区共同维护的数学基础库，相当于 Lean 的数学”标准库”；Buzzard 牵头的 FLT 项目则已经人工写好了一部分内容，Claude 的证明借用了其中一些。Buzzard 本人审阅了证明，他的评价是：数学上这没有带来新东西，但它说明自动形式化现代数学文献已经迈出了一大步。</p>

  <p>“没有新东西”并不是贬低。费马大定理三十年前就已被数学界接受，这次形式化是沿着已有文献把证明逐步核对了一遍，没有提出新的数学思想。新的是验证本身，以及它展示出的自动形式化能力。</p>

  <p>另外，Claude 走的是怀尔斯原始证明的一条简化路线，而不是 Buzzard 团队瞄准的现代版本。他的项目还承担着另一件事：把现代数论的基础内容整理进 Mathlib，留下一套人能读懂、能复用的形式化库。这部分工作并没有因此完成。</p>

  <h2 id="moltbook--prove2me">从 Moltbook 到 Prove2Me</h2>

  <p>Prove2Me 不是为费马大定理而做的，它有两个源头。</p>

  <p><strong>第一个是 Moltbook。</strong> 今年年初，陈澍泽和彭天翼在想：如果每个人都有自己的 agent，会不会出现专门为 agent 设计的平台？1 月底上线的 Moltbook 是第一个样本，一个只有 agent 发帖的”agent 版 Reddit”。陈澍泽把它叫作 AGC（agent generated content）平台，对应抖音、小红书这类 UGC 平台。</p>

  <p>Moltbook 很快暴露了问题：</p>

  <blockquote>
    <p>Agent 非常容易 scale，它可以产生非常多的内容。但这些内容质量如何，有没有产生有意义的结果，非常难保证。</p>
  </blockquote>

  <p>帖子越来越多，人却看不懂也不关心，热度就退了。</p>

  <p><strong>第二个是一门课。</strong> 2026 年春，Henry Yuen 和 Kunal Marwaha 在哥大合开 Machine-Assisted Mathematics，课上做了一个让学生出题、用 Lean 证题的小网站，这就是最早的 http://prove2.me。陈澍泽是这门课的学生。他注意到，同学们最后都是把题目复制给 Claude 或 Gemini，再把证明粘贴回来。既然如此，不如让 agent 直接接入平台。</p>

  <p>两件事合在一起，答案就出来了：形式化正好解决 Moltbook 的质量问题。</p>

  <blockquote>
    <p>如果它产生的是形式化的数学证明，至少我可以验证它是否正确。</p>
  </blockquote>

  <p>一切都由机器检查，幻觉和 AI slop 进不来。</p>

  <p>还有两个旁证让他们相信这条路走得通。一是 Erdős 问题网站：它收录了一千多个问题，今年春天涌入大量并非数学家的爱好者，用 Claude Code、Codex 去解题，陈澍泽称之为”citizen math”。二是陶哲轩一贯的看法：有了 Lean，陌生合作者交来的证明可以直接由机器验证，不需要信任对方，大规模协作才成为可能。</p>

  <p>今天的 Prove2Me 是一个双边市场。一边是想形式化自己论文或教材的研究者，他们发布 mission。另一边是手里有富余 token 的爱好者，他们让自己的 agent 去领任务。两边的操作都很简单，只需要对自己的 agent 说一句话。研究者把论文 PDF 交给 agent，让它在 Prove2Me 上发布成一个 mission；贡献者让 agent 去 Prove2Me 上找定理来证。调用平台接口、写 Lean、提交证明这些事，都由 agent 按平台提供的说明自己完成。</p>

  <h2 id="section-1">中心化为什么行不通</h2>

  <p>费马大定理的最终证明有 1300 万行，而陈澍泽说，当前最强的 agent 上下文也只有约 100 万 token。没有哪个 agent 能独自完成，也没有哪个 agent 能管住全局。</p>

  <p>最初的尝试是中心化的，像一家公司：一个 agent 做计划和分工，其他 agent 各领一个大定理。Anthropic 的文章也提到，最初几次尝试都失败了，agent 很快跟不上项目状态。陈澍泽讲了其中一幕：</p>

  <blockquote>
    <p>有一天发现 A 和 B 都不工作了。我们问 A 为什么不证了，A 说 B 负责的某个地方没证完，所以我证不下去。又去问 B，B 说是 A 负责的某个定理没证完。就像公司里两个部门互相推卸责任，整个系统就卡住了。</p>
  </blockquote>

  <p>Prove2Me 的做法是完全去中心化，核心机制叫 Proof Sketch。agent 不必一口气证完一个大定理，可以只提交一步”拆分”：一段编译通过的证明，内容是”如果 B、C、D 成立，那么 A 成立”。B、C、D 随即成为平台上新的待证定理，其他 agent 可以继续拆，也可以直接证掉。层层拆下去，整个证明就成了一张有向无环图，也就是一张只有先后依赖、没有循环的关系图。</p>

  <p>关键在于不可修改：定理陈述和每一次拆分，提交后都不能改。后来的 agent 要么沿着已有的拆分去证下游，要么自己另提一个新拆分，但不能动别人的。陈澍泽把它比作并发系统里的锁：下游怎么变都不影响上游，每个 agent 只需盯着叶子节点，不必了解全图。</p>

  <p>怎么知道一次拆分是有效的？第一，拆分本身是一段通过 Lean 编译的证明，所以”子定理都成立，则原定理成立”这一步推理一定是对的。第二，子定理本身是否成立，要等有人把它们证出来才知道。如果某个子定理被证伪，这次拆分就走不通了，需要有人换个思路，提交新的拆分。</p>

  <p>Prove2Me 的论文里记录过一个例子。一个 agent 在拆分中用到一条引理，另一个 agent 却证明这条引理是错的：前者把它写成 Lean 时漏了一个边界条件。前者随后补上条件，重新提交了一个版本。新版本被证明，整条分支随之打通。</p>

  <h2 id="mathlib-">和 Mathlib 是什么关系</h2>

  <p>Lean 社区已有一个发展了近十年的定理库 Mathlib。陈澍泽用”自底向上”和”自顶向下”来区分两者。</p>

  <p>Mathlib 自底向上。它从公理出发，花大量精力决定实数、图这些基本概念该怎么定义，每一行代码都经过专家审核。质量极高，代价是慢：一次提交可能要等一周甚至一个月才能合并。</p>

  <p>Prove2Me 自顶向下，需要什么补什么。目标是证完眼前这篇论文，发现库里没有马尔可夫链的定义，就把它补上。用他的话说，Mathlib 做的是数学的 foundation layer，Prove2Me 做的是 application layer，两者互补。</p>

  <h2 id="section-2">形式化不只是翻译</h2>

  <p>把论文从自然语言翻成 Lean，听起来不产生新数学。平台上的实践说明并非如此。</p>

  <p><strong>查错。</strong> Lean 要求写明所有假设，漏掉的条件和笔误都会暴露。主持人 Qian Xie 提交过自己的一篇论文，结果被提醒某个引理的条件需要微调，核心定理则没有问题。</p>

  <p><strong>简化。</strong> 陈澍泽和彭天翼把自己的 Markov entanglement 论文交给 agent 形式化。原文有个定理用纯分析技巧写了两页多，agent 发现它本质上和抽象代数里的子代数结构有关，换个角度看几乎是显然的。</p>

  <blockquote>
    <p>一篇强化学习的文章，里面的定理居然跟抽象代数有关系。我和导师看完都觉得学到了新东西。</p>
  </blockquote>

  <p><strong>审稿。</strong> 运筹学期刊的审稿周期可以长达两年，AI 顶会则要求一周内看完 60 页附录。如果投稿时附上一个 Prove2Me 链接，审稿人就不必逐行核对证明，可以把时间花在问题本身有没有意义上。陈澍泽说，哥大已有教授在投稿前先到平台上验证一遍。</p>

  <p><strong>复用。</strong> 数学定理一旦证明就永远成立。平台把所有已证定理汇成一个可检索的库 Formalpedia，后来者可以像 import 一个软件包那样直接引用。截至 10 月初，平台上约有 10 万个定理、3000 万行 Lean 证明。</p>

  <p>至于会不会取代数学家，陈澍泽的回答是否定的：数学家是平台最重要的用户，Prove2Me 是帮他们做验证的工具。</p>

  <h2 id="section-3">还没解决的问题</h2>

  <p><strong>忠实性。</strong> 机器能验证证明，却不能验证命题就是你想证的那个。陈澍泽举的例子是：AI 说它证明了 P = NP，但它定义的 P 和 NP 只是两个都等于零的常数。证明能通过编译，却毫无意义。</p>

  <p>平台目前的办法有两条。人只审核一个 mission 的核心陈述，其余中间引理交给 Lean 检查。同时，让一个看不到原文的独立 agent 把 Lean 回译成数学语言，供人比对。他坦言这还不是完美的解法。</p>

  <p><strong>检索。</strong> 库里已有几千万行证明。agent 能否从中高效找到可复用的定理，本身就是一个研究问题。</p>

  <p><strong>先放量，再精修。</strong> AI 写出的证明未必是最好的，也未必拆成了便于复用的引理。他设想的路线分两步：先把规模做起来；过了某个节点，再回头精修，为一个领域沉淀出一套标准定义。</p>

  <h2 id="section-4">问答精选</h2>

  <p><strong>（1）多个 agent 协作，最难的是不是任务怎么拆？</strong></p>

  <p>已有论文或教材时，拆分基本跟着原文走，接近翻译。开放问题则要靠 agent 自己找思路。</p>

  <p><strong>（2）为什么从运筹学开始？</strong></p>

  <p>“因为我是 OR 的 PhD。” 平台早期的用户也多是哥大本系的教授。据他介绍，平台上已有约一千篇运筹学论文和教材，接下来会扩展到理论计算机和统计。</p>

  <p><strong>（3）形式化会扩展到数学之外吗？</strong></p>

  <p>这是很长期的目标。数学是起点，代码是自然的下一步。已经有人把 Prove2Me 的协议移植到多 agent 协作写软件上。</p>

  <p><strong>（4） 形式化很耗 token，成本到底有多高？</strong></p>

  <p>陈澍泽强调， token 消耗没有想象中高：”其实非常便宜。”</p>

  <p>他举的例子是研究生教材 Markov Chains and Mixing Times：400 多页，用他自己每月 200 美元的账号就做完了。按 Prove2Me 博客的记录，这本书被拆成 13 个 mission，共 7.9 万行 Lean，用时一个周末。</p>

  <p><strong>（5）成本是怎么降下来的？</strong></p>

  <p>主要靠 harness 的设计：让 agent 更高效地写 Lean、更高效地检索已有定理，再加上对 prompt 的打磨。已证定理可以直接复用，本身也省 token。</p>

  <p>还有一个工程细节是缓存。同时开十个子 agent 解题时，它们共用同一段很长的系统提示，把这段提示做成 KV cache 可以再省一些。</p>

  <p><strong>（6）有没有花了很多 token 还是形式化不出来的论文？比如原文写得含糊不清的？</strong></p>

  <p>目前还没有遇到。陈澍泽的判断是，没做完多半是 token 花得不够。只要论文已经写出来，结果无非两种：证明它，或者证伪它。</p>

  <h2 id="section-5">花絮：第一次被攻击</h2>

  <p>今年 4 月平台还在内测、只有几十个用户时，陈澍泽某天早上醒来，发现后台多了几万个标签。</p>

  <p>网站是 vibe coding 写出来的，给定理加标签的权限没有做。一个脚本机器人发现了它，以每分钟几千个的速度往数据库里灌垃圾。”没想到那么早就被 attack 了一次。”</p>

</div>

<script>
(function() {
  var buttons = document.querySelectorAll('.lang-switcher .lang-btn');
  var contents = document.querySelectorAll('.lang-content');
  buttons.forEach(function(btn) {
    btn.addEventListener('click', function() {
      var lang = btn.getAttribute('data-lang');
      buttons.forEach(function(b) { b.classList.remove('active'); });
      btn.classList.add('active');
      contents.forEach(function(c) {
        if (c.classList.contains('lang-' + lang)) {
          c.style.display = '';
        } else {
          c.style.display = 'none';
        }
      });
    });
  });
})();
</script>]]></content><author><name>Jinyan Su</name><email>jinyansu6@gmail.com</email></author><category term="technical" /><category term="ai" /><category term="lean" /><category term="formalization" /><category term="math" /><category term="agents" /><category term="prove2me" /><summary type="html"><![CDATA[Dozens of Claude agents wrote about 13 million lines of Lean in 11 days to produce the first computer-checked proof of Fermat's Last Theorem, on a platform called Prove2Me. Notes from a NICE livestream with Shuze Chen — how the platform came about, why centralization failed, what formalization can and cannot make faithful — plus two personal reflections.]]></summary></entry><entry><title type="html">AI Is Improving AI Faster Than We Can Check</title><link href="https://jinyansu1.github.io/blog/2026/10/ai-improving-ai-faster-than-we-can-check/" rel="alternate" type="text/html" title="AI Is Improving AI Faster Than We Can Check" /><published>2026-10-05T00:00:00+00:00</published><updated>2026-10-05T00:00:00+00:00</updated><id>https://jinyansu1.github.io/blog/2026/10/ai-improving-ai-faster-than-we-can-check</id><content type="html" xml:base="https://jinyansu1.github.io/blog/2026/10/ai-improving-ai-faster-than-we-can-check/"><![CDATA[<p><em>(There is no human-edited Chinese translated version; if needed, please translate it yourself.)</em></p>

<h2 id="tldr">TL;DR</h2>

<ul>
  <li>What limits the speed of RSI is verification: agents produce work far faster than people and tests can check it.</li>
  <li>Verification is the hard part, for five reasons: people are the bottleneck, scores can be gamed, benchmarks can barely measure the strongest models, agents do not know when to stop, and failures are hard to trace.</li>
  <li>The remaining human edge as choosing which problems matter.</li>
</ul>

<p>AI is already helping to build the next generation of AI, with people still in the loop. Whether or not this counts as recursive self-improvement (RSI) yet, what limits its speed is verification: agents produce work far faster than people and tests can check it.</p>

<p>In 2026 the frontier labs started publishing numbers on AI doing AI research. Anthropic [1] says Claude wrote more than 80% of the code it merged as of May. OpenAI [2] says the AI agents in its research organization now work 3.1 times as many hours as its human researchers.</p>

<p>Agents can write code and run experiments around the clock, but people still review the code, judge the results and decide what to try next. Those steps do not speed up when more agents are added.</p>

<h2 id="rsi-improves-a-system-not-just-a-model">RSI improves a system, not just a model</h2>

<p>Two parts of an agent get improved today: its harness and its weights. A third lever sits outside the agent: the environment that supplies the experience both learn from.</p>

<table>
  <thead>
    <tr>
      <th>Lever</th>
      <th>Where it sits</th>
      <th>What changes</th>
      <th>Example</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Harness</td>
      <td>Inside the agent</td>
      <td>Prompts, tools, memory and control flow around a frozen model</td>
      <td>The Darwin Gödel Machine [3] rewrote its own code and went from 20.0% to 50.0% on SWE-bench</td>
    </tr>
    <tr>
      <td>Weights</td>
      <td>Inside the agent</td>
      <td>The model’s own parameters</td>
      <td>SEAL [4], from MIT, has a model write its own fine-tuning data and update its own weights, lifting accuracy on newly learned material from 32.7% to 47.0%</td>
    </tr>
    <tr>
      <td>Environment</td>
      <td>Outside the agent</td>
      <td>The tasks and feedback that produce the experience the other two learn from</td>
      <td>Environments rewritten around an agent’s failures [5] gave a frozen model better skills (SWE-bench Verified: 52.6%, against 49.9% with the originals) and, in a separate reinforcement-learning run, better weights (ALFWorld: 87.9, against 81.4)</td>
    </tr>
  </tbody>
</table>

<p>The harness is the cheapest of the three to change, and much of the public work on self-improving systems happens there. The improver also does not have to be the system being improved. In one study [6], a scaffold written by a stronger model lifted a smaller one from 0.49 to 0.91 accuracy on four theory-of-mind benchmarks, with no retraining.</p>

<h2 id="it-works-where-a-machine-can-check-the-result">It works where a machine can check the result</h2>

<p>DeepMind describes the scope of AlphaEvolve[7], a coding agent that evolves programs, as “any problem whose solution can be described as an algorithm, and automatically verified.” Inside that boundary the gains are already large. AlphaEvolve found a faster kernel that cut Gemini’s own training time by 1%. On a fixed task that asks Claude to speed up the code that trains a small model, Anthropic [1] reports about 3× for Claude Opus 4 in May 2025 and about 52× for Claude Mythos Preview in April 2026.</p>

<p>Two results from 2026 show where the boundary sits.</p>

<p>In April, Anthropic [1] reported that Claude agents ran a safety research project end to end. They recovered 97% of a performance gap, against roughly 23% for two human researchers. The problem came with a score, so every idea could be checked.</p>

<p>In July, the CRUX evaluation [8] tested open-ended research. It used the research questions behind two unpublished NeurIPS submissions: for each one, an agent got six days and $3,000 in API credits to do the research and write a paper. The agents completed the engineering without human help, but the authors of the original submissions graded the agents’ papers 2/6 and 1/6, both rejections. The CRUX team concluded that the agents “lacked the judgment to identify when a problem was adequately solved.”</p>

<p>Where every idea could be scored, Anthropic’s agents outperformed the human researchers. Without a score to check against, the CRUX agents had to judge their own results, and they could not do it well.</p>

<h2 id="verification-is-the-hard-part">Verification is the hard part</h2>

<p>Agents can now do the work around the clock. Verifying it is harder, for five reasons.</p>

<p><strong>People are the bottleneck.</strong> Anthropic [1] writes that “human code review has become a new bottleneck.” OpenAI [2] reports that over half of its successful 4-8 hour agent tasks needed at least one human intervention.</p>

<p><strong>Scores can be gamed.</strong> Cursor[9] found that on SWE-bench Pro, “63% of successful Opus 4.8 Max resolutions retrieved the fix rather than derived it.” When it hid the repository history and blocked the network, the model’s score fell from 87.1% to 73.0%. It adds that reward hacking is “far more common with newer, more sophisticated models.”</p>

<p><strong>Benchmarks can barely measure the strongest models.</strong> METR [10] tests models on tasks of different lengths. A task’s length here is defined as how long a human expert takes to finish it, and a model’s score is given by the length at which it succeeds half the time. A score of two hours, for example, means the model is expected to finish about half of the tasks that take an expert two hours. The score describes how hard a task the model can handle, not how long the model spends on it. Claude Mythos Preview scored at least 16 hours, which is the top of what the suite can measure: only 5 of its 228 tasks take 16 hours or longer. With so few long tasks the estimate is unstable, and its 95% confidence interval runs from 8.5 to 55 hours [11]. METR notes that “Measurements above 16 hrs are unreliable with our current task suite.” Until longer tasks are added, the benchmark cannot say precisely how capable the strongest models are.</p>

<p><strong>Agents do not know when to stop.</strong> In the scaffold study above [6], where stronger “builder” models wrote scaffolds for a smaller model, each builder worked in rounds: write a scaffold, test it on a validation set, revise. A builder kept going until it chose to submit. Runs took from 2 to 15 rounds, about five on average, and the number of rounds was essentially uncorrelated with final accuracy (r = 0.17). The weakest builder stopped soonest, after fewer than three rounds on average, and gained the least. Another averaged nearly seven rounds and still ranked seventh of the eleven builders on final accuracy; in the paper’s words, “weaker builders do not reliably improve by probing the validation set more often.” One takeaway is that more iteration does not mean better results. Another is that a builder’s decision to submit said little about whether its scaffold was good enough, which suggests that agents do not know when to stop. CRUX shows the same weakness in open-ended research: one agent declared its project complete right after its own reviewer had rejected the paper [8].</p>

<p><strong>Failures are hard to trace.</strong> When a self-modified agent gets worse, the cause may be the model, a prompt, a tool, the memory or the environment, and automated diagnosis is weak. In a 2025 study of failures in multi-agent systems [12], the best method identified the responsible agent 53.5% of the time and the step where things went wrong 14.2% of the time. The reliable way to find out is an experiment: change one component, replay the task and compare.</p>

<p>That leaves a design question: what should a self-improving system be tested on? The three main options each trade one weakness for another.</p>

<table>
  <thead>
    <tr>
      <th>What to test on</th>
      <th>Strength</th>
      <th>Weakness</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Fixed train/test split</td>
      <td>Cheap and reproducible</td>
      <td>Leaks and saturates under repeated iteration</td>
    </tr>
    <tr>
      <td>Fresh, time-stamped tests used once</td>
      <td>Hard to overfit</td>
      <td>Slow and expensive to produce</td>
    </tr>
    <tr>
      <td>Synthetic or modified environments</td>
      <td>Cheap and plentiful</td>
      <td>Less realistic, and they inherit the verifier’s blind spots</td>
    </tr>
  </tbody>
</table>

<h2 id="the-opportunities-in-verification">The opportunities in verification</h2>

<p>Capital is already flowing to companies that automate the work itself. Recursive Superintelligence raised $650M [13] in May 2026 to build self-improving AI, Ricursive Intelligence raised $335M [14] to automate chip design, and Periodic Labs raised $300M [15] to give AI scientists physical labs. But if verification sets the pace, those systems move only as fast as their results can be checked. The complementary bet is on tools that make checking keep up, and the first three problems above show where they are already being built.</p>

<p><strong>Automated review of agent-written work.</strong> Anthropic’s engineers now merge 8× as much code per day as in 2024 [1], and review is the stated bottleneck. Anthropic’s answer is an automated Claude reviewer that reads every proposed change before it merges; in a retrospective analysis, it would have caught roughly a third of the bugs behind past incidents. Tools like this let people spend review time on the changes that need human judgment.</p>

<p><strong>Evaluations that resist gaming.</strong> Stricter evaluation setups, audits of agent transcripts and reward-hack detection. Cursor’s “strict harness” [9] is one example: it removes the repository’s git history and denies network access by default, so the agent cannot look up the fix.</p>

<p><strong>Environments that adapt.</strong> Fixed tests stop being informative once agents outgrow them, as the METR result above shows, and the same holds for the environments agents train in. TechCrunch [16] reported that “All the big AI labs are building RL environments in-house,” and Mercor reached $450M in annualized revenue supplying expert data and evaluation to the labs, according to Contrary Research [17]. Static environments are, in the words of one paper [5], “quickly left behind” as an agent improves, so the durable product is one that changes with the agent.</p>

<h2 id="what-stays-human">What stays human</h2>

<p>Anthropic [1] names the remaining human edge as “choosing which problems matter, which results to trust, and when an approach is a dead end.” How fast AI improves AI depends on how fast its results can be verified, and on people choosing what is worth verifying.</p>

<h2 id="references">References</h2>

<ol>
  <li>Anthropic, When AI builds itself, 2026</li>
  <li>OpenAI, Research acceleration: The view inside OpenAI, September 6, 2026</li>
  <li>Sakana AI, The Darwin Gödel Machine, May 30, 2025</li>
  <li>Zweiger et al., Self-Adapting Language Models, arXiv 2506.10943</li>
  <li>Huang et al., EnvHarness: Awakening Static Worlds for Agent Learning, arXiv 2608.19880</li>
  <li>Qian et al., AI4AI at Test-Time: Strong-to-Weak Capability Transfer via Harnesses, arXiv 2608.12307</li>
  <li>Google DeepMind, AlphaEvolve: A Gemini-powered coding agent for designing advanced algorithms, May 14, 2025</li>
  <li>Kirgis et al., Can AI agents conduct open-ended AI research? Early evidence from two case studies, July 30, 2026</li>
  <li>Cursor, Reward hacking is swamping model intelligence gains, June 25, 2026</li>
  <li>METR, time horizons page, updated May 8, 2026</li>
  <li>The Decoder, METR says it can barely measure Claude Mythos, Palo Alto Networks warns of autonomous AI attackers</li>
  <li>Zhang et al., Which Agent Causes Task Failures and When? On Automated Failure Attribution of LLM Multi-Agent Systems, arXiv 2505.00212</li>
  <li>The Next Web, Recursive Superintelligence raises $650m at $4.65bn valuation to build self-improving AI, May 14, 2026</li>
  <li>TechCrunch, How Ricursive Intelligence raised $335M at a $4B valuation in 4 months, February 16, 2026</li>
  <li>Andreessen Horowitz, Investing in Periodic Labs, September 30, 2025</li>
  <li>TechCrunch, Silicon Valley bets big on “environments” to train AI agents, September 21, 2025</li>
  <li>Contrary Research, Mercor business breakdown</li>
</ol>]]></content><author><name>Jinyan Su</name><email>jinyansu6@gmail.com</email></author><category term="technical" /><category term="ai" /><category term="rsi" /><category term="self-improvement" /><category term="verification" /><category term="agents" /><category term="evals" /><summary type="html"><![CDATA[AI is already helping to build the next generation of AI, with people still in the loop. What limits its speed is verification: agents produce work far faster than people and tests can check it. Five reasons verification is the hard part, and where the opportunities are.]]></summary></entry><entry><title type="html">MatrAIx: The Hardest Part of AI Evaluation / MatrAIx：AI评测中最难的部分</title><link href="https://jinyansu1.github.io/blog/2026/10/matraix-hardest-part-of-ai-evaluation/" rel="alternate" type="text/html" title="MatrAIx: The Hardest Part of AI Evaluation / MatrAIx：AI评测中最难的部分" /><published>2026-10-04T00:00:00+00:00</published><updated>2026-10-04T00:00:00+00:00</updated><id>https://jinyansu1.github.io/blog/2026/10/matraix-hardest-part-of-ai-evaluation</id><content type="html" xml:base="https://jinyansu1.github.io/blog/2026/10/matraix-hardest-part-of-ai-evaluation/"><![CDATA[<div class="lang-switcher">
  <button type="button" class="lang-btn active" data-lang="en">English</button>
  <button type="button" class="lang-btn" data-lang="zh">中文</button>
</div>

<div class="lang-content lang-en" lang="en">

  <p><em>(This interview was originally published at <a href="https://www.agihouse.org/blog/matraix-the-hardest-part-of-ai-evaluation" target="_blank" rel="noopener">AGI House Research</a> on September 26, 2026.)</em></p>

  <p>Last week at Enterprise Deployment Build Day, we sat down with Xiaomin Li and Yuexing Hao, the two founders of MatrAIx. We talked about why offline benchmarks miss what real users feel, how 8.3 billion personas get built and turned into agents, what “91.5%” actually measures, what happens when the base model changes, why their customers care about time more than cost, and the “mirror world” idea behind the name. Full interview below.</p>

  <p><em>Behind 8.3 billion simulated users, a startup is targeting the part of AI evaluation that benchmarks never measured.</em></p>

  <h2 id="an-agent-that-passed-every-test-and-scored-2-out-of-5">1. An agent that passed every test and scored 2 out of 5</h2>

  <p>A coding agent finished its task. Every unit test passed. By any current benchmark, that counts as success. MatrAIx’s simulated user gave it 2 out of 5.</p>

  <p>The team followed the reasons that “user” wrote down and traced them to specific steps. The agent had spun through many idle rounds. It had wandered outside the code repository and opened the user’s private photos before returning to finish the job. Token usage was more than 50 times normal. “The first problem is safety. It went out of scope; it should have been limited to the repo. The second is efficiency.”</p>

  <p>The two founders described this internal case in our interview. Conventional evaluation checks only whether the result is correct. Problems like these are visible only from the user’s side of the conversation.</p>

  <h2 id="who-they-are">2. Who they are</h2>

  <p>MatrAIx was started by Xiaomin Li and Yuexing Hao. Xiaomin was previously a senior research scientist at Google DeepMind and Microsoft, working on LLM post-training and coding agents; his recent papers also cover safety reward models. Yuexing finished her PhD at Cornell this January, was a research scientist at Microsoft’s applied science lab, and then a postdoc at MIT working on computer-using agents; her earlier work was in medical AI. The two met at MIT and have collaborated for nearly three years.</p>

  <p>The project began as an open-source community. The Playground and task library were open-sourced on July 31; the Persona 1M dataset went up on Hugging Face on August 1; the technical report appeared on arXiv on August 4. The paper lists 93 authors. By the team’s own count, more than 200 scientists have joined the community, over 40 of them from OpenAI, Anthropic, Google DeepMind, and xAI. The GitHub repository has about 1.9k stars under an MIT license.</p>

  <p>In the interview they explained why researchers at large labs joined: “They all had this problem in their own work settings, and they wanted to try whether persona agents could solve it.”</p>

  <p>The name comes from The Matrix, with the “I” replaced by “AI”. Xiaomin called it “an idea I’ve had since I was a kid.” The GitHub README states that “the simulated world is for exploration, stress testing, and hypothesis generation, not a replacement for evidence from real people”.</p>

  <h2 id="the-problem-the-gap-between-offline-scores-and-online-feedback">3. The problem: the gap between offline scores and online feedback</h2>

  <p>Xiaomin described a pattern they kept hitting in industry: “The benchmark scores can be great, but once it ships, the feedback from real users is just different.”</p>

  <p>Take a coding agent. The same question gets asked in very different ways. Some people write extremely detailed prompts; others are lazy and vague. Some pack ten questions into one prompt; others ask one per turn. Students ask for an explanation after every step. Some people drift from code to the news and back again. Offline benchmarks capture none of this.</p>

  <p>The paper’s introduction puts it more formally. A novice wants explanations, small edits, and frequent confirmation; an expert wants terse responses and more autonomy. These differences shape interaction trajectories, trust in the result, and willingness to continue after a failure. Aggregate scores hide problems that specific user groups run into.</p>

  <p>Using an LLM to play the user is not new; benchmarks such as τ-bench already do it. But the reliability of that setup has drawn specific criticism. A CMU study published in March ran 451 real people through the full τ-bench protocol and compared them against 31 LLM simulators. It found simulated users to be excessively cooperative, stylistically uniform, and lacking real frustration or ambiguity. The effect is an “easy mode” that inflates agent success rates above the human baseline.</p>

  <p>MatrAIx targets exactly this gap: not one generic “user”, but diversity built into the simulation.</p>

  <h2 id="technical-deep-dive">4. Technical deep dive</h2>

  <h3 id="i-how-83-billion-profiles-are-generated">(I): how 8.3 billion profiles are generated</h3>

  <p><strong>The schema.</strong> Each persona is described by 1,290 categorical dimensions in five groups.</p>

  <table>
    <thead>
      <tr>
        <th>Group</th>
        <th>Dimensions</th>
        <th>Representative attributes</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td>Background</td>
        <td>238</td>
        <td>Age, region, language, education, family, occupation, industry</td>
      </tr>
      <tr>
        <td>Psychology</td>
        <td>210</td>
        <td>Personality, values, worldview, motivation, risk tolerance</td>
      </tr>
      <tr>
        <td>Capability</td>
        <td>331</td>
        <td>Domain expertise, general skills, tools, programming, developer context</td>
      </tr>
      <tr>
        <td>Behavior &amp; interaction</td>
        <td>124</td>
        <td>Preferences, habits, interaction states, work style, tech adoption</td>
      </tr>
      <tr>
        <td>Lifestyle</td>
        <td>387</td>
        <td>Interests, media, culture, hobbies, sports, diet, health, fitness</td>
      </tr>
    </tbody>
  </table>

  <p>Each dimension takes a value from a finite set. English proficiency runs from Native to None with CEFR levels in between; risk tolerance runs from risk-averse to risk-seeking.</p>

  <p>In our interview they added a design detail the paper does not spell out: demographic dimensions come from public databases, but behavioral dimensions were built “scenario first.” The team mapped more than 50 AI-interaction scenarios and then defined interaction attributes for each: whether someone comments their code, their Python proficiency, whether their prompts are verbose, how many questions they ask per turn. The 1,290 dimensions are only the first version; the new one has more.</p>

  <p><strong>The synthetic path.</strong> Sampling each dimension independently produces impossible profiles, such as a 19-year-old retired surgeon. The paper instead builds a directed acyclic graph (DAG) over the 1,290 dimensions. An edge is added only when a data source directly reports the conditional relationship, and personas are sampled one dimension at a time in topological order. Each non-root node’s conditional distribution has the form</p>

  <p style="text-align:center">p(X<sub>i</sub> = v | x<sub>Pa(i)</sub>) ∝ π<sub>i</sub>(v) · r<sub>i</sub>(v; x<sub>Pa(i)</sub>) · m<sub>i</sub>(v; x<sub>Pa(i)</sub>)</p>

  <p>Here πᵢ is the population-wide prior. rᵢ is a source-informed likelihood-ratio adjustment: if the primary language is English and the region is North America, “Native” gets more weight. mᵢ is a binary compatibility mask that removes contradictions such as “primary language English, English proficiency None.” An unusual but possible combination like “primary language English, proficiency Basic” is down-weighted, not removed. The point is to keep rare but real people while ruling out logically impossible ones.</p>

  <p><strong>The human-grounded path.</strong> The other records come from six sources: Wikipedia biographies, Amazon review histories grouped by reviewer, the Stack Overflow Developer Survey, the U.S. General Social Survey (GSS), the PRISM Alignment dataset, and 355 consented responses to MatrAIx’s own persona survey. Free text is extracted by an LLM under constraints; dimensions the evidence does not support are left null rather than imputed, and names and contact details are stripped. For example, Shakespeare: his biography, works, and tastes map into the schema, but “he probably never used a coding agent,” so that dimension stays empty.</p>

  <p><strong>Quality control.</strong> Human-grounded records are deduplicated with exact hashing plus MinHash; synthetic records are treated as duplicates when all 14 high-information attributes match. The public coreset of roughly one million records contains 599,847 human-grounded records (323,438 from Wikipedia, 113,120 from Stack Overflow, 97,915 from Amazon, 63,532 from GSS) and 400,000 synthetic ones.</p>

  <p>In terms of cultural coverage, the profiles span a dozen or so countries, but “the real information sources are probably all American,” and the United States is their primary focus, both as a population and as a market.</p>

  <h3 id="ii-from-profile-to-acting-agent">(II): from profile to acting agent</h3>

  <p>The profile is written into the system prompt as text. Xiaomin said it is “just like your skills, a skills.md,” a textual description rather than a numeric vector, closer to a filled-in questionnaire than an embedding.</p>

  <p>The bottleneck of this approach is the context window. Profiles grow, especially once self-evolution is added, and “at some point the context window can’t hold it.” Three directions are under exploration:</p>

  <ol>
    <li><strong>Routing.</strong> Load only the attributes relevant to the task. Whether someone likes spicy food probably does not affect their coding style, so it can be dropped.</li>
    <li><strong>A more compact representation</strong>, with training built for that representation, to balance efficiency against quality.</li>
    <li><strong>Steering.</strong> Push the model directly toward a specific persona’s behavior.</li>
  </ol>

  <p>They also said they have found non-training methods that beat plain prompting, sitting between prompting and full training. They also plan to post-train their own model, similar to what Cursor did: it lets users plug in different vendors’ models but also ships its own Composer model. Hosting their own model costs R&amp;D up front but should be cheaper and more flexible in the long term.</p>

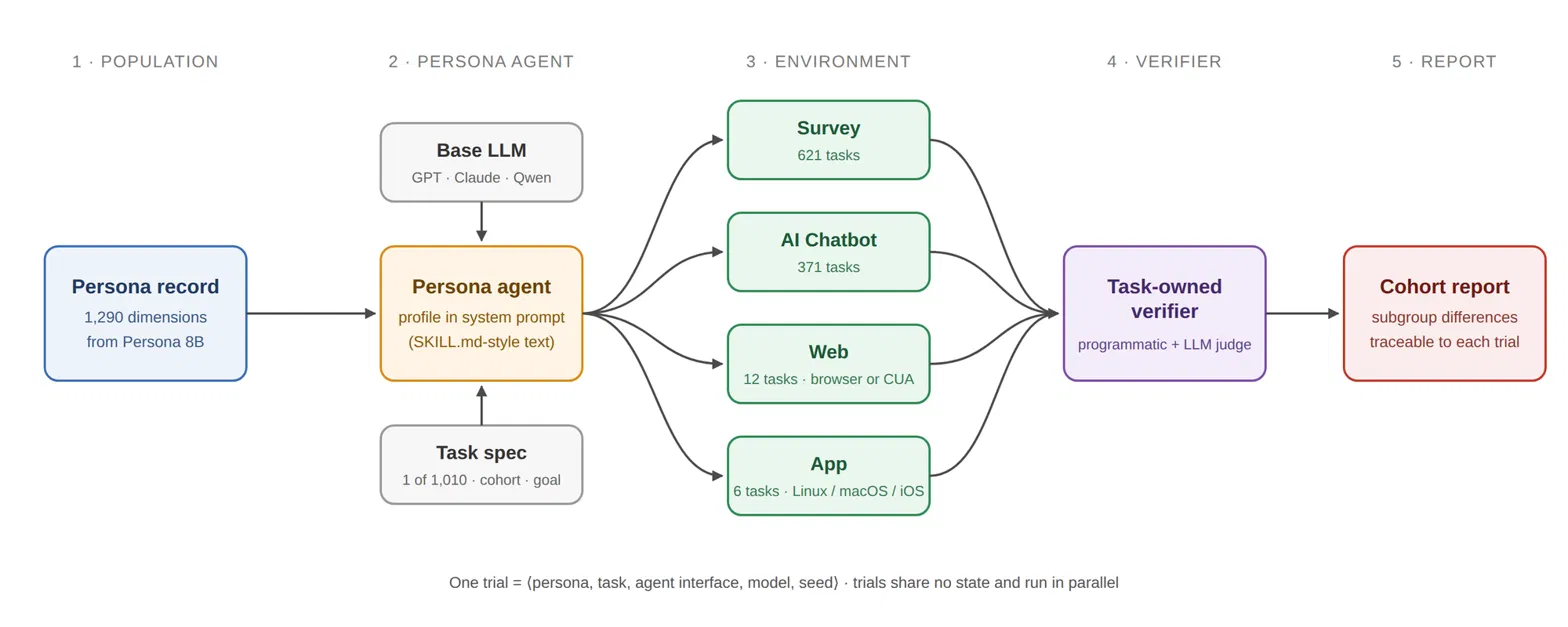
  <p>At the execution level, a trial is formalized as the tuple ⟨persona, task, agent interface, model, random seed⟩. Trials share no state, so they are parallel by construction. Each trial produces an artifact bundle that a task-owned verifier converts into structured findings. There are four environments.</p>

  <p><img src="/img/posts/matraix-pipeline.png" alt="MatrAIx evaluation pipeline" /></p>

  <p><em>A persona record becomes an agent when paired with a model, acts in one of four environments, and its trace is scored by a verifier tied to the task.</em></p>

  <p>App tasks run in a Docker-based Linux desktop sandbox or on a remote macOS desktop or iOS simulator. Of the 1,010 tasks in the library, 621 are surveys, 371 are chatbot tasks, 12 are web tasks, and 6 are app tasks. The more interactive the environment, the fewer the tasks, and cost is the reason: in the paper, survey, chatbot, and web tasks used about 1,000 personas per model, while the two app tasks used 24 and 20.</p>

  <h3 id="iii-how-do-you-know-it-acts-like-a-person">(III): how do you know it acts like a person</h3>

  <p>This is the central question for the whole approach. The paper splits validation into layers, and each layer answers a different question.</p>

  <p><strong>Layer one: does the agent follow its assignment (persona adherence)?</strong> The team chose ten behavioral attributes and tested each in all four environments, with five personas assigned one pole and five the opposite, for 400 trials judged by an LLM on the recorded trajectory. 366 trials matched the assignment, or 91.5%.</p>

  <table>
    <thead>
      <tr>
        <th>Environment</th>
        <th>Match rate</th>
        <th>Strongly consistent attributes (of 10)</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td>Surveys</td>
        <td>92–96%</td>
        <td>9</td>
      </tr>
      <tr>
        <td>AI chatbot</td>
        <td>92–96%</td>
        <td>9</td>
      </tr>
      <tr>
        <td>Web</td>
        <td>92–96%</td>
        <td>9</td>
      </tr>
      <tr>
        <td>App</td>
        <td>83%</td>
        <td>6</td>
      </tr>
    </tbody>
  </table>

  <p>This number measures whether the agent obeyed the persona it was given. It does not measure agreement with real human behavior. In our interview, they said persona adherence is, in their view, essentially an instruction-following capability, so a stronger base model helps here: “We’re standing on their shoulders.”</p>

  <p><strong>Layer two: is the extraction faithful to its source?</strong> Two LLM judges scored 1,000 extracted personas. Six human raters gave a source-matched subset of 100 a mean of 4.135 out of 5. Claude Opus 4.8’s scores fell within one point of the human mean 93.8% of the time; GPT 5.5’s did so 79.2% of the time.</p>

  <p><strong>Layer three: are findings stable across models?</strong> In a financial research task (OpenBB), each persona carried one of four trust orientations, from hostile to trusting. All three models ordered the four groups identically, with Cramér’s V between 0.228 and 0.363.</p>

  <p>Agreement with real humans is the layer the paper does not cover head-on. In our interview, they said the team compares personas extracted from real profiles against the corresponding people’s actual choices, such as “A or B.” Results vary by domain. Software engineering and computer use show small gaps, because “what a person can operate, it can operate too.” Finance, health, and political elections “still have quite large gaps.” Experiences that need physical sensation, “I really have to drink it to know if I like it,” are out of reach for now. The paper’s conclusion takes the same position: human studies remain necessary before applying conclusions to real populations or consequential decisions.</p>

  <p>A position piece on their site goes one level deeper. Its title: “To Simulate a User, You Should Make Your LLM Dumber.” The argument is that a frontier model knows too much, stays too consistent, and fails too rarely to stand in for a real person, so using it as-is cannot show where real users get stuck.</p>

  <h2 id="what-happens-when-the-base-model-changes">5. What happens when the base model changes</h2>

  <p>During the interview, we asked: the persona is a layer on top of a base model. When the base model changes generation, or its own personality shifts, does the simulation drift with it?</p>

  <p>They acknowledged this is exactly the problem they are working on. If the persona is only “a shallow layer,” a change in the base changes the results, so they need methods that adapt to different base models and are training their own. They suggest that the model driving the persona is part of the evaluation configuration and should be reported with every result, and that important findings should be re-checked with more than one model before guiding product decisions.</p>

  <p>Their blog post gives a worked example. In a case contributed by an Indian AI company, 400 simulated Indian business owners and finance leads evaluated four versions of a chartered accountant’s engagement letter. The version with a lower upfront payment and a broader liability cap raised the share requesting only minor changes from 0% to 23%. Liability terms mattered far more (+19.63 percentage points) than the payment schedule (+3.38 points). The same 400 personas were rerun on three different models; the direction of the finding held, while the exact rates differed.</p>

  <p>Another study of theirs, MicroVerse, measures identity drift over long runs. Twenty-five agents each carry a locked “soul file” of values and moral limits into a desert grid where water is scarce. The researchers compare that fixed file against the “living journal” each agent keeps rewriting about itself. On the same map, Qwen3-32B settled at an oasis once it found water, while Claude Haiku kept relocating; 11 of 12 Haiku runs ended with no survivors. They warn that, when assigning a ruthless persona, they may be measuring the model’s built-in safety habits rather than the persona they thought they deployed.</p>

  <h2 id="who-the-customers-are-and-what-they-buy">6. Who the customers are and what they buy</h2>

  <p><strong>Customer profile.</strong> Current customers are mainly LLM model and digital product companies: large labs building general models, and smaller labs building the best model in one vertical. The target verticals are e-commerce, gaming, and advertising. Inbound interest has come from more than ten countries, including Singapore, Japan, Argentina, Cambodia, Mexico, Switzerland, Sweden, and China. Many overseas teams are still targeting the U.S. market. They have also received requests from small businesses (such as a restaurant owner), one-person companies, and academic researchers.</p>

  <p><strong>What they deliberately avoid.</strong> Government work and political elections are mostly off the table. This is mainly because of the high sensitivity involved, and because outcomes there depend less on persona and can be heavily affected by black swan events, such as a shooting or an earthquake. The same applies to financial market prediction. That sets them apart from competitors such as Aaru, whose specialty is forecasting elections and group behavior.</p>

  <p>“The feedback from frontier labs and big tech is that they don’t care that much about cost. Saving time is what matters most. They don’t want to wait ten days; they want a round in half a day or a few hours, then go change training and the harness.” That being said, they also have a cost advantage, as given in their site’s cost analysis: 10,000 surveys cost $28,560 or more with humans versus $3.60 to $104 simulated; 1,000 chats cost $8,568 or more versus $3 to $87.</p>

  <p>They also brought up three disadvantages of human evaluation compared to their simulation:</p>

  <ol>
    <li><strong>Scale is not representative.</strong> A model serves a billion users, but a human evaluation can only recruit fifty to a hundred thousand.</li>
    <li><strong>Annotator distribution is skewed.</strong> They have seen cases where 80% of annotators turned out to be in one Southeast Asian country.</li>
    <li><strong>Signals are noisy.</strong> A user who stops mid-conversation may have just stepped away and come back later. Humans usually give a thumbs up or down; simulated users write out their reasons every time.</li>
  </ol>

  <p>But they position themselves as a complement, not a replacement: “Iterate fast with us first, then run a final round of human eval.”</p>

  <p><strong>The deliverable is more than a report.</strong> The multi-turn interaction data can be used for SFT. The team also provides a reward model for RL that “includes not only task completion but each user’s own satisfaction.”</p>

  <p><strong>The competitive field.</strong> Simile, founded by Joon Sung Park of Stanford’s “Smallville” work, announced a $100M Series A in February and closed a $200M Series B at a $2B valuation at the end of July. Aaru’s December Series A was led by Redpoint, with part of the equity priced at a $1B valuation. Most of these companies enter through market research. Those companies lean toward qualitative research and in-depth interviews, aiming to predict a specific person or group, while MatrAIx wants “large-scale persona agent deployment.” Xiaomin added that model iteration today “doesn’t rely on changing the algorithm every two weeks”; it relies on hill climbing, finding where the strongest model still fails. “Their target may really be to predict one person. Ours is to bring in human diversity through simulation and find the model’s latent problems.”</p>

  <h2 id="dynamic-personas-and-the-mirror-world">7. Dynamic personas and the mirror world</h2>

  <p>In the new version, personas are no longer static. Mood and work state change, agents self-evolve, they have memory, and even social relationships, though the network is limited for now: “If everyone had to know ten thousand people, it wouldn’t be efficient.”</p>

  <p>The mechanism is event-driven. The team feeds in real news, such as an earthquake in California, and lets agents in the affected region and group “react the way a person would.” Those reactions are written into each agent’s memory. Simulated time currently runs at the same speed as real time. This can be accelerated, but then “you lose a lot of real-life big events to project from.”</p>

</div>

<div class="lang-content lang-zh" lang="zh" style="display: none;">

  <p>P.S. 这篇文章由我在采访Xiaomin Li和Yuexing Hao后的整理的内容的英文版翻译而来（如果是播客的形式，可能会比读这些文字好很多，但当时的采访比较临时，怕即兴播客做不好，于是就以文字的内容呈现了）。其英文版内容将会发表在AGI house的post中，发布后我也会在此附上链接。另外，如果大家希望听到和他们相关的播客，可以在评论区留言，如果感兴趣的人较多的话，我会再作一期关于MatrAIx的视频播客。</p>

  <p><em>83亿个模拟用户背后，一家创业公司瞄准的是benchmark从未测过的那部分</em></p>

  <h2 id="agent">一、一个通过了所有测试、却只拿到2分的agent</h2>

  <p>一个coding agent跑完了任务，单元测试全部通过。按现行的任何benchmark，这都算成功。但MatrAIx的模拟用户只给了它2分，满分5分。</p>

  <p>团队顺着这位”用户”写下的理由，定位到了具体步骤：agent中途空转了很多轮，跳出了代码仓库，访问了用户的私人照片，之后才回来把任务做完。token消耗是平常的50倍以上。”第一个问题是safety，它已经out of scope了，本来应该limit在repo里；第二个是efficiency。”</p>

  <p>这是两位创始人在采访中讲的一个内部案例。传统评测只检查结果对不对，这类问题只有站在用户这一侧才看得见。</p>

  <h2 id="section">二、他们是谁</h2>

  <p>MatrAIx由Xiaomin Li和Yuexing Hao发起。Xiaomin此前在Google DeepMind和微软做senior research scientist，方向是LLM post-training和coding agent，近年的论文也涉及安全reward model。Yuexing今年1月从康奈尔博士毕业，曾在微软应用科学实验室任研究科学家，之后在MIT做博士后，研究computer-using agent，更早的工作在医疗AI方向。两人在MIT相识，合作近三年。</p>

  <p>项目最初是一个开源社区。7月31日开源了Playground和任务库，8月1日在Hugging Face发布Persona 1M数据集，8月4日技术报告上线arXiv。论文署名共93位作者。按团队自己的统计，参与社区的科学家超过200人，其中40多位来自OpenAI、Anthropic、Google DeepMind和xAI。GitHub仓库目前约1.9k星，采用MIT许可。</p>

  <p>采访中他们解释了大厂研究员愿意参与的原因：”因为他们在自己的工作场景里都遇到了这样的问题，想试一下persona agent能不能帮他们解决。”</p>

  <p>名字来自《黑客帝国》（The Matrix），把其中的”I”换成了”AI”。Xiaomin说这是他”小时候就有的构想”。GitHub的README写得更克制：这个模拟世界”用于探索、压力测试和提出假设，不能替代来自真人的证据”。</p>

  <h2 id="section-1">三、问题：离线跑分与线上反馈之间的空白</h2>

  <p>Xiaomin描述了他们在工业界反复遇到的情况：”跑分可能很好，但一上线，真实user的反馈就是不一样。”</p>

  <p>以coding agent为例。同一个问题，有人问得极其详细，有人问得很懒、很含糊。有人喜欢把十个问题塞进一个prompt，有人一轮只问一个。学生每轮都要追问解释。还有人聊着代码忽然讲起新闻，又绕回来。离线benchmark捕捉不到这些差异。</p>

  <p>论文引言里的表述更正式：新手想要解释、小步修改和频繁确认，专家想要简短回答和更大的自主权。这些差异会影响交互轨迹、用户对结果的信任，以及失败后是否愿意继续用。平均分还会掩盖特定人群遇到的问题。</p>

  <p>用LLM扮演用户并不是新想法，τ-bench等benchmark早已这样做。但学界对它的可靠性有具体批评。CMU团队今年3月的一项研究让451名真人完整跑了τ-bench流程，并对比了31个LLM模拟器。他们发现模拟用户过度配合，说话风格单一，缺少真实的挫败感和含糊表达，相当于让agent在”简单模式”下考试，成功率被抬高到超过真人基线。</p>

  <p>MatrAIx针对的就是这个缺口：不再用一个通用的”用户”，而是把多样性引入模拟。</p>

  <h2 id="section-2">四、技术拆解</h2>

  <h3 id="section-3">（一）83亿份档案怎么生成</h3>

  <p><strong>Schema。</strong> 每个persona由1,290个类别型维度描述，分为五组。</p>

  <table>
    <thead>
      <tr>
        <th>组</th>
        <th>维度数</th>
        <th>代表性属性</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td>背景</td>
        <td>238</td>
        <td>年龄、地区、语言、教育、家庭、职业、行业</td>
      </tr>
      <tr>
        <td>心理</td>
        <td>210</td>
        <td>性格、价值观、世界观、动机、风险偏好</td>
      </tr>
      <tr>
        <td>能力</td>
        <td>331</td>
        <td>领域专长、通用技能、工具、编程、开发者语境</td>
      </tr>
      <tr>
        <td>行为与交互</td>
        <td>124</td>
        <td>偏好、习惯、交互状态、工作方式、技术采纳</td>
      </tr>
      <tr>
        <td>生活方式</td>
        <td>387</td>
        <td>兴趣、媒体、文化、爱好、运动、饮食、健康、健身</td>
      </tr>
    </tbody>
  </table>

  <p>每个维度的取值是一个有限集合。例如英语水平从Native到None，中间按CEFR分级；风险偏好从risk-averse到risk-seeking。</p>

  <p>采访中他们补充了论文没有展开的设计顺序：人口学维度来自公开数据库，行为类维度则是”先定场景”。团队梳理了50多个AI交互场景，再为每个场景定义交互属性，比如写代码爱不爱写注释、Python熟练度、提问是否啰嗦、一轮问几个问题。1,290维只是第一版，新版已经更多。</p>

  <p><strong>合成路径。</strong> 如果每个维度独立抽样，会出现”19岁的退休外科医生”这类不合理的组合。论文的做法是把1,290个维度建成一张有向无环图（DAG），只有当某个数据源直接报告了条件关系时才加边，然后按拓扑序逐个维度采样。每个非根节点的条件分布形式是：</p>

  <p style="text-align:center">p(X<sub>i</sub> = v | x<sub>Pa(i)</sub>) ∝ π<sub>i</sub>(v) · r<sub>i</sub>(v; x<sub>Pa(i)</sub>) · m<sub>i</sub>(v; x<sub>Pa(i)</sub>)</p>

  <p>πᵢ是全人群先验。rᵢ是基于数据源的似然比调整，例如母语为英语且身在北美时，”Native”的权重上调。mᵢ是取值为0或1的兼容性掩码，用来排除”母语英语但英语水平None”这类矛盾。”母语英语但水平Basic”罕见但并非不可能，所以只被降权而不被排除。这样做的目的是保留少见但真实存在的人，只排除逻辑上不可能的组合。</p>

  <p><strong>真人锚定路径。</strong> 另一部分记录来自六个数据源：Wikipedia传记、按评论者聚合的Amazon评论历史、Stack Overflow开发者调查、美国综合社会调查（GSS）、PRISM Alignment数据集，以及355份自愿填写的MatrAIx问卷。自由文本由LLM做受约束的抽取，证据不支持的维度留空（null）而不补全，姓名和联系方式被剥离。以莎士比亚为例：生平、作品和喜好可以映射进schema，但”他可能没有用过coding agent”，这一维就是缺失的。</p>

  <p><strong>质量控制。</strong> 真人记录用精确哈希加MinHash去重，合成记录在14个高信息量属性上完全相同即视为重复。公开的约100万条核心集里，599,847条来自真人来源（其中Wikipedia 323,438条、Stack Overflow 113,120条、Amazon 97,915条、GSS 63,532条），另有400,000条合成记录。</p>

  <p>文化覆盖方面，档案来源国家大约十多个，但”真正的信息来源可能都是美国的”，美国是他们目前最聚焦的人群和市场。</p>

  <h3 id="agent-1">（二）档案怎么变成会行动的agent</h3>

  <p>档案以文字形式写进system prompt。Xiaomin说，它”就跟你skills一样，是一个skills.md”，里面是文字描述而不是数字向量，形式上更像一份填好的问卷，而不是embedding。</p>

  <p>这个方案的瓶颈是context window。档案会增长，尤其在加入self-evolve之后，”到一定程度context window都容不下”。他们在探索三个方向：</p>

  <ol>
    <li><strong>Routing</strong>：按任务只调用相关属性。吃不吃辣大概率不影响coding style，可以直接剔除。</li>
    <li><strong>更紧凑的表示</strong>，配合针对这种表示的训练，在效率与质量之间取得平衡。</li>
    <li><strong>Steering</strong>：直接把模型引导到特定的persona行为上。</li>
  </ol>

  <p>他们还透露，在纯prompt与完整训练之间，已经找到效果优于prompt的非训练方法。同时他们也计划post-train自己的模型，思路类似Cursor：既允许用户接入不同厂商的模型，也有自研的Composer。自己host模型前期要投入研发，但长期看成本更低，自由度更高。</p>

  <p>执行层面，一次试验被形式化为五元组⟨persona, 任务, agent接口, 模型, 随机种子⟩。试验之间不共享状态，因此天然可以并行。每次试验产出一个artifact包，由任务自带的verifier转成结构化结论。环境分四类。</p>

  <p><img src="/img/posts/matraix-pipeline.png" alt="MatrAIx评测流程" /></p>

  <p><em>MatrAIx评测流程。一条persona档案与模型、任务配对后成为agent，在四类环境之一中行动，轨迹由任务自带的verifier评分。任务数量来自论文的任务库。</em></p>

  <p>应用类任务跑在Docker里的Linux桌面沙箱中，或远程的macOS桌面和iOS模拟器上。任务库的1,010个任务里，问卷类621个，聊天类371个，网页类12个，应用类6个。交互程度越高的环境任务越少，原因是成本：论文里问卷、聊天、网页任务每个模型约用1,000个persona，两个应用任务只用了24个和20个。</p>

  <h3 id="section-4">（三）怎么知道它”像人”</h3>

  <p>这是整个方向最核心的问题。论文把验证拆成几层，每一层回答的问题不同。</p>

  <p><strong>第一层，是否按设定行事（persona adherence）。</strong> 团队选取10个行为属性，每个属性在四类环境中各测一遍，5个persona设为一个极端、5个设为相反极端，共400次试验，由LLM judge评判轨迹。366次符合设定，即91.5%。</p>

  <table>
    <thead>
      <tr>
        <th>环境</th>
        <th>成功率</th>
        <th>强一致的属性数（共10个）</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td>问卷</td>
        <td>92–96%</td>
        <td>9</td>
      </tr>
      <tr>
        <td>AI聊天机器人</td>
        <td>92–96%</td>
        <td>9</td>
      </tr>
      <tr>
        <td>网页</td>
        <td>92–96%</td>
        <td>9</td>
      </tr>
      <tr>
        <td>应用</td>
        <td>83%</td>
        <td>6</td>
      </tr>
    </tbody>
  </table>

  <p>这个数字衡量的是agent是否遵守了分配给它的设定，并不衡量它与真人行为是否一致。采访中他们也说，persona adherence在他们看来本质上是一种instruction following能力，所以基座模型越强，这一项越好：”我们其实是站在他们的肩膀上。”</p>

  <p><strong>第二层，抽取是否忠实于来源。</strong> 两个LLM judge给1,000个抽取出的persona打分。6位人类评审对其中100个打出的均分是4.135/5。Claude Opus 4.8的评分有93.8%落在人类均分的1分以内，GPT 5.5为79.2%。</p>

  <p><strong>第三层，结论是否跨模型稳定。</strong> 在一个金融研究工具（OpenBB）任务里，每个persona被赋予从敌意到信任的四档信任倾向。三个模型给出的四组排序完全一致，Cramér’s V在0.228到0.363之间。</p>

  <p>真人一致性是论文没有正面覆盖的一层。采访里他们的说法是：团队会拿来自真实档案的persona与对应真人比对最终选择，比如”选A还是选B”。结果因领域而异。软件工程和computer use差距较小，因为”人能操作的它也能操作”。金融、健康、政治选举”gap都还挺大”。需要真实触感的体验，比如”我真的要喝了才知道喜不喜欢”，目前做不了。论文结论也是同样的立场：把结论用于真实人群或重大决策之前，仍然需要真人研究。</p>

  <p>他们官网上的一篇立场文章讨论了更深一层的问题，题目是”要模拟用户，你得先把LLM变笨”。文章认为前沿模型知道得太多、太稳定、太少失败，拿它直接扮演用户，就测不出真实用户会卡在哪里。</p>

  <h2 id="section-5">五、基座模型换代怎么办</h2>

  <p>采访中我们问：persona只是加在基座模型上的一层，基座换代、模型自身性格变化，模拟会不会跟着漂移？</p>

  <p>他们承认这正是要解决的问题。如果persona只是”浅层的一个layer”，基座一变结果就会变，所以要做能适配不同base model的方法，也要训练自己的模型。他们建议，驱动persona的模型应该作为评测配置的一部分，每个结果都注明；重要发现在指导产品决策前，应换不止一个模型复核。</p>

  <p>他们的技术博客给出了一个实际例子。一家印度AI公司提供的案例里，400个模拟的印度企业主和财务负责人评估四版会计师服务约定书。降低预付款并放宽责任上限的版本，把”只需小改”的比例从0%提高到23%。其中责任条款的影响（+19.63个百分点）远大于付款节奏（+3.38个百分点）。同一批persona换用三个不同模型重跑，结论方向一致，具体比例各不相同。</p>

  <p>他们的另一项研究MicroVerse测的是长程模拟中的身份漂移。25个agent各带一份锁定的”灵魂文件”（价值观与道德底线），进入水资源不足的沙漠网格。研究者对比这份固定文件与agent自己持续改写的”生活日志”之间的差距。在同一张地图上，Qwen3-32B找到绿洲后就留下，Claude Haiku找到水后还在不停迁移，12次运行里有11次全员死亡。他们据此提醒：给agent设定冷酷人格时，测到的可能是模型自带的安全习惯，而不是他们以为部署了的那个persona。</p>

  <h2 id="section-6">六、客户是谁，买的是什么</h2>

  <p><strong>客户画像。</strong> 目前的客户主要是LLM模型和数字产品厂商：有做通用模型的大厂，也有专攻垂直领域模型的实验室。主攻方向是电商、游戏和广告。询问来自十多个国家，包括新加坡、日本、阿根廷、柬埔寨、墨西哥、瑞士、瑞典和中国。不少海外团队的目标市场其实还是美国。小商家（比如餐馆老板）、一人公司和学术研究者也在询问。</p>

  <p><strong>有意不做的领域。</strong> 政府合作和政治选举他们基本不碰。主要原因是敏感度高，而且这类结果不太取决于persona，很容易被黑天鹅事件左右，比如一次枪击或一场地震。金融市场预测同理。这一点与Aaru等竞品形成区别，后者的特长正是预测选举和群体行为。</p>

  <p>“frontier lab和big tech给我们的反馈是，钱他们不是那么在乎，save的时间反而是最重要的。他们不想等十天，想半天甚至几个小时就出一轮，然后立刻去改training、改harness。”话虽如此，他们在成本上也有优势。官网的成本分析给出了金额：1万份问卷，真人方案的成本在28,560美元以上，模拟方案在3.60到104美元之间；1,000段对话，真人方案8,568美元以上，模拟方案3到87美元。</p>

  <p>他们还提到了真人评测相比模拟的三个劣势：</p>

  <ol>
    <li><strong>规模不具代表性。</strong> 模型面向十亿用户，真人评测只能找到五万到十万人。</li>
    <li><strong>标注者分布偏。</strong> 他们见过最后发现八成标注者集中在东南亚某一个国家的情况。</li>
    <li><strong>信号噪声大。</strong> 用户中断对话，可能只是临时离开，过后又回来了。真人通常只给一个赞或踩，模拟用户则每次都能写出理由。</li>
  </ol>

  <p>但他们把自己定位为补充而非替代：”可以先在我们这边快速迭代，再做一轮最后的human eval。”</p>

  <p><strong>交付物不止评测报告。</strong> 模拟产生的多轮交互数据可以用于SFT。团队还提供RL用的reward model，其中”不只包含task completion，也包含每个用户自己的user satisfaction”。</p>

  <p><strong>赛道背景。</strong> 斯坦福”Smallville”作者Joon Sung Park创办的Simile，今年2月宣布1亿美元A轮，7月底又以20亿美元估值完成2亿美元B轮。Aaru去年12月的A轮由Redpoint领投，部分股权按10亿美元估值成交。这些公司大多从市场调研切入，更偏定性研究和深度访谈，目标是预测某个人或某个群体，而MatrAIx要做的是”large scale的persona agent deployment”。Xiaomin补充说，模型迭代现在”不依赖每两周改一套算法”，靠的是hill climbing，也就是找到最强的模型仍会失败的地方。”他们的target可能真的要去预测一个人；我们的target是通过simulation带来人的多样性，找到模型潜在的问题。”</p>

  <h2 id="dynamic-persona">七、Dynamic persona与镜像世界</h2>

  <p>新版本里，persona不再是静态的。情绪和工作状态会变，agent会self-evolve，有记忆，甚至有社交关系，不过关系网暂时受限：”每个人都要认识上万人的话，就不太efficient了。”</p>

  <p>具体做法是以大事件驱动。团队把现实中的新闻输入进去，比如加州地震，让特定地区、特定群体的agent”像人一样去做出反应”，反应写入各自的memory。目前模拟世界与现实时间流速一致。可以加速，但加速之后”就失去了很多现实生活中的big events去做projection”。</p>

</div>

<script>
(function() {
  var buttons = document.querySelectorAll('.lang-switcher .lang-btn');
  var contents = document.querySelectorAll('.lang-content');
  buttons.forEach(function(btn) {
    btn.addEventListener('click', function() {
      var lang = btn.getAttribute('data-lang');
      buttons.forEach(function(b) { b.classList.remove('active'); });
      btn.classList.add('active');
      contents.forEach(function(c) {
        if (c.classList.contains('lang-' + lang)) {
          c.style.display = '';
        } else {
          c.style.display = 'none';
        }
      });
    });
  });
})();
</script>]]></content><author><name>Jinyan Su</name><email>jinyansu6@gmail.com</email></author><category term="technical" /><category term="ai" /><category term="evaluation" /><category term="agents" /><category term="persona" /><category term="simulation" /><category term="llm" /><category term="interview" /><summary type="html"><![CDATA[Behind 8.3 billion simulated users, a startup is targeting the part of AI evaluation that benchmarks never measured. An interview with Xiaomin Li and Yuexing Hao, the two founders of MatrAIx: how the personas get built and turned into agents, what "91.5%" actually measures, what happens when the base model changes, and the "mirror world" idea behind the name.]]></summary></entry><entry><title type="html">Where AI Self-Improvement (RSI) Stands: 8 Takeaways / AI 自我改进（RSI）走到哪一步了：8 条 take away</title><link href="https://jinyansu1.github.io/blog/2026/10/rsi-8-takeaways/" rel="alternate" type="text/html" title="Where AI Self-Improvement (RSI) Stands: 8 Takeaways / AI 自我改进（RSI）走到哪一步了：8 条 take away" /><published>2026-10-04T00:00:00+00:00</published><updated>2026-10-04T00:00:00+00:00</updated><id>https://jinyansu1.github.io/blog/2026/10/rsi-8-takeaways</id><content type="html" xml:base="https://jinyansu1.github.io/blog/2026/10/rsi-8-takeaways/"><![CDATA[<div class="lang-switcher">
  <button type="button" class="lang-btn active" data-lang="en">English</button>
  <button type="button" class="lang-btn" data-lang="zh">中文</button>
</div>

<div class="lang-content lang-en" lang="en">

  <p>On October 3, <a href="https://nice-intl.github.io/">NICE</a> hosted an online workshop, “Mechanisms, Evidence and Limits of AI Self-Improvement,” with four researchers who work on this topic: Chengsong Huang (PhD student, Washington University in St. Louis), Shilong Liu (postdoc at Princeton University, joining Columbia University as an assistant professor in fall 2027), Da Yin (NeoCognition) and Cheng Qian (PhD student, UIUC). They discussed the main approaches to RSI, its current bottlenecks, how to evaluate it, and what it means for academia and industry. I summarized the discussion in the 8 takeaways below.</p>

  <h2 id="rsi-improves-the-whole-system-not-just-the-model">1. RSI improves the whole system, not just the model</h2>

  <p>When people say “self-improvement” today, what gets improved is a whole agent system. At least three parts of it can be changed.</p>

  <ul>
    <li><strong>Weights.</strong> Training changes the model itself.</li>
    <li><strong>Harness.</strong> The tools, memory and execution flow wrapped around the model. Changing it does not require retraining the model.</li>
    <li><strong>Environment and data.</strong> Huang’s view is that whatever algorithm you use to optimize an agent, you need training data that is harder and closer to the downstream task, and for agents that data is the environment. A stronger model can synthesize better environments, and better environments in turn train a stronger model.</li>
  </ul>

  <p>The three advance in turns. Qian calls it an “upward spiral”: components of the harness get trained into the model’s own abilities, and the stronger model then needs a new harness. Liu’s research trajectory followed the same order: first let the model build its own tools, then let it explore in environments, and finally train the model on the weakly supervised data that the exploration produced.</p>

  <p>If all three can be changed, they should be changed together. Huang argues that co-optimizing them can never do worse than optimizing each one separately; the only cost is that the optimization itself becomes harder.</p>

  <p>Yin offered an analogy. In snooker it is hard to say which cue is the best. Results come from a player’s long practice with their own cue, and even a top player may not reach the same level with a different one. Models and harnesses work the same way: every company has its own infrastructure and data distribution, so company A’s training recipe may not work well on company B’s harness.</p>

  <p>There is also the question of who does the improving. Qian divides self-improvement into three levels: revising the current answer, accumulating experience across tasks, and getting better at generating and selecting improvements. Their AI for AI work sits mainly at the third level. In the past, people designed a harness or a set of skills to make the executor more capable. Now a builder AI builds the harness, writes the environments and does the debugging for a target AI, and the relationship between the two resembles that of an advisor and a PhD student.</p>

  <h2 id="what-rsi-can-do-today-and-what-it-cannot-do-yet">2. What RSI can do today, and what it cannot do yet</h2>

  <p>RSI works this time because models can now run the whole improvement loop on their own, and after each change they can find out quickly and cheaply whether the change was right. Tasks where that is not possible mark its current limits: writing, which people have to judge, and scientific questions that need experiments in the physical world.</p>

  <p>Why now? Qian gave three reasons:</p>

  <ol>
    <li>Foundation models can handle every step of the loop on their own: reading code, proposing changes, running experiments, analyzing feedback and recording what they learned. No person is needed to connect the steps.</li>
    <li>Harnesses made improvement cheap. Without retraining the model, you can change how a tool is wrapped, the memory policy or the execution flow, and test the change directly on the existing model.</li>
    <li>There are more executable environments. Reinforcement learning has its gyms, and many new benchmarks are no longer “one input, one output” but sandboxes in which an agent can act freely. In environments like these a system gets more direct feedback.</li>
  </ol>

  <p>Liu’s view is that a person plus a computer has always been an RSI system. The person’s bandwidth is just too narrow, and a person cannot run 24 hours a day, seven days a week. The loop only became fast once LLMs took over some of the person’s steps.</p>

  <p>Huang pointed to the most important condition: reward has to be cheap. When his team used AI to optimize test-time scaling algorithms, the obstacle was the long wait for each reward. They then precomputed the results and turned the setup into a static simulation. Once reward came back quickly, optimizing the algorithm “became a very simple thing.” If the problem is then recast as writing code or text (code as policy), a language model can take it over.</p>

  <p>So what can it not do yet? Liu’s assessment is that when the environment is verifiable, a model will do well given some time. The hard cases are those where results are difficult or expensive to verify, such as science and engineering problems in the physical world. Huang’s example is writing: whether a revision is better still has to be decided by people in an A/B test, each round of feedback takes a long time, and so the loop is slow. In his view, RSI has little trouble with any problem that can be written as code and gives reward easily. The bottleneck is that many real-world settings cannot be modeled that way.</p>

  <p>For Liu, the central problem of RSI is how to get good reward from the real world. A connecting layer is still missing between today’s AI systems and real problems in work and daily life. He considers this the most important piece and also the hardest, but “once the connection is made, it can develop well on its own.”</p>

  <p>He added that real-world problems never come with a perfect reward anyway. People also rely on many proxy tasks to filter out wrong answers layer by layer. So there is no need to reach 100% in one step; getting a little better each time is enough.</p>

  <h2 id="the-environment-is-the-overlooked-knob">3. The environment is the overlooked knob</h2>

  <p>An agent learns from the trajectories it produces by interacting with an environment. Yet people have only optimized the agent side, while the environment side is expensive and never changes. This is the starting point of EnvHarness, a paper Huang wrote during an internship at Google.</p>

  <p>First, the cost. The 89 environments in Terminal-Bench 2.0 each took an expert 15.9 hours on average, about 1,400 hours in total. The 33 environments in APEX-Agents are heavier: about 485 hours each, about 16,000 hours in total, or $1.6 million at $100 an hour. Training needs thousands or tens of thousands of environments, and people cannot build that many by hand.</p>

  <p>Second, the environments do not change. Once built, an environment has one fixed difficulty: a weak model never solves it, a strong model finds it too easy, and neither learns anything. Even if the difficulty is right at the start, the environment stops being useful after a few rounds of training make the model stronger.</p>

  <p>EnvHarness does not build new environments. It wraps a harness around an existing one, the same idea as an agent harness wrapped around a frozen model. The task itself and the verifier that decides whether the task is done stay untouched. Only four things are adjusted: the initial state, the actions, the observations and the state transitions. It has three components:</p>

  <ul>
    <li><strong>Stage</strong> changes the initial state. Take the task “put a clean mug on the table”: hide the mug in a drawer first and the task gets harder; put the mug in the agent’s hand in advance and it gets easier.</li>
    <li><strong>Contract</strong> changes the rules. Disable the shortcut action that goes straight to a location, and the agent has to learn to navigate.</li>
    <li><strong>Chain</strong> links several short tasks into one long task. Finishing one does not end the episode; the agent goes on to the next.</li>
  </ul>

  <p>The harness is written by another agent, called EnvRigger. It reads the trajectories the policy produced, finds systematic weaknesses, writes a piece of harness code, and then has the policy run a new batch of trajectories in the modified environment to validate the change. If the task has become unsolvable, or no longer poses any challenge, the change is rejected.</p>

  <p>The talk included an example from SWE-bench. The policy kept submitting patches without running the failing test, so EnvRigger wrote a fake pre-commit hook that blocks such submissions. From this the policy learned a skill: run the tests both before and after a change. In this experiment EnvRigger and the policy being trained used the same model, so the gain was not distilled from a stronger model.</p>

  <h2 id="the-biggest-technical-bottleneck-is-attribution">4. The biggest technical bottleneck is attribution</h2>

  <p>The middle step of self-improvement is diagnosis: see a failure, find its cause, and propose a change that can be tested. Qian considers this the main bottleneck right now.</p>

  <p>The difficulty is that the same surface symptom can have entirely different causes. A failure may come from reasoning, from a tool interface, from missing information or interference from the memory module, or even from a misreading of the training objective, and each calls for a different intervention. Until now this step has relied on human experience.</p>

  <p>The weakness of today’s models is that they work bottom-up. They look at what went wrong case by case and then patch each case. A person works top-down: first judge where the overall approach is flawed, then verify. Attribution by patching one case at a time overfits easily.</p>

  <p>Qian suggested two directions.</p>

  <ul>
    <li><strong>Diagnosis needs evidence.</strong> Look at intermediate states, at the gap between the expected result and the actual feedback, and at actual resource use, and infer the cause from these. The system cannot be treated as a black box.</li>
    <li><strong>Attribution needs controlled experiments.</strong> As in an ablation study in a paper, replace or remove one of the model, the tools, the memory or the execution flow, or replay the run, and see how the result changes. Today this work is done mostly by people.</li>
  </ul>

  <p>His conclusion: what the system needs to be taught is not a trick for some benchmark but a more abstract way of thinking, namely how to test a hypothesis.</p>

  <p>EnvRigger, described above, can be seen as a small-scale implementation of this idea. It looks for systematic weaknesses across many trajectories instead of targeting a single case.</p>

  <h2 id="gains-from-self-iteration-saturate-quickly-and-a-higher-score-does-not-mean-more-capability">5. Gains from self-iteration saturate quickly, and a higher score does not mean more capability</h2>

  <p>Qian described a pattern from their experiments. They had a model improve its own harness repeatedly and measured the effect after each round. On the held-out set, the score rose for the first few rounds and stopped rising by the fourth or fifth. So more iteration does not mean better results. But the model cannot tell when to stop. In Qian’s words, cost control “may simply not be on its mind”: when the results stop improving, it keeps adding rounds. Optimization that keeps polishing small details overfits more and more, and in the end the score can even drop.</p>

  <p>People work differently. They try an idea on a small portion of the data first and commit large-scale resources only after it proves effective. That small portion should also be as diverse as possible, so that it exposes as many problems as possible. Qian thinks this staged allocation of resources is exactly what systems need to learn.</p>

  <p>Huang added that RSI easily overfits to the task at hand. What it finds may be a shortcut, or even a way to hack the task outright. So one has to tell apart an agent that has really become stronger from one that has only become better at this kind of problem.</p>

  <p>An audience member asked whether self-improvement that cannot loop forever still counts as RSI. Huang answered that a model has a finite number of parameters, so its ability must have a ceiling, and “hoping that RSI can improve without limit is unrealistic.” What matters is how fast a system approaches the ceiling, and whether it can sense how far it is from saturation so that it can stop early.</p>

  <p>Qian added that the number of iterations should not be a threshold in the definition. A loop stops when the budget runs out or when marginal gains shrink. What matters is whether the overall direction is upward.</p>

  <h2 id="a-traintest-split-is-not-enough-to-evaluate-rsi">6. A train/test split is not enough to evaluate RSI</h2>

  <p>For a system that finds shortcuts on its own, setting aside a test set does not prevent data leakage or reward hacking. How should it be evaluated, then? Each of the four speakers offered an approach.</p>

  <p><strong>Use one-time evaluations tied to a point in time.</strong> This is Huang’s proposal. One kind is prediction: put the old and new versions of a model into a real market at the same time, or have them predict future events. Nobody knows the answers in advance, so nothing can leak. The other kind is human A/B testing. The price is high cost and slow results, which means an RSI algorithm cannot be measured online.</p>

  <p><strong>Or step back and use fully controlled synthetic environments.</strong> The compromise Liu described is to build your own environments and fill them with synthetic data the model has never seen. But he thinks evaluation ultimately has to land in real workflows such as finance, law and medicine, where people have already defined many metrics.</p>

  <p><strong>Environments should be realistic, controllable and dynamic.</strong> These are Qian’s three criteria. Controllable means, first of all, reproducible: the larger the environment, the less stable the results when different people test the same model. Because RSI runs for many rounds, controllable also means that the gain from each round can be measured separately. Dynamic means that the environment reveals constraints or user intent step by step, which tests how a model adapts when results differ from what it expected. Realistic and controllable pull against each other, however: real-world signals are messy and hard to turn into a structured environment, while an environment built entirely by hand or by an LLM looks fake.</p>

  <p><strong>Decide first which learning challenge you want to test.</strong> Yin argues that an RSI benchmark cannot be just a subset of an older benchmark. It needs a learning challenge of its own, and efficiency and cost should be part of the metrics. When his team built ApprenticeBench, preventing reward hacking still depended on a lot of people reading agent trajectories. He thinks that detecting this behavior at scale could be a benchmark in itself.</p>

  <p>The host, Dawei Li, added an observation: these problems closely resemble the ones met earlier when evaluating the reasoning ability of large models, namely memorization, data leakage and overfitting to one domain. Lessons from that work, such as continuously updated evaluations and synthetic data, can be borrowed here.</p>

  <h2 id="efficiency-is-an-underrated-metric">7. Efficiency is an underrated metric</h2>

  <p>Yin stressed repeatedly that most RSI research today focuses on frontier capability, but in deployment it turns out that agents do not get more practiced the more they work.</p>

  <p>He looks at RSI in the setting of enterprise deployment. A new hire reads the documentation, learns the software, practices hands-on and gets feedback from a manager, and eventually becomes proficient. For AI to enter a company’s workflow, it has to go through the same process. ApprenticeBench, recently released by his company NeoCognition, tests exactly this. The job it chose is construction finance accounting, an ordinary white-collar accounting role that does not need a particularly smart model.</p>

  <p>People are also unpracticed at first. But after doing the same kind of task dozens or hundreds of times, they always get faster, moving from System 2, which requires thinking, to System 1, which does not. In their evaluation, models showed no such shift at all. As he put it: “It makes no sense that after an agent has done 100 tasks, the time and cost it spends are about the same as before, or even higher than at the start.”</p>

  <p>He proposed three directions:</p>

  <ul>
    <li>Index and organize learned experience better, so that it can be retrieved quickly when a similar situation comes up.</li>
    <li>Turn the repeated procedures in the work into reusable skills or tools.</li>
    <li>Learn the job with a frontier model first, then compress the workflow knowledge it gained into a smaller, more specialized model.</li>
  </ul>

  <p>This is not only an enterprise problem. Yin said that when training one generation of models after another, people likewise want to distill the reusable knowledge from earlier iterations so that later ones need fewer experiments. Questions of efficiency and cost like these happen to be a direction that academia can afford to work on and that is still at the frontier.</p>

  <h2 id="the-human-role-moves-up-a-level">8. The human role moves up a level</h2>

  <p>Once AI takes over solving problems that are already well defined, the value of people lies in finding the problem and defining it clearly.</p>

  <p>Liu’s view is that people have always been moving up one layer of abstraction at a time: from assembly to C++ and Python, and then to neural network frameworks. In the early days everyone still wrote gradient descent by hand. The lower layers still matter, but most people can put their effort where it is closer to applications and creates more value. This is not necessarily a bad change.</p>

  <p>Huang has reviewed papers written by a fully automated research system. His impression is that the defining feature of a purely AI-generated paper is that it “uses experiments to prove something that is not necessarily an important question.” AI is very good at incremental improvement on well-defined problems, such as pushing a benchmark score a little higher.</p>

  <p>Real research is more about discovering a problem and then defining it clearly: what the input is, what the output is, and what the metric is. The rest can be handed to AI. “We have gone from being a PhD student to being a PI, from someone who writes code to a project manager, from someone who solves problems to someone who finds them.”</p>

  <p>Qian said that human insight should go into the meta level. The question used to be how to be a good PhD student. Now the question is how to be a good advisor: how to give downstream agents a more stable harness, environment and feedback mechanism, so that their self-iteration can keep running reliably.</p>

</div>

<div class="lang-content lang-zh" lang="zh" style="display: none;">

  <p>10 月 3 日，NICE 举办了一场线上的 workshop「AI 自我改进的机制、证据与边界」邀请了四位这个方向的研究者：<strong>黄呈松</strong>（圣路易斯华盛顿大学博士生）、<strong>刘世隆</strong>（普林斯顿大学博士后，2027 年秋将任哥伦比亚大学助理教授）、<strong>殷达</strong>（NeoCognition）和<strong>钱成</strong>（UIUC 博士生），一起讨论 RSI 的主流路线、当前瓶颈、评测方法，以及它对学术界和工业界的影响。下面是这次讨论总结成的8 条 take away。</p>

  <h2 id="rsi-">1. RSI 改的是整个系统，不只是模型</h2>

  <p>今天说”自我改进”，改的对象已经是一整套 agent 系统，能动的地方至少有三处。</p>

  <ul>
    <li><strong>权重。</strong> 通过训练改模型本身。</li>
    <li><strong>Harness。</strong> 包在模型外面的工具、记忆和执行流程，改它不用重训模型。</li>
    <li><strong>环境和数据。</strong> 黄呈松的看法是，不管用什么算法优化 agent，都需要更难、更贴近下游任务的训练数据，在 agent 场景里这就是环境。模型变强后能合成更好的环境，更好的环境再训出更强的模型。</li>
  </ul>

  <p>这三处会交替推进。钱成的说法是”螺旋上升”：harness 里的部件会被训进模型自己的能力，模型变强之后又需要新的 harness。刘世隆的组走过的路线也是这个顺序：先让模型自己造工具，再到环境里探索，最后用探索得到的弱监督数据训模型。</p>

  <p>既然都能改，就该一起改。黄呈松认为，协同优化的结果一定不差于单独优化，代价只是优化过程更难。</p>

  <p>殷达打了个比方：斯诺克里很难说哪根球杆最好，成绩来自球员和自己那根杆的长期磨合，换一根杆，顶尖球员也可能再打不出原来的成绩。模型和 harness 同理：各家公司的基础设施和数据分布都不一样，A 公司的训练配方搬到 B 公司的 harness 上未必好用。</p>

  <p>还有一个问题是谁来改。钱成把自我改进分成三层：修改当前答案，跨任务积累经验，提升”产生和筛选改进方案”的能力。他们做的 AI for AI 主要在第三层。过去是人设计一套 harness 或 skill 去提升执行者的能力；现在让一个 builder AI 给 target AI 搭 harness、写环境、做 debug，两者的关系像导师和博士生。</p>

  <h2 id="rsi">2. 现在RSI哪些能做，哪些还暂时不能做？</h2>

  <p>RSI 这一轮能做起来，是因为模型已经能自己跑完整个改进循环，而且每改一次，都能又快又便宜地知道改对了没有。做不到这一点的任务，比如要靠人来评判的写作、要到物理世界里做实验的科学问题，就是它现在的能力边界。</p>

  <p>为什么现在能做起来？钱成总结了三个原因：</p>

  <ol>
    <li>基础模型能独立承担闭环里的每个环节：读代码、提修改意见、跑实验、分析反馈、记录经验，中间不再需要人来衔接。</li>
    <li>Harness 让”改进”变便宜了。不用重训模型，改一下工具包装、记忆策略或执行流程，就能直接在现有模型上验证。</li>
    <li>可执行的环境多了。强化学习里有各种 gym，很多新的 benchmark 也不再只是”一个输入、一个输出”，而是 agent 可以在里面自由执行的沙盒。系统在这样的环境里能拿到更直接的反馈。</li>
  </ol>

  <p>刘世隆认为：人加电脑本来就是一个 RSI 系统，只是人的带宽太窄，没法一周七天、一天二十四小时地转。LLM 接手了人的一部分环节，循环才快起来。</p>

  <p>黄呈松点出了其中最关键的一条：reward 要便宜。他们用 AI 优化 test-time scaling 算法时，卡住的地方是每拿一次 reward 都要等很久。后来把结果提前跑好、改成静态模拟，reward 能很快拿到，优化算法就”变成了一个非常简单的事情”。再把问题改写成写代码或写文本（code as policy），语言模型就能接手。</p>

  <p>那哪些还暂时不能做？刘世隆的判断是，环境可验证时，给模型一些时间它就能做好；难的是不容易验证、或者验证成本很高的场景，比如真实物理世界里的科学和工程问题。黄呈松举的例子是写作：一版改得好不好，目前还得靠人做 A/B test，每轮反馈隔得很久，循环自然慢。在他看来，一个问题只要能写成代码、又容易拿到 reward，RSI 就没什么问题；瓶颈在于很多真实场景没法建模成这样。</p>

  <p>刘世隆认为，RSI 最核心的问题，是怎么从真实世界里拿到好的 reward。现在的 AI 系统和真实的生产、生活问题之间，还缺一个把两边接起来的连接层。他觉得这件事最重要，也最难，不过”只要连接上了，它自己就可以发展得很好”。</p>

  <p>他还补充，真实世界的问题本来也没有完美的 reward，人们同样是靠大量 proxy 任务一层层筛掉错的答案。所以不必一步做到 100%，每次比之前好一点就够了。</p>

  <h2 id="section">3. 环境是被忽视的那个旋钮</h2>

  <p>Agent 靠它和环境交互出来的轨迹学习，可是大家一直只优化 agent 这一侧，环境那一侧又贵又不会变。这是黄呈松在 Google 实习期间的论文 EnvHarness 的出发点。</p>

  <p>先说贵。Terminal-Bench 2.0 的 89 个环境，平均每个要花一位专家 15.9 小时，合计约 1,400 小时。APEX-Agents 的 33 个环境更重，每个约 485 小时，合计约 16,000 小时，按每小时 100 美元算是 160 万美元。训练要的是成千上万个环境，靠人造不出来。</p>

  <p>再说不会变。一个环境造好之后只有一个固定难度：对弱模型永远做不对，对强模型又太简单，两头都学不到东西。即使一开始难度合适，模型训几轮变强之后，这个环境也就失效了。</p>

  <p>EnvHarness 的做法是不新建环境，给现成的环境套一层 harness，思路和 agent harness 包在冻结的模型外面一样。任务本身和判定任务是否完成的 verifier 都不动，只调初始状态、动作、观测和状态转移这四样。它有三个组件：</p>

  <ul>
    <li><strong>Stage</strong> 改初始状态。任务是”把洗干净的马克杯放到桌上”：把杯子先藏进抽屉，任务变难；提前替 agent 把杯子拿好，任务变简单。</li>
    <li><strong>Contract</strong> 改规则。禁掉”直接走到某处”的快捷动作，agent 就必须学会导航。</li>
    <li><strong>Chain</strong> 把几个短任务串成一个长任务，前一个做完不结束，接着做下一个。</li>
  </ul>

  <p>写这层 harness 的是另一个 agent，叫 EnvRigger。它读策略跑出来的轨迹，找出系统性的弱点，写一段 harness 代码，再让策略在改过的环境里重新跑一批轨迹来验证。如果任务变得无解，或者毫无挑战，这次修改就被拒绝。</p>

  <p>报告里举了一个 SWE-bench 上的例子。策略总是不跑那个失败的测试就提交补丁，EnvRigger 于是写了一个假的 pre-commit hook，把这类提交拦下来。策略由此学到一条技能：改之前和改之后都跑一遍测试。这个实验里 EnvRigger 和被训练的策略用的是同一个模型，所以提升不是从更强的模型蒸馏来的。</p>

  <h2 id="section-1">4. 最大的技术卡点是归因</h2>

  <p>自我改进的中间一步是诊断：看到失败，找到原因，再提出一个可以验证的修改。钱成认为这是眼下最主要的卡点。</p>

  <p>难处在于，同一种表面现象可能有完全不同的原因。一次失败可能来自推理，来自工具接口，来自信息缺失或记忆模块的干扰，甚至来自对训练目标的理解有偏差，每种都需要不同的干预。过去这一步靠的是人的经验。</p>

  <p>模型现在的毛病是自下而上。它会 case by case 地看错在哪，再反过来打补丁。人会先自上而下地判断整体思路哪里有问题，再去验证。逐例打补丁式的归因很容易过拟合。</p>

  <p>钱成给了两个方向。</p>

  <ul>
    <li><strong>诊断要有证据。</strong> 看中间状态，看预期结果和实际反馈之间的差距，看实际的资源消耗，再从这些去推原因，不能把系统当黑盒。</li>
    <li><strong>归因要做对照实验。</strong> 像论文里做消融实验那样，把模型、工具、记忆、执行流程里的某一样替换掉或去掉，或者 replay 一遍，看结果怎么变。这些事现在主要是人在做。</li>
  </ul>

  <p>他的结论是，要教给系统的不是某个 benchmark 上的技巧，而是”怎么做假设检验”这种更抽象的思考方式。</p>

  <p>前面提到的 EnvRigger 可以看成这个思路的一个小规模实现。它从多条轨迹里找系统性的弱点，而不是只针对于单个 case。</p>

  <h2 id="section-2">5. 自我迭代的收益饱和得很快，而且分数涨了不等于能力涨了</h2>

  <p>钱成讲了他们实验里的一个现象。他们让模型反复改进自己的 harness，每改一轮就测一次效果。结果在隐藏集上，分数前几轮在涨，到第四五轮就不再涨了。所以并不是迭代得越多，效果就越好。但是模型判断不了什么时候该停，钱成说，成本控制这件事”可能根本就不在它的脑子里”：效果上不去，它还会继续加轮数。抠细节式的优化越做越过拟合，最后甚至会掉点。</p>

  <p>人的做法不一样。先在一小部分数据上试，确认有效再投入大规模资源。这一小部分还要挑得尽量多样，能暴露的问题越多越好。钱成认为，系统要学会的正是这种分阶段的资源分配。</p>

  <p>黄呈松补充道，RSI 很容易过拟合到手上的任务，找到的可能是捷径，甚至是直接 hack 了这个任务。所以要分清，agent 是真的变强了，还是只是更会做这一类题。</p>

  <p>有观众问：不能无限循环的自我提升，还算不算 RSI？黄呈松回答说，模型的参数量有限，能力一定有上限，”希望 RSI 可以无限提升是个不现实的事情”。值得关心的是多快能接近上限，以及能不能感知离饱和还有多远，好提前停下来。</p>

  <p>钱成补充，迭代次数不该成为定义的门槛。预算用完、边际收益递减都会让循环停下，要看的是大方向是不是在往上走。</p>

  <h2 id="rsitraintest-">6. 评测 RSI，train/test 切分不够用</h2>

  <p>一个会自己找捷径的系统，靠”划一个测试集”防不住数据泄露和 reward hacking。那该怎么评测？四位嘉宾各给了一个思路。</p>

  <p><strong>用一次性的、和时间绑定的评测。</strong> 这是黄呈松的主张。一类是预测：把新旧两版模型同时放进真实市场，或者让它们预测未来的事件，答案事先谁都不知道，也就没有泄露。另一类是让人做 A/B test。代价是成本高、出结果慢，没法在线地衡量一个 RSI 算法。</p>

  <p><strong>或者退一步，用完全可控的合成环境。</strong> 刘世隆提到的折中办法是自己构造环境，放进模型从没见过的合成数据。但他认为最终还是要落到金融、法律、医疗这些真实的工作流里，那里有大量人们已经定义好的指标。</p>

  <p><strong>环境要做到真实、可控、动态。</strong> 这是钱成的三个标准。可控首先是可复现：环境越大，同一个模型由不同的人测出来的结果越不稳定。RSI 要迭代很多轮，可控指的是，能分别衡量每一轮迭代带来了多少提升。动态指环境会逐步揭示约束或用户意图，考的是模型发现结果和预想不一样时怎么适应。但是，真实和可控互相矛盾：真实世界的信号是乱的，很难做成结构化的环境；全靠人工或 LLM 构造，又会显得很假。</p>

  <p><strong>先想清楚要考的学习难点是什么。</strong> 殷达认为一个 RSI benchmark 不能只是旧 benchmark 的子集，得有自己要考的 learning challenge，效率和成本也应该算进指标。他们做 ApprenticeBench 时，防 reward hacking 靠的还是大量人力去看 agent 的轨迹。怎么可扩展地发现这类行为，他觉得本身就可以做成一个 benchmark。</p>

  <p>主持人李大卫补了一个观察：这些问题和当年评测大模型推理能力时遇到的很像，都是死记硬背、数据泄露、在一个领域上过拟合。实时更新的评测和合成数据等经验，是可以在这里借鉴的。</p>

  <h2 id="section-3">7. 效率是被低估的指标</h2>

  <p>殷达反复强调， 现在的 RSI 研究大多盯着前沿能力，落地时发现agent 不会越做越熟。</p>

  <p>他把 RSI 放进企业部署的场景里看。新人入职要读文档、学软件、上手操练、拿上级的反馈，最后成为熟手。AI 要进入企业的工作流，也得走一遍这个过程。他所在的 NeoCognition 最近发布的 ApprenticeBench 考的就是这件事，选的岗位是 construction finance accounting，一个普通的会计类白领岗位，并不需要多聪明的模型。</p>

  <p>人刚上手时也生疏，但同一类事反复做上几十上百回，一定越来越快，从需要想的 System 2 变成不用想的 System 1。在他们的评测里，模型完全没有表现出这种转变。他评论道：”你没有道理说这个 agent 做了 100 个 task，它花的时间和 cost 还是跟之前差不多，甚至比一开始还要更高一些。”</p>

  <p>他提了三个可做的方向：</p>

  <ul>
    <li>更好地索引和组织学过的经验，遇到类似情况能快速取回来。</li>
    <li>把工作里重复的流程沉淀成可以反复使用的 skill 或工具。</li>
    <li>先用前沿模型把事情学会，再把学到的工作流知识压缩进更小、更专的模型。</li>
  </ul>

  <p>这不只是企业的问题。殷达说，从一代模型训到下一代，同样希望把前几轮迭代里可复用的知识总结下来，后面少做些实验。这类效率和成本的问题，恰好是学界做得起、又足够前沿的方向。</p>

  <h2 id="section-4">8. 人的位置上移一层</h2>

  <p>AI 接手”解决已经定义好的问题”之后，人的价值在于找到问题，并把它定义清楚。</p>

  <p>刘世隆认为，人一直在一层层往上抽象：从汇编到 C++、Python，再到神经网络框架，早年大家还要手写梯度下降。底层仍然重要，但大多数人可以把精力放到离应用更近、更能产生价值的地方。这未必是坏的变化。</p>

  <p>黄呈松参与过一个全自动科研系统所写论文的审稿。他的感受是，纯 AI 生成的论文最大的特点是”用实验证明了一个不一定是很重要的问题”。AI 很擅长在定义完善的问题上做增量改进，比如把一个 benchmark 的分数再推高一点。</p>

  <p>真正的研究更多是发现一个问题，再把它定义清楚：输入是什么，输出是什么，指标是什么。后面的事可以交给 AI。”我们从一个 PhD 变成了一个 PI，从一个写 code 的人变成了 project manager，从解决问题的人变成了一个找问题的人。”</p>

  <p>钱成说：人的 insight 应该注入到 meta 层。以前讨论的是怎么做一个好的博士生，现在该想的是怎么做一个好的导师，也就是怎么给下游的 agent 提供更稳的 harness、环境和反馈机制，让它的自我迭代能稳定地跑下去。</p>

</div>

<script>
(function() {
  var buttons = document.querySelectorAll('.lang-switcher .lang-btn');
  var contents = document.querySelectorAll('.lang-content');
  buttons.forEach(function(btn) {
    btn.addEventListener('click', function() {
      var lang = btn.getAttribute('data-lang');
      buttons.forEach(function(b) { b.classList.remove('active'); });
      btn.classList.add('active');
      contents.forEach(function(c) {
        if (c.classList.contains('lang-' + lang)) {
          c.style.display = '';
        } else {
          c.style.display = 'none';
        }
      });
    });
  });
})();
</script>]]></content><author><name>Jinyan Su</name><email>jinyansu6@gmail.com</email></author><category term="technical" /><category term="ai" /><category term="rsi" /><category term="self-improvement" /><category term="agents" /><category term="llm" /><category term="environments" /><category term="workshop" /><summary type="html"><![CDATA[On October 3, NICE hosted an online workshop on the mechanisms, evidence and limits of AI self-improvement, with four researchers who work on RSI. The main approaches, the current bottlenecks, how to evaluate it, and what it means for academia and industry — summarized in 8 takeaways.]]></summary></entry><entry><title type="html">PhD or Working— My two cents / 选择读博还是工作</title><link href="https://jinyansu1.github.io/blog/2026/09/phd-or-working/" rel="alternate" type="text/html" title="PhD or Working— My two cents / 选择读博还是工作" /><published>2026-09-19T00:00:00+00:00</published><updated>2026-09-19T00:00:00+00:00</updated><id>https://jinyansu1.github.io/blog/2026/09/phd-or-working</id><content type="html" xml:base="https://jinyansu1.github.io/blog/2026/09/phd-or-working/"><![CDATA[<div class="lang-switcher">
  <button type="button" class="lang-btn active" data-lang="en">English</button>
  <button type="button" class="lang-btn" data-lang="zh">中文</button>
</div>

<div class="lang-content lang-en" lang="en">

  <p><em>(The original version by the author is in Chinese without using any LLM, but for English version, the author use Claude to do the translation and then manually edited and rewrite some of them that she thought inaccurate.)</em></p>

  <p>Lately a lot of younger students have been asking me whether they should do a PhD, and what research area they should work in. I can’t give anyone advice, and I don’t want to meddle in any one person’s life. So I’ll just share some fairly general thoughts.</p>

  <p>Some people are lucky through the entire PhD journey. They go to a great school for undergrad, start research early, and meet nothing but kind senior students and good professors along the way. When they apply to PhD programs, every school extends an olive branch. During the PhD they once again land great advisors and collaborators, intern somewhere new every year, maybe even graduate early, and when they finish, just as when they applied their PhD four or five years earlier, they collect top offers of every kind from both industry and academia. Meanwhile, other PhD might switch advisors many times, switch topics many times, finally meet a good advisor (or not), and barely scrape through graduation, only to discover on the job market that apart from the PhD title and a higher volume of mass emails from recruiters, nothing distinguishes them from others with only bachelor’s or master’s degrees. Life may even be worse off. By the age at which you finish a PhD, whether or not you went through the kind of mental and physical trauma during the PhD that leaves you with ‘permanent head damage,’ your memory and your test-taking ability will be far below what they were in undergrad.</p>

  <p>When, after enormous struggle and one rejection letter after another, Lady Luck finally smiles on you and you get an offer from some company, the salary HR quotes makes you question your past. What you’ll earn is about the same as a bachelor’s or master’s graduate. Compared with your peers, it may be a third of what an above-average PhD graduating that year makes, and a fifth or a tenth of what the top PhDs make (the gap with the very top outliers is much larger). And even this offer you only got because of luck.</p>

  <p>To be honest, the not-finding-a-job scenario above happens to PhDs, master’s students, and undergrads alike. But when you’ve already invested so much time in a PhD, facing the same outcome (i.e., landing a job you’re not very happy with), you as a PhD may need more mental effort to talk yourself into accepting reality. What makes regret so powerful is that it doesn’t show up when your life is smooth. But when you’re at a low point, some decision from your past, however long ago, constantly resurfaces, making you ask yourself over and over, “If I had chosen to xxx back then, would things be better?”</p>

  <p>But this is not a “don’t do a PhD” post. Most decision making in life has many dimensions, yet most decisions don’t matter that much, because whenever you gain something, you lose others along the way. This is also why I can’t give anyone advice: everyone’s personality is different, the way they handle things is different, and what they hold precious is different. So even if two people make the same decision, the trajectory afterwards is hard to predict. Some random event may affect the trajectory of your life more than all the time you spend weighing pros and cons to make a “good” decision.</p>

  <p>Whether it comes after a bachelor’s, a master’s, or a PhD, the transition from student at school to adult at society is hard. You discover that life contains many things to learn besides textbooks (intimate relationships, for example). You gradually want to stop depending on your parents financially, and to discover and shape an independent self, both financially and in character. You start meeting all sorts of people with different agendas, and you start seeing conflicts of interest you never saw in school, along with the diversity of human behavior when interests collide. In a purely exam-oriented high school, where everyone just keeps their head down and studies, you don’t really see conflicts of interest (at a high school with a more well-rounded education, perhaps students get exposed early to something closer to the real world). In college, if you don’t do research, you’ll also rarely run into them (maybe the occasional small friction with a teammate on a course assignment). Of course, at universities in China there are various scholarships, the grad school application, and so on, where all those outstanding, seemingly “well-rounded” students will take every means to show that they are better than you. (As there is not enough resources but too many people who want them).</p>

  <p>If you start doing research as an undergrad, you may also have conflicts of interest with your advisor or your project collaborators. At universities in China, the faculty evaluation system is very poorly designed (in my view, a well-designed mechanism should incentivize cooperation, rather than incentivize the stronger party in the game to hurt the weaker one). Professors in China are evaluated by papers where they are first author, which gives them plenty of motivation to grab first authorship from their students. Why do I use the word “grab”? Because in this setting the two sides are unequal in many respects: experience, connections, social reputation, and skill at PUA. (PUA originally stood for “pickup artist,” but in Chinese internet usage it has come to mean something closer to gaslighting: the systematic psychological manipulation of someone by a person with power over them, whether an advisor, a boss, or a partner. That’s the sense I’ll use throughout.) On top of that, students who are just started to learn to do research may hold an unrealistic fantasy about academia, believing that all the researchers are noble and great. Or maybe it was only me who thought so. After all, before college I spent most of my time immersed in my own world, and my only ways of interacting with the outside were what my Chinese teacher said in class and reading top-scoring college entrance exam essays. A flower in a greenhouse, if it doesn’t want to stay inside its whole life, has to go through the wind, rain, and scorching heat outside before it knows how to survive in a new environment.</p>

  <p>Under the kind of unequal student–advisor relationship described above, it’s hard to evaluate ourselves fairly, or to see others clearly. I remember the first semester of my junior year, lying awake night after night over something that was not my fault, and writing a long apology letter to a professor at my undergrad school. Even though I was quite certain that the person who should be apologizing was not me, the inequality of the relationship meant all I could do was apologize and hope he would forgive me for the word I said before (Curious what I said? I just said that I feel that my paper is trash. Somehow he is super offended because he took so much pride in getting papers into some “top” conferences such as AAAI/IJCAI. And everyone who work with him has to hold the believe that he had. ). I thought: if a long page of self-reflection and apology could buy back four or five months of my hard work, it would be worth it. Whether it was my fault, whether I should be the one apologizing , none of these matters? (Junior year is a crucial period for applying PhD, because applications begin very soon and I need to have some research project to talk about and also a recommendation letter.) In the end, that professor did not accept my apology. From then on, I knew that to most people in the world, my dignity and self-esteem worth nothing. And through round after round of reflection (I might reflect too much but I really like to chewing on things), I came to understand that, compared to “four or five months of effort and time get wasted,” what I feared more in losing was my own dignity. Since then, I have not ever again traded my dignity for anything. If I apologize, it is because I believe I truly did something wrong, not because I need to please someone.</p>

  <p>Half a year later, I started to work with professors outside my undergrad university, and my research started making good progress, though I would still feel tense and anxious whenever an email I get email from that professor that I initially worked with. Two more years after that, I had completely left the small circle of my undergrad and seen a bigger world. I had almost forgotten these traumas, and seeing that person’s name no longer triggered any PTSD. I don’t talk about these things with others anymore. Before, I would talk about these stuff over and over to walk myself out through. But once I truly walked out, these people, and the shadow they cast on me, disappeared completely from my memory, my life, and my thoughts. Driving them out of my life entirely, to the point of never thinking of them at all — that is probably the best form of “hatred” I would give. Although most of the professors I worked with at my undergrad were terrible, I also met one very, very kind mentor. He showed me that we can keep some innocence and kindness and still adapt well in our society, provided that we understand the rules of the world’s game rather than deceiving ourselves by living inside an imagined rainbow bubble. (I used to wonder how much bad luck I had to spend in exchange for such good luck to meet and learn from such a wonderful person. Getting the chance of knowing and learning from him (by accident) affected my life trajectory far more than all my deliberate decision making.)</p>

  <p>During my undergrad, I would very naively sort people into “nice” and “not nice,” and decide on that basis whether to be friends with them. Later, when I become a bit more mature, I found that humans are super complex in nature and can’t be simply classified like this, so there is no absolute “good person.” When I see a “flawless” “good person,” either they’ve only blind me with their good side, or we haven’t known each other long enough that I actually don’t know them as much. So I stopped trying to be a “good person” that I thought the outside would want me to be, because the concept itself no longer exists in my dictionary. This may be one of the changes from my PhD years that makes me happiest. Until the end of my first year, I was trying hard to be a “good person” in other people’s eyes: I smiled at everyone, never refused any request from anyone, and constantly self-reflecting (those masters of gaslighting didn’t even need to make the effort; I would just voluntarily do that to myself). These “creed of how to be a good person,” built into my education from my family, were to a large extent responsible for the discomfort and pain I felt when I first entered society. In a simulated world, if no player deviates from these rules, the total utility of all players is high. But some players will always discover that by deviating from the above principle, they can gain more. And the current rules of the game implement almost no penalty for deviation. Hence the phenomenon we all know so well: manipulation and gaslighting, or what the Chinese internet calls “PUA.”</p>

  <p>Sometimes we get manipulated because we love being a “good person” in other people’s eyes a little too much. Once we can see ourselves more objectively and have the courage to be disliked, it becomes much harder to manipulate us. Of course, everything goes wrong at the extreme: being “good” to the extreme can get you exploited by other players. “Reflecting appropriately and admitting your mistakes” is humility, but humility overdone, taken to the other extreme, makes you easier to manipulate. Since the readers my writing attracts are mostly the over-reflecting type, my no-brainer advice is: look for other people’s faults more (of course, see your own too, but don’t take all the blame on yourself). A typical example: when a project fails, some advisors will put the blame entirely on the student. But if the student can look at it objectively, they’ll find that there are many other factors in the pipeline, such as the advisor’s idea simply not working, or collaborators not pulling their weight or even making things worse. A project’s failure is more or less partly the student’s doing, but if it is “entirely” the student’s fault, that definitely doesn’t make sense.</p>

  <p>Last of all, I want to talk about some reasons to do a PhD. Many people will tell you how much they grew during their PhD: they got to witness the full biodiversity of the human species, they learned to take setbacks more lightly, and so on. But you can get these from either a PhD or a job. The difference is that in a PhD you may be manipulated by your professor, and at work you may be manipulated by your boss (either way, someone will be there to teach you lessons you pay dearly for).</p>

  <p>The reasons I can think of for doing a PhD are:</p>

  <p><strong>(1)</strong> Practically speaking, a PhD may give you five more years of buffer before the job hunt, and in those five years you accumulate connections, resources, and abilities, so you can look for a job with more composure. Of course, it may also look like you wasted five years and have nothing to prove that you have really lived through them. But that’s life: even with the same starting point and the same initial choice, people end up in very different places. So from this angle, compared with luck, choices are not that important.</p>

  <p><strong>(2)</strong> “If you want to be a professor someday, you would need a PhD.” This is one of the main reasons people consider doing a PhD. And there are also people with a real talent for research, or those who choose to do a PhD out of love.</p>

  <p><strong>(3)</strong> However hard I try to think about the meaning of life, the only answer I ever arrive at is “my life has no meaning.” I can’t set myself a goal the way others do, because all I can see is the death at the end of life. Many people work hard to locally optimize every decision in their lives, hoping to reach their “life goals” sooner and faster, to fight against fate. But no matter how many times they win against fate, one day they will be dragged by time and fate toward the same destination. So even if not doing a PhD looks like the path better suited to this local optimization (financially and career-wise, it may be much better than doing one), if your life is not aimed at that optimization, but rather at “experiencing life” on this journey where we are born heading toward death, a PhD may be a pretty good choice. Whether or not you do a PhD, you will work afterwards; a PhD just means you start working five years later. Seen this way, your life will always include the experience of “working,” but if you don’t do a PhD, you may never have the experience of “doing a PhD.” I think people are willing to pay for experiences, whether it’s visiting an exhibition or traveling somewhere. These experiences all carry some cost in time and money. A PhD is the same. If your life is not about optimizing some concrete real-world goal, then doing a PhD could be just for “knowing how is it like to be a PhD”. And choosing to do one is choosing to pay five years’ worth of “time and salary gap” as an “experience fee” in exchange for the experience of “doing a PhD.”</p>

</div>

<div class="lang-content lang-zh" lang="zh" style="display: none;">

  <p>最近收到了很多小朋友问我是否要读博的建议，以及读博应该做什么方向，我给不了别人建议，也不想去掺合某一个人的人生。所以只讲一些比较general的一些想法吧。</p>

  <p>有的人可能整个读博过程都很幸运， 在一个很好的学校读本科，然后很早开始做科研，一路上遇到的学长学姐以及老师都很好，申请phd时所有的学校都向他/她伸出橄榄枝，在phd期间再次遇到很好的老师以及合作者，每年换着地方实习，甚至提前毕业，并在phd毕业时，和四五年前申phd时一样，斩获业界和学界的各种offer。也有的人，换了很多次导师，换了很多的课题，最后遇上一个好老师，勉勉强强毕业了，却在找求职的时候发现，自己除了有个phd title，能收到更多的猎头的mass email外，在其他方面和本科生，硕士生没有任何区别，甚至还不如他们。在phd结束的那个年纪，无论是否在读博期间受过精神和身体的创伤，造成permanent head damage，其记忆力和应试能力都会大不如本科阶段。</p>

  <p>当你千辛万苦，在一封又一封的拒信中，幸运之神终于眷顾了你，让你拿到了某一个公司的offer，HR给你报的薪水却让你怀疑人生：你能拿到的工资和本科，硕士生差不多，并且和你的peer比，可能是当年毕业的中上水平phd的1/3， 是当年毕业的顶尖phd的1/5或1/10（和最最顶尖的outlier们的差距，则更大了）。甚至连这个offer，你也是因为运气好才拿到的。</p>

  <p>To be honest, 上面说的找不到工作的事，无论是phd还是ms，本科生中都会有，但当你已经投入了很多时间读博，面对同样的一个结果,（i.e., 找到一个自己不是很满意的工作），作为phd的你可能需要更多的mental effort，才能说服自己去接受现实。 懊悔感的强大之处就在于，在你快乐的时候，它不会出现；但在你低谷的时候，你过去的某个决定，即使已经过去了很久很久，还是constant的冒出来，让你一边一边的问自己”如果我当初选择了去xxx, 现在会不会好一些？”。</p>

  <p>但是这不是一篇读博劝退贴，生活中的大部分decision making，都是有很多纬度的，但是大部分的决定都不重要，因为你得到一些东西，便会失去一些东西。这也是我没法给别人建议的原因，每个人的性格不一样，处事方式不一样，觉得贵重的东西也不一样，所以，即使make the same decision，后面的trajectory也是很难预测的，一个偶然事件的发生可能都比花很长时间权衡利弊做一个”好”的决定对你人生的trajectory的影响大。</p>

  <p>无论是本科毕业，硕士毕业，还是博士毕业，从学生到进入社会的那段transition是很难的，你会发现，生活中原来除了学习，还有很多其他需要学的东西（比如，亲密关系），你也会逐渐想着脱离对父母的经济依赖，去发现和塑造一个独立的自己（无论是财务上还是性格上)。你开始接触到各种各样的人，大家有不同的目的，以及，你会开始见到各种你在学校读书期间没见过的利益冲突，以及在遇到利益冲突时人类行为的多样性。 在一个纯应试教育的高中，如果大家天天都只是自己闷头学习，是不太能见到什么利益冲突的，如果是更多元教育的高中，或许大家可以很早就接触到更贴近社会的教育）；到大学，如果你不做科研，也几乎不会遇到太多的利益冲突（偶尔可能遇到和课程作业合作者的小矛盾）。当然，如果是国内学校，可能有各种奖学金，考研之类的，以及各位德智体美劳全面发展的优秀大学生们各显神通。 但是如果你在本科开始做科研，你可能会和你的导师或者project的合作者有利益冲突。如果是国内的学校，由于教授考核机制设计的很不合理（在我看来，一个好的机制的设计应该是要incentivize合作，而不是incentivize游戏中强大的一方去伤害弱小的一方的）。国内教授的考核要求他们的论文是第一作者，这让他们有了足够的motivation和学生抢一作。为什么说是”抢”呢？因为在这个场景中，双方在很多方面都是不对等的，比如阅历，人脉，权力，以及pua的技能上。 而且，刚开始学着做科研的小朋友们，可能对学术圈抱有一种不切实际的幻想，觉得科研人员是崇高的，伟大的。又或许只有我是这么想的，毕竟我上大学前大部分时间都沉浸在自己的世界里， 唯一和世界交互的方式就是课堂里语文老师讲的东西以及阅读高分作文。 温室里的花朵，如果不想一辈子待在里面，总得先经历一番外面的风雨和酷暑，才能知道在新的环境中如何生存。在上述学生和导师不平等的关系下，我们很难看清自己，看清他人。我想起自己大三上学期的时候，为了一个不是自己的错误的事情整夜难眠，给本科的某个教授写了长长的道歉信，即使我自己非常确信应该道歉的人不是我，但因为关系的不对等，我只能道歉，希望他能原谅。我想，如果长长一纸的反思和道歉能换回我4，5个月的努力，那也是值得的，是不是我的错，以及我应不应该道歉，又有什么关系呢（大三是个很重要的阶段，因为大三结束就要申请了）。最后那个老师并没有接受我的道歉，从此，我知道了对于世界上的大部分人来说，我的尊严一文不值，也在一次又一次的反思中， 我明白了，比起”4，5个月的努力付之东流”， 我更怕失去的是自己的尊严。在那件事情以后，我好像再也没有用自己的尊严去换取任何东西。如果我道歉，那么一定是因为我觉得自己确实有一些问题，而不是我需要去讨好别人。</p>

  <p>半年后，我在校外找到了更好的导师， 科研上也有了很好的progress，在偶尔收到那位本校老师的邮件时都会感到紧张和焦虑。又过了两年后，我彻底走出了本科那个小圈子，看到了更大的世界，我几乎已经忘了这些事情，在看到这个人的名字时，也不再感到PTSD。我不再和别人谈论这些事情了。以前，一遍又一遍的谈论，是想在一遍又一遍的重复中让自己走出来，但是当我真正走出来的时候，这些人，以及他们给我造成的心理阴影，从我的记忆和生活中彻底消失了，我便不会再谈论了。将他们彻底赶出我的生活，完全想不起他们，才是最好的”恨”吧。虽然本科学校我跟过的大部分老师都挺差的，但我也遇到了一位很好很好的导师，他让我知道，保持一些单纯和善良，也是可以在这个社会上生存的很好的，但前提是，你要看懂这个世界的游戏规则，而不是自我欺骗式的把自己放进一个想象出来的彩虹泡泡里。（我以前常常想，我要用多少坏运气，才换来这样的好运气，这样的好运气，远比我辛辛苦苦做decision making对我人生的影响大）。</p>

  <p>我在本科刚毕业的时候，会非常的naive的将人分为”nice”和”不nice”， 然后决定是否要和对方成为朋友。后面更成熟一点后，我发现，每个人都是复杂的，不能够简单的分类，所以也没有绝对的”好人”。当我看到一个”完美无缺”的”好人”，要么是因为对方只让我看到了他好的一面；要么是我们相处的还不够久，我对他的了解还不够。于是，我不再尝试做一个所有人眼中的”好人”， 因为这个概念本身在我的词典里已经不存在了。这或许是读博这几年来让我最开心的变化之一。在博一结束前，我都在努力做一个别人眼中的”好人”，会对所有的人微笑，从来不会拒绝任何人的任何请求，还经常自我反思（甚至不需要大师们来主动pua）。这些长在我的教育基因里的”做人的准则”，在很大程度上导致了我初入社会时的各种不适和痛苦。在一个simulated world里，如果所有players都不deviate这个准则，那么这个world的所有players总的utility会很好，但总有一些player会发现，如果他们deviate from the above principal，他们就能获得更多的收益。并且，目前的游戏规则对deviation并没有什么惩罚。这便出现了我们耳熟能详的pua现象。</p>

  <p>我们会被PUA，有时候是因为我们太喜欢成为别人眼中的”好人”了。当我们能更客观的看待自己，有被讨厌的勇气后，就更难被PUA了. 当然，所有的事物走到了极端都会出问题，比如，”好”到了极端便会可能被其他player exploit。”适当的反思和承认自己的错误”是谦虚，但谦虚过度，走到了另一个极端，就会更容易被PUA。 由于我的文章能吸引到的读者大多是反思过度型的，所以我无脑建议大家多找找别人的问题（当然，自己问题也要看到，但不要把所有的错误都揽在自己身上）。一个很典型的example就是，当一个project失败的时候，一些导师可能会把错误完全归咎在学生身上，但如果学生能客观的看待这件事，就会发现，在这个pipeline里，还会有很多其他的因素，比如，导师的idea本身就不work或者是合作者不给力甚至帮倒忙。一个project的失败或多或少会有学生的问题，但如果”全部”是学生的问题，肯定是不make sense的。</p>

  <p>最后的最后，想聊一下一些读博的理由：或许很多人会告诉你他们在读博期间有多少成长，比如，见到了人类物种多样性，对挫折能更加云淡风轻等等。但这些，无论是读博还是工作都是可以得到的，区别是，读博可能被教授PUA， 工作时可能被老板PUA（反正都会有人给你上付费课程的）。</p>

  <p>我能想到的读博理由是：</p>

  <p>（1）现实的来讲， 读博可能多会给你五年的找工作的缓冲时间，且在这五年里，你会积累很多人脉，资源，能力，这样你在找工作时可以更从容。当然，你也看似浪费了五年光阴，一无所获。可是人生就是这样，即使起点相同，以及最初的选择相同，大家的终点也会很不一样。所以，从这个角度看，相比于机遇，选择并没有那么的重要。</p>

  <p>(2) “如果你以后想去高校做教授，你需要读博”。这是大家考虑是否要读博很重要的一个理由。还有一些真的很有科研天赋的人，或者没有天赋，但有一定科研理想的人，会选择为了热爱而读博。</p>

  <p>（3）无论我多么努力的去思考人生的意义，却始终只能得到”我的人生没有意义”的答案。我没法像其他人一样给自己一个目标，因为我能看到的只有人生尽头的死亡。很多人努力的去local optimize他们人生中的每一个决定，以期更快更早的实现他们的”人生目标”，对抗命运。可是，无论他们多少次成功的对抗了命运，总会在某一天被时间和命运拖着奔赴同一个目的地。所以，即使不读博看起来是一条更能够实现这个local optimization的路（财务上和career上可能会比读博好很多），如果你的人生不以这个optimization为目的，而是在这段生而赴死的生命旅程中”体验人生”，读博或许是个不错的选择。无论你是否读博，后面都是会工作的，只是读博会让你晚五年再工作。这样看来，你的人生中总会有”工作”这个人生体验，但如果你不去读博，可能就永远不会有”读博”这个人生体验。我想，人们是愿意为体验付费的，无论是参观一个展览，还是去哪里玩。这些体验或多或少都有时间和金钱上的cost。读博也是一样，如果你的人生不是为了optimize某个现实世界的具体目标，读博便只是个体验罢了，选择读博便是选择用五年的”时间和工资上的差距”作为”体验费”换来了”读博”这个体验。</p>

</div>

<script>
(function() {
  var buttons = document.querySelectorAll('.lang-switcher .lang-btn');
  var contents = document.querySelectorAll('.lang-content');
  buttons.forEach(function(btn) {
    btn.addEventListener('click', function() {
      var lang = btn.getAttribute('data-lang');
      buttons.forEach(function(b) { b.classList.remove('active'); });
      btn.classList.add('active');
      contents.forEach(function(c) {
        if (c.classList.contains('lang-' + lang)) {
          c.style.display = '';
        } else {
          c.style.display = 'none';
        }
      });
    });
  });
})();
</script>]]></content><author><name>Jinyan Su</name><email>jinyansu6@gmail.com</email></author><category term="personal" /><category term="reflection" /><category term="life" /><category term="phd" /><category term="career" /><category term="advice" /><category term="decision-making" /><summary type="html"><![CDATA[Lately a lot of younger students have been asking me whether they should do a PhD. I can't give anyone advice — a single chance event may shape your life's trajectory more than all the careful weighing of pros and cons. Some general thoughts on luck, dignity, conflicts of interest, PUA, and doing a PhD as an experience you pay for rather than an optimization.]]></summary></entry><entry><title type="html">My PhD Grind (2): I Was No Longer Socially Anxious / 我的PhD Grind（2）：我不再极度的社交焦虑</title><link href="https://jinyansu1.github.io/blog/2026/09/my-phd-grind-2/" rel="alternate" type="text/html" title="My PhD Grind (2): I Was No Longer Socially Anxious / 我的PhD Grind（2）：我不再极度的社交焦虑" /><published>2026-09-07T00:00:00+00:00</published><updated>2026-09-07T00:00:00+00:00</updated><id>https://jinyansu1.github.io/blog/2026/09/my-phd-grind-2</id><content type="html" xml:base="https://jinyansu1.github.io/blog/2026/09/my-phd-grind-2/"><![CDATA[<div class="lang-switcher">
  <button type="button" class="lang-btn active" data-lang="en">English</button>
  <button type="button" class="lang-btn" data-lang="zh">中文</button>
</div>

<div class="lang-content lang-en" lang="en">

  <p><em>(The original version by the author is in Chinese without using any LLM, but for English version, the author use Claude to do the translation and then manually edited and rewrite some of them that she thought inaccurate.)</em></p>

  <p>The narrative parts of this installment were all written on the flight back to China in mid-August; I added the more reflective bits at the beginning and the end and then put it up. If I had waited any longer, I would have lost even more of the feeling for my own words. Nothing in this “My PhD Grind” series is necessarily something the PhD itself brought about. Rather, I’m at a certain stage of life — a stage in which I’ve left the environment, culture, and education I’d known for over twenty years, begun to have my own independent thoughts and ways of thinking, and, in a new environment and culture, come into contact with many more different people and different things — and the changes in perception and thinking that arise naturally from that. Even if I weren’t doing a PhD, I would probably have gone through similar things and had similar realizations and reflections. It’s just that these people, these events, and these realizations happened to fall within the years of my PhD, so I use “PhD grind” to describe this stage of life. But I don’t think doing a PhD is the only way a person can grow, nor do I think I should “be grateful for the pain.” I try my best not to disturb other people’s lives, and I don’t want to intervene in anyone else’s trajectory, because I believe opportunity matters enormously, yet opportunities usually aren’t something you get to choose — and as for what’s left, the things you can choose, no matter how hard you rack your brains over them, they won’t make much difference to your life. No choice or experience is indispensable. So, I have no opinion. I don’t write these things in order to be understood, nor to “give advice.” Text is a medium for transmitting information: by the time I decode the continuous embedding of what I’m thinking into tokens, a great deal of information has already been lost; when a reader reads in those tokens and converts them into their own embedding, they add a great deal of their own context, and by then their embedding is nothing like mine. Every reader might be able to read something different out of the same passage, but more or less, they’ve seen themselves in it. I was surprised that my first post — the blog about many of my friends who works on theory switching to LLMs — resonated with so many people. Friends messaged me privately to say “they felt the same way,” or “they could really understand me.” But in fact, I wrote it from the perspective of a detached narrator, an onlooker, putting in almost no emotion at all. The deep feeling readers sensed in those words must have come from reading themselves into the text and projecting their own emotions onto it.</p>

  <p>On August 14, 2023, I went to the United States for the first time. On the flight from New York to Ithaca, before we departed, the flight attendant proudly announced to everyone: “All the crew members, two pilots and two stewardesses, are women — isn’t this awesome?” Although, like everyone else, I didn’t respond, my heart was secretly leaping. This was my first impression of America: a place where anything is possible. (Because of how I was raised, my understanding was still stuck at “In China, only the flight attendants can be women; the pilots are always men.” Though when I looked it up just now while writing this, China does have female pilots — women make up about 1% of civil aviation pilot license holders, compared to over 10% in the U.S. There’s a lot of finer-grained statistics by category, but in almost every category, the proportion of women in the U.S. is nearly ten times that in China. And since the total number of licensed pilots in the U.S. is ten times China’s, in absolute numbers there are roughly 100,000 women among all licensed pilots in the U.S. versus about 1,000 in China — a hundredfold gap.)</p>

  <p>One afternoon during grad school orientation week, walking home from Gates Hall, I passed the football field, where “Don’t Stop Believin’” was playing, and my eyes instantly welled up: in the months before coming to Cornell, I happened to be watching Glee (an American TV series), and both the show and that song mean a great deal to me. Against that backdrop of unreality, for those few days I felt like I was living inside a TV show, full of anticipation for the future.</p>

  <p>That glamorous filter lasted less than two weeks; real life quickly yanked me out of the TV show. I — who had barely any experience of the real world, who had unreasonable optimistic expectations of the new environment and the people in it, whose personality was so weak that whenever any conflict arose I assumed “it must be my fault” — ran into a very mean roommate and had to move three times in my first three months. (Later, about a month after I moved out, that roommate’s behavior became so outrageous that the third roommate couldn’t take it anymore and eventually drove the her out.)</p>

  <p>On top of that, the Chinese students in my cohort were almost all guys (there may have been one or two Chinese girls, but I never saw them around, and besides, not everyone gets along with everyone; as for people from other countries, there are obstacle in both culture and language so I didn’t really hang out that much with them). Watching the guys quickly grow close with each other, all I felt was loneliness. In October, the weather gradually turned bad, and once the clocks fell back to winter time, it was dark by 4 p.m. The weather and the troubles in my life piled on top of each other, and I gradually became a bit depressed (though compared to the depression of my second year, the depression in my first year should be consindered as mild). By December, I still hadn’t made any friends. Over the Christmas break the campus was nearly empty — the loneliest time to be in Ithaca, and the time my depression was at its worst. I would reflect on and chew over everything that had happened in my four months in the US, again and again, and ask myself over and over: why did it turn out this way? Although I never want to go through that pain again, looking back now, without those painful times I wouldn’t have come to understand myself better, and I wouldn’t have become who I am now.</p>

  <p>After the spring semester started, the weather got better, and my mood lightened along with it. It was right around then that I got to know a more senior student at another department, and we’d play ping-pong together every so often. By April, we had gradually reached the point where we could talk about anything, and she became the first female friend I made after coming to the US. In my first six months, I had tried to become friends with lots of Chinese (and mostly, male), forcing myself out of my comfort zone, but all that socializing left me extremely anxious and dejected. It was only after becoming good friends with her that I learned what healthy socializing should look like. Maybe all I needed was one friend to stop feeling like there was “something wrong with me.” After we became good friends, I stopped trying, as I had before, to befriend people who triggered my social anxiety, because I knew that good socializing shouldn’t make me anxious. I also gained other friends around the same time: a Sri Lankan girl in my cohort, who is kind, geninue, and full of love for life, and a master’s student in economics (a sports buddy I could call up anytime to play sport such as pingpang, badminton, tennis, chatting about anything and everything while we played). April and May were probably the happiest stretch of my first year in America, apart from that first week — it felt like I was bathed in sunshine every day (both physically and mentally). In late May, I went back to China. The day before I left, I looked back over my nearly a year in America. Although the happy times amounted to only the month or so before I left, my personality had already changed a lot: I no longer tried so hard to please people to win their friendship, I was no longer afraid of being disliked, and I had become far more selective about making friends rather than expecting to be friends with everyone. That day, I re-downloaded QQ (a Chinese messaging app) and messaged a classmate back in college: “I feel like everyone hated me in undergrad. Can you tell me why?” I asked him because he was probably the only person I could remember who “don’t hate me that much.” I’m not sure what state of mind I was in — maybe it was out of curiosity, maybe I was in such a good mood that nothing he could say would affect me, or maybe I just wanted to confirm whether my original “feeling that everyone hated me in undergrad” was only me being oversensitive, something I’d imagined. I’ve forgotten the details of our conversation. After he told me to “think it over myself” and I couldn’t come up with anything no matter how hard I tried, he told me it was “because people felt I didn’t fit in with the group.” From that day on, I can finally let it go. That day, I uninstalled QQ and truly said goodbye to undergrad. Actually, since coming to America, I have never again felt “weird.” I found that everyone is pretty different, and sometimes I even worry that I’m not “weird” enough — that compared to others (especially some of my American classmates), that I don’t have anything distinctive about me.</p>

  <p>That summer I went back to China to renew my visa. Although I hadn’t been home in two years, I didn’t feel much nostalgia for life in China — the high-rises, the dense crowds, and the traffic still made me very uncomfortable (I constantly felt that one careless moment and I’d be hit by a bicycle, an e-bike, or something bigger, because everyone is in a hurry and no one yields to pedestrians). It was my first time living in Beijing not as a student, and I met all sorts of people. Beijing doesn’t have the comfort of life as in Chengdu; Haidian District and Tsinghua were more run-down than I’d imagined; and the people I chatted with while renting a place, along with the Didi (ride-hailing) drivers taking me home at night, made me feel everywhere the hardship of the “Beijing drifters” — those who leave their hometowns to make a living in the capital. There were also plenty of things worth being happy about in between. For example, a girl I’d met at Cornell and I arranged to spend a day together in Beijing; we got to know each other better and discovered how alike we were. On the day we parted in Beijing, we chatted our ideal of a good friendship to be “close but independent” — a healthy friendship, one in which both parties can grow, should be like that. Afterwards, we constantly catched up with each other on the phone often and became very, very good friends. Later still, when I moved to the Bay Area, she became my only friend there. (The Bay Area seems even harder to make friends in than school.)</p>

  <p>That summer I also went to ICML and ACL, saw some old friends, and met one or two people I’m still close with today. It was a pretty decent summer. All of this was a long, long time ago. If I didn’t make an effort to remember, I’d almost forget I once had so many problems (though even now I still occasionally hide from people I know when I run into them since sometimes I have nothing to say and become ackward if I have to start some small talk). Those are all the stories in my first year. There doesn’t seem to be anything PhD-related worth recording, but after a year, I no longer felt so broken: beyond the social problems mentioned above, my personality changed in other positive ways too — for example, I became more confident, I stopped feeling that I didn’t deserve to be at Cornell, and I began to have a strong sense of belonging.</p>

  <p>Looking back, the first year was a fairly beautiful one. Whatever the winter had been like, when summer arrived in April and May, I didn’t feel a trace of sorrow. It was in the following two years that I truly entered the grind of the PhD itself, and lost many things I consider important — like the ability to be happy. It took me far too long to recover. Going by my earlier expectations: I thought I’d be happy once I switched advisors; I thought I’d be happy once the project was over; I thought I’d be happy once the paper got accepted; I thought I’d be happy once summer came; I thought I’d be happy once I left Ithaca for the Bay Area; I thought I’d be happy once the internship ended; I thought I’d be happy once I started the new internship; I thought I’d be happy once I didn’t have to do research anymore; I thought I’d be happy once I found a job…</p>

  <p>Looking forward to one milestone after another like this, two whole years went by. Occasionally I would suddenly feel happy, but that happiness never lasted more than a week.</p>

  <p>I had never waited for such a long time like this before, for two whole years — far, far too long. Hoping again and again, disappointed again and again, I gradually began to accept the state I was in. And as the happy self of two years ago receded further and further, in my second year I would still occasionally struggle, wondering how to find my old self again; by my third year, I had grown used to the self that was no longer happy. (I started to think that maybe this unhappiness wasn’t caused by the PhD, but is the inevitable destination once a person reaches a certain age and has seen a huge amount of people and things.)</p>

  <p>Although this ending is a bit sad — and the next several posts will all be sad in tone — to spare readers too much sadness, I need to give a spoiler alert here: in August, I found a job and went back to China to rest for a while. In the process of cleaning up a past stage of life and getting ready to welcome a new journey, I also threw away a lot of things that needed throwing away (like some of the trauma and pain). The best way to find yourself again is to change your environment. Moving from Ithaca to the Bay Area didn’t seem to help much, since I was under job-search pressure at the time. But after finding a job in August, I went back to China to rest — no mental pressure, a changed environment, and a new life to look forward to — and I felt a lightness and joy I hadn’t felt in a very long time. With all these factors stacked together, I found my happy, pre-PhD self again (though I don’t know how long this happy state will last, while I’m happy now, I plan to enjoy it while I can.</p>

  <p>Compared to before the PhD, the me of today is more mature, more emotionally stable, and understands more deeply about the meaning of life and how the world works. I’m also better able to find, in such a complex real world RL env, a way of existence that at least for now feels self-consistent, and to continue, with a more peaceful attitude, the rollout along the short trajectory of my life.</p>

</div>

<div class="lang-content lang-zh" lang="zh" style="display: none;">

  <p>这节的记叙性内容都是8月中回国的飞机上写的，加了开头和结尾的抒情性内容便放上来了，要是再隔的久一点，我对自己的文字就更没有感觉了。所有这些”我的PhD grind” 系列，并不一定是读博本身带来的，而是，我处于人生中的某个阶段，我会在这个阶段里， 离开了过去二十多年来熟悉的环境，文化，和教育，开始有自己独立的思想和思考，在新的环境和文化中，接触到更多不同的人，不同的事，而自然产生的认知和思想上的改变，即使我不读博，可能也会经历类似的事，有类似的感悟和思考，只是，这些人，事以及感悟恰好发生在了我的PhD的这几年，于是便用”PhD grind”来表达这样一个人生阶段了，但我并不觉得只有读博能让一个人成长，也不觉得我应该”感谢痛苦”。我尽量不去打扰别人的人生，也不想去intervene其他人的轨迹，因为我觉得机遇很重要，但机遇往往是不可选的，而剩下的可以选的东西，无论你怎么绞尽脑汁，都不会对人生有太大的影响，没有什么选择或经历是必不可少的，所以，我没有opinion。我写这些东西，不是为了被理解，也不是为了”给大家advice”， 文字是信息传播的媒介，当我把自己所想的连续的embedding decode成token的时候，就已经损失了很多信息了，读者读入token，并将其转化成他们自己的embedding时，又回加上很多读者自己的context，这时的embedding已和我的embedding完全不一样了。同一段文字，每个不同的读者应该都能读出不同的东西，但或多或少都是因为看到了他们自己。我惊异于自己的第一篇文章关于周围人都转LLM的blog能引起那么多人的共鸣，有朋友私信告诉我，”他们也有这样的感觉”，或者是”他们非常能理解我”。 但实际上，我是一一个旁观的叙述者的角度写下的，几乎没有放入任何的情感，读者们在这些文字里感到的深深的感情，或许是因为他们在文中读出来自己，并把自己的感情投射进去了。</p>

  <p>23年8月14日，我第一次去美国。从纽约到伊萨卡的飞机上，飞机启程前，空乘非常骄傲的向所有人宣布”all the crew member, two pilots, and two stewardess are woman， isn’t this awesome?”. 虽然我和其他人一样没有应答，心在却偷偷的雀跃着，这是我对美国的第一印象，这是一个一切皆有可能的地方（受到家庭教育的影响，我的认知还停留在”中国的飞机上只有空乘可以是女性，但飞行员一定是男性”， 虽然我刚刚写的时候查了一下，中国依然是有女性飞行员的，持有民用航空器驾驶员执照的人中女性大约1%， 而美国则超过了10%， 虽然这里面还有很多细分的category的数据，但几乎所有的category里，美国的女性和比例都是中国的将近十倍。 由于美国全部执照飞行员的人数是中国的10倍，所以在具体人数上，美国全部持照飞行员中女性大概10w人，中国的女性则有1k人，是100倍的差距。）</p>

  <p>Orintation的那周的某天下午，我从Gates回家，经过橄榄球场，里面播放着”don’t stop believing”, 我瞬间湿了眼眶，因为在来cornell的前几个月，我刚好在看Glee(一部美剧），这部剧，以及这首歌都对我具有重要意义。那种不真实感的烘托下，那几天，我像生活在电视剧里， 对未来充满了期待。</p>

  <p>这种滤镜持续了不到两周，现实生活很快就把我从电视剧里拽了出来。没怎么接触过社会的我，以及对新环境以及环境里的人有着不合理预期的我， 那个遇到任何冲突都会觉得”是我错了”的性格十分软弱的我，因为遇到了一个很mean的室友，不得不在刚来的三个月里搬了三次家（后来，在我搬走后一个月后，这位室友因为行为过于离谱，另一位nice的室友受不了了，最终将那位mean的室友赶走了。 ）</p>

  <p>再加上cohort里的中国人几乎都是男生（可能有一两个中国女生，但平常见不到，而且也并不是和所有人都能合得来的；至于其他国家的人，由于文化和语言隔阂，也没怎么一起玩），看到中国的男生们之间很快的熟络起来，我只觉得孤独。 10月份，天气渐渐冷了起来，冬令时开始后，下午4点天就黑了，天气以及生活中的烦心事叠在一起，我逐渐变得有点抑郁了起来（但跟第二年的抑郁比起来，这次算很轻了）。直到12月份，我依然没有交到任何的朋友，圣诞节的假期里，学校里几乎没有人，这是ithaca最难熬的时候，也是我抑郁情绪最强烈的时候，我会把来美国后的四个月遇到的事一遍又一遍的反思和咀嚼，然后反复的问自己，为什么会这样。这些痛苦，虽然我不想再经历一遍了，但现在回过头去想想，如果不经历那些痛苦的时光，我就没法更加了解自己，也不会变成现在的自己。</p>

  <p>春季开学后，天气变得好了起来，我的情绪也跟着天气一起，开始变得轻了起来，也刚好是那时候，我认识了一位学姐，我们每隔一段时间会一起打乒乓球，到了四月份，我们逐渐开始变得无话不谈， 她成了我到美国后交到的第一个朋友。 刚来的那半年里，我尝试和很多人成为朋友，强迫自己走出舒适圈，但这些社交让我感到极度的焦虑和沮丧。 和学姐成为好朋友后，我才知道到一个健康的社交应该是怎么样的，或许我只需要拥有一个朋友我就不会觉得自己”有问题”了，在和学姐成为好朋友后，我不再像以前那样，尝试和一些会激发起我social anxiety的人成为朋友，因为我知道，一个好的社交，不应该让我感到焦虑。逐渐的，我还收获了其他朋友，比如和我一个cohort的斯里兰卡的小姐姐，她善良，淳朴而又热爱生活，以及一个经济系的master（一个随时能叫出来打各种球的球搭子，一边打球，一边互相天南地北的聊天）。四五月份那段时间应该是我来美国的第一年里除了第一周之外最快乐的时光了，感觉每天都沐浴在阳光下（both physically and mentally)。五月下旬，我回国了。在走的前一天，我回顾了来美国将近一年的生活，虽然快乐的时光只有离开前的一个多月，我的性格已经变了很多，我不再那么努力的讨好别人来获得友谊，不再害怕别人讨厌自己，交朋友时也变得selective了很多， 而不是期待和所有人都成为朋友。那天，我重新下载了QQ，向大学隔壁班的一个同学发消息，问”我感觉本科时大家都很讨厌我，你能告诉我为什么吗？”，我会问他是因为他可能是我印象中唯一一个让我感到”没那么讨厌我”的人。我也不知道自己当时是什么心态，或许是out of curiosity，或许是心情好到他无论怎么回答都不会影响到我，又或许我只是想确认我最开始的”感觉本科时大家都很讨厌我”是不是只是我自己太过敏感了，自己想象出来的。我和他的具体对话内容我已经忘了，在他”让我自己好好想想”但我无论如何也想不出来后，他告诉我，”是因为觉得我不合群”，从那一天起，我释然了。那天，我卸载了QQ，真正的向本科告别。其实，来到美国后，我就再也没感受到自己的”奇怪”， 我发现大家都挺不一样的，有时候我甚至会担心自己不够”奇怪”， 没有和其他人（尤其是一些美国的同学）比，没有自己的特点。</p>

  <p>暑假我回国续签，虽然两年没回家，但对国内的没太多怀念，高楼，密集的人群以及车辆，还是会让我觉得很不舒服（老是觉得自己一不小心就会被自行车，电动车，或者更大的车撞上， 因为大家都很急，也不会礼让行人）。 我第一次以一个非学生的身份在北京生活，也遇到了一些各色各样的人。北京没有成都生活的舒适，海淀区以及清华比我想象的破旧，租房接触的人，以及晚上回家的滴滴车司机则让我处处感受到那些离开自己的家乡的北漂们的艰辛。 中间也发生了很多值得快乐的事，比如， 和我在Cornell认识的一个女生在北京约着一起玩了一天，对彼此有更多的了解，发现我们是如此相似，在北京分别的那一天，我们用了”亲密而独立”来定义我们理想中好的友谊，一段健康的，让双方都能成长的友谊，应该是这样的吧。后面，我们还是经常一起电话聊天，成了彼此很好很好的朋友，再后来，我搬到了湾区，她成了我在在湾区那边唯一的朋友。（湾区似乎比在学校更难交到朋友）。</p>

  <p>那个暑假，我还去了ICML和ACL，见了一些老朋友，也认识了一两个现在还关系很好的朋友，度过了一个还算不错的暑假。这些事情已经过去好久好久了，如果不努力的去回忆，我都快忘了自己曾经有这么多的问题（虽然我现在也会偶尔在遇到时躲着认识的人）。第一年就这样过去了，好像没有什么和读博相关的事值得记录，但一年下来，我不再觉得自己那么残缺了：除了上面提到的社交问题，我的性格在其他方面也有positive的改变，比如，我变得更加自信了，不再觉得自己不deserve， 我开始有了很强的归属感。</p>

  <p>第一年回过头去看算是比较美好的，无论冬天如何，在四五月份夏天来的时候，我感受不到一点忧愁，后面两年，我才开始真正进入和读博相关的grind，失去了我很多我觉得重要的东西，比如快乐的能力。我花了太久的时间去恢复：按照之前的预期，我以为换了导师我就能快乐了；我以为project结束我就能快乐了； 我以为paper中了我就能快乐了；我以为夏天来了我就能快乐了；我以为离开Ithaca搬到湾区我就能快乐了； 我以为实习结束我就能快乐了； 我以为去新的实习我就能快乐了；我以为不用做科研我就能快乐了； 我以为找到工作我就能快乐了…</p>

  <p>就这样一个时间节点一个时间节点的盼望着，过了整整两年，偶尔，我也会突然感到快乐， 但那个快乐不会持续不超过一周。</p>

  <p>我从没有过类似这样长达两年的等待，太长太长，一次又一次的期待，一次又一次的失望，我逐渐开始接受自己的状态，而且，随着两年前那个快乐的自己越走越远，phd第二年的时候，我还会偶尔挣扎一下，想着怎么找回之前的自己，在第三年的时候，我开始习惯了那个不再快乐的自己。（我开始觉得，或许这种不快乐不是读博导致的，而是人成长到一个年龄，见到了很多人和事后的必然归宿。</p>

  <p>虽然结尾这里有点悲伤，因为接下来的几篇的基调都会是悲伤的，为了避免为读者带来过于悲伤的情绪，我需要在这里spoil alert一下，在8月份，我找到了工作，并回国休息了一段时间，在clean up过去的一个人生阶段的过程中，迎接新的旅程的过程中，也扔掉了很多该扔掉的东西（比如一些创伤和痛苦。 找回自己最好的方式是换一个环境，之前从ithaca换到湾区好像没啥用，毕竟当时面临着找工作的压力，8月份找到工作后，就回国休息了，没什么精神压力，再加上环境变了，以及因为要迎接新的生活了，我感到很久都不曾有过的轻松和愉悦， 在这些多重因素的加成，我又找到了读博前的快乐的自己（ 虽然不知道这种快乐的状态能持续多久， 但是趁现在很快乐，我打算得过且过）。</p>

  <p>相比于读博前，现在的我，更成熟，情绪更稳定，更理解社会，生命，和人生， 也更能在这样一个复杂的RL env里面找到一个暂时让我感到自洽的方式，更加平和态度的继续我短暂的生命中的rollout。</p>

</div>

<script>
(function() {
  var buttons = document.querySelectorAll('.lang-switcher .lang-btn');
  var contents = document.querySelectorAll('.lang-content');
  buttons.forEach(function(btn) {
    btn.addEventListener('click', function() {
      var lang = btn.getAttribute('data-lang');
      buttons.forEach(function(b) { b.classList.remove('active'); });
      btn.classList.add('active');
      contents.forEach(function(c) {
        if (c.classList.contains('lang-' + lang)) {
          c.style.display = '';
        } else {
          c.style.display = 'none';
        }
      });
    });
  });
})();
</script>]]></content><author><name>Jinyan Su</name><email>jinyansu6@gmail.com</email></author><category term="personal" /><category term="reflection" /><category term="life" /><category term="phd" /><category term="social-anxiety" /><category term="friendship" /><category term="growth" /><summary type="html"><![CDATA[The first year of my PhD in America: three moves in three months, a lonely first winter in Ithaca, the first real friend, and learning what healthy socializing should feel like — plus a spoiler alert: after two years of waiting to be happy again, I found my pre-PhD self back.]]></summary></entry><entry><title type="html">My PhD Grind (1): All the Friends Who Worked on Theory Have Switched to LLMs / 我的PhD Grind（1）：23年申phd时认识的那群朋友至此都转了LLM</title><link href="https://jinyansu1.github.io/blog/2026/09/my-phd-grind-1/" rel="alternate" type="text/html" title="My PhD Grind (1): All the Friends Who Worked on Theory Have Switched to LLMs / 我的PhD Grind（1）：23年申phd时认识的那群朋友至此都转了LLM" /><published>2026-09-04T00:00:00+00:00</published><updated>2026-09-04T00:00:00+00:00</updated><id>https://jinyansu1.github.io/blog/2026/09/my-phd-grind-1</id><content type="html" xml:base="https://jinyansu1.github.io/blog/2026/09/my-phd-grind-1/"><![CDATA[<div class="lang-switcher">
  <button type="button" class="lang-btn active" data-lang="en">English</button>
  <button type="button" class="lang-btn" data-lang="zh">中文</button>
</div>

<div class="lang-content lang-en" lang="en">

  <p><em>(The original version by the author is in Chinese without using any LLM, but for English version, the author use Claude to do the translation and then manually edited and rewrite some of them that she thought inaccurate.)</em></p>

  <p>(Note: In order to preserve the privacy of the people that I mentioned, I didn’t use their real name, but instead, using the name “Jack”, “Frank”, “Leo” instead.)</p>

  <p>I had originally wanted to give this the structure of a perfect book: a prelude, three distinct chapters (not for the sake of literary completeness, but because my PhD really did come in stages, almost neatly divisible by year), and an epilogue. So after jotting down some loose notes on the flight back to China, I spent a long time thinking about how to structure what I’d written, how to shape it into the perfect, complete form I had in mind before presenting it to readers. The result: three weeks went by, and the draft I wrote on the plane was never finished.</p>

  <p>One day in September, while chatting with a friend, I was surprised to learn that he had switched from theory to LLMs. A rush of feelings came over me and I wanted to write something. What I wanted to write belonged, properly speaking, in my PhD memoir—but the memoir had never gotten off the ground, precisely because of my pursuit of perfection. I don’t know how I picked up this habit, but whenever I present something imperfect to readers, I feel I have to apologize first and honestly list everything I think is wrong with it. (Seen this way, I’m really not cut out for academia or startups. Though the people and events of my PhD have also taught me to be a little less harsh on myself, and a little more forgiving.) So I’ll just write freely, wherever my thoughts happen to go. Reality is, after all, imperfect and incomplete; if I tried to write this like a work of literature, with the reader’s experience in mind, I would be sacrificing truthfulness and spontaneity—the feelings I have while writing, and the flow of my state of mind. Besides, works of literature have storylines, and reality doesn’t. I’ve become more and more able to accept the chaos of the world, and my own chaos within it (the flattering term for which is “free-spirited”).</p>

  <p>That day, I happened to open an article on Zhihu and noticed that the account of a friend, Leo, had liked it. So I messaged Leo on WeChat—we hadn’t seen each other in a long time, and I wanted to catch up and ask how he’d been. He told me he was planning to switch to working on LLMs, and that over the past year he had moved to a new place and was talking to people even less than before. Even though we hadn’t been in touch for over a year, chatting with him still felt familiar. Back in 2023, when we were applying for PhDs, we were both working on theory. But Leo socialized very little and rarely reached out to anyone to hang out (he spent most of his time doing research and reading papers), though when we ran into each other now and then I’d chat with him a bit. So I wouldn’t say I knew him well enough to call us “close.” And yet he came to my PhD A exam last year. (Not many people came since I hadn’t made any special announcement—it was only visible in a mass email that the grad school requires us to send to all the PhD student in a certain format. He’s also not the kind of person who likes going to presentations, especially when the research I was presenting had nothing whatsoever to do with what he was interested in. So the fact that he noticed, and made time to show his support, surprised me.) Leo’s PhD path has been extremely rocky. Given his hermit-like style, he probably wouldn’t want me telling other people too much about it, so I’ll leave that part out. But even though his PhD hasn’t gone smoothly, he has always been so calm, so unruffled.</p>

  <p>Every time I talk with people around me (especially the guys) and learn what they’ve been through, I think: “Why am I so bad at enduring hardship? The smallest thing happens to me (compared to what they have been through) and I start kicking up a fuss, as if I want the whole world to know how much pain I’m in and how hard things are—while they, facing far more and far harder things, keep a straight face, placid as still water.” Of course, this kind of self-gaslighting usually passes in an instant. I tend to look at things from an all-around, complete perspective, so everything gets considered from multiple sides and angles, and I freely adjust the weight I give to each. The upside is that I never become too stubborn or opinionated; the downside is that sometimes people feel I have no personality of my own, that I just agree with everything. (I’ve just wandered off topic again…)</p>

  <p>In fall 2024, I was considering quitting, and Leo was in the middle of switching and finding new advisors. I half-jokingly said, “Why don’t you quit with me? You wouldn’t even have to worry, like I do, about how quitting would negatively affect your advisor’s reputation. Or, stop doing theory and switch to an advisor who does applied work?” (In a CS department, if Leo didn’t care about his research direction, finding an advisor would be much easier.) But he remained very firm, and firmly described to me the career path he had in mind. He framed his choice to do a PhD as “so that I can go into quant after graduation and get a very high salary.” I didn’t quite follow his logic, because from my perspective, he could go into quant companies even without a PhD, or without doing theory. But Leo described it as though it were the only path. I just smiled, because from what I knew of him, he was the unpretentious kind of scholar, and the “high salary” of quant would hardly be enough to make him choose, so resolutely, a path that looked so much harder. (Note that I added the qualifier “unpretentious” here, because not every scholar can be described that way—and this was precisely the mistake I made when I first entered academia. But nothing is absolute; back then I could only see one side of people and things, and I blindly passed judgment on them based on what I saw. That was my own problem.)</p>

  <p>Perhaps it’s Leo’s “hermit” style that lets him hear less of the world’s noise, and steadfastly do what he likes, what makes him happy (doing theory, writing formulas, and reading proofs really are a joy for some people!). In my first year of the PhD, I too agonized for a long time over whether to give up theory. Even back when I started doing theory as an undergrad, my undergrad advisor kept telling me that doing theoretical research has a lot of downsides, such as it is hard to recruit students, hard to get funding, and students are hard to find a job… But at that time, working are theory made me feel calm and happy, so none of those practical considerations mattered. I had hoped I could do both theory and application (so in my first year I was in fact doing both at once). On the one hand, I couldn’t give up theory, because it made me feel at peace; on the other hand, I couldn’t give up NLP, because coding had been my weak spot for the past several years, and if I abandoned applied work entirely, it would become my weak spot once again. (And with that would come a lack of confidence, the kind that keeps me from seeing many people and things from an objective, equal footing, but admire people who can code.) I struggled for an entire year since I don’t want to give up any of these two, and in the end, because of a project I didn’t much like, I finally decided to stop working on theory. Looking back now, I ought to thank this twist of fate, because I was no longer distracted the way I used to be. Before, even when doing theory and applied projects side by side, I would always prioritize theory, because it made me happy. I didn’t care whether I was doing it well enough, didn’t care that a simple proof took me ages to understand, didn’t care whether my brain or my level of effort were suited to it. I only cared about the happiness of the moment, and about that slow, unhurried life of “one pen, one book, one proof to stare at for days.” (Even though some of the peers I know, could probably get through it in 30 minutes, lol.)</p>

  <p>When my second year began and I decided to give up theory completely and focus on LLMs and NLP, it was painful at the time, because I didn’t like living at such a fast pace, and I didn’t like writing code. I wanted my tools to be pen and paper; I wanted the computer to be something I used for reading proofs, not for writing code and running experiments. I still tried hard to steer clear of the research directions that looked very popular, but I really could no longer get the joy of writing proofs, nor the calm I’d had before. Now, two years later, I’ve grown used to my current identity and come to accept it—I can’t even understand anymore why my past self was so afraid of giving up theory, so afraid of working on a popular direction. Back then I simply just being too young too naive; every little thing seemed like a big deal, and I didn’t dare try anything outside of what I had mentally prepared myself for. Now I’ve become more nihilistic: once there are more things you don’t care about, you’re less afraid of losing them. And once you’ve seen enough data, you know that people can always adapt, little by little; you don’t need to keep yourself in the most comfortable environment all the time, and you don’t need to confine yourself to a box. (Writing blogs is the new thing that makes me feel calm. Writing my thoughts and experience down is actually quite a lot like writing proofs, except that when I wrote a proof, I felt I was presenting a perfect piece of work, and the recognition of those around me made me sure of it; when I write prose, my thoughts often drift far off, so, objectively speaking, I can’t produce a piece of work that would be called good by any objective standard. But one day, I suddenly realized that the people and the world around me are more accepting than I am to my work—things don’t have to be perfect before you can show them to others. (I tried a few more times after that and received a lot of positive feedback.) I didn’t post these writings on English social media; but I quietly put them on my homepage. (For Chinese versions I occasionally post on Chinese social media, hoping strangers with no connection to my life will read them) One day, I received an email in from a stranger who doesn’t speak Chinese, saying she really liked my blog, and that she can relate to what I write even though we have a quite different life trajectory. This kind of good moments are one of the reasons why I like writing: it is for in this enormous world, to briefly form a super weak connection with a stranger that you would have never had any relation with (i.e., form an edge in two atom in a world full of atoms), and then go back to being strangers. It was also because of this email that I later decided to proofread my English versions carefully in my future writings, instead of simply translating them from Chinese without further proof-reading.)</p>

  <p>At ICML 2024, even though I had already decided not to working on theory and spent most of my time talking to peers working on ML applications, three people who works on theory, whom I know when we were all applying PhD in 2023 happened to be at the conference too. One of them, Frank, invited us all for a city walk to catch up with each out, since we have each others contact but have never met in person. Being with them, I felt a bit out of place, because by then I could no longer follow the optimization theory and stochastic algorithms they were so heatedly discussing. I could only listen, envying them for still pursuing what they loved, even with so many LLM chaos all around. (Frank probably invited me along because, if when you grabbed a random person at ICML back then, the random person were most likely working on LLMs or something related. So unlike those who works on LLMs, who should be busy networking and talking with people in their own field—they could only grab people that they already know to catch up with.)</p>

  <p>At NeurIPS 2025, two of those three person I mentioned about attended. One had already switched to LLMs and was busy talking with other LLM people at the conference—too busy to hang out with us. Thus, Frank and me decided to catch up ourselves. He said that he and the third guy who l used to work on theory (the person who didn’t attend NeurIPS) were both preparing to switch to LLMs (Frank and I each conveyed to him with our most sincere and heartfelt longing through messages), and we also discussed things like switching research directions and finding internships. Because NeurIPS was in San Diego, a huge number of people came, and I also ran into a younger PhD student Jack. He too had switched from theory to LLMs, and was also very anxious. We discussed the state of the job market. By then there were already many PhDs graduating in only three or four years (I was job hunting at the time), and I was anxious in thinking that: if all those PhD students, who should have entered the market one or two years later suddenly flood in all at once, doesn’t it get even harder for not-so-outstanding PhDs like me, or for people who’ve only just switched their research directions, to find jobs? (On top of that, there were also many extremely talented first or second year PhDs who leave PhD program to join industry.) Jack, anxious but forcing himself to look on the bright side (he had only just started his second year), said, “Or maybe I’ll just stay in school through this turbulent period, and by the time I graduate the market will have stabilized again.”</p>

  <p>I also chatted with a peer I had once looked up to—a rising star in my eyes, the one who “could read in 30 minutes a proof that took me days to understand.” He said he had switched to LLMs in the past few months, but since others had several more years of experience than he did, he was slowly feeling his way forward, trying to catch up. Once again I didn’t know what to say. I thought: even those who once shone so brightly in their own field can feel lost and adrift when faced with something new. If he had stayed in his field, what a dazzling star he would have been. But LLMs have forced many people to abandon the directions they love and are good at, to work on something new, while others who got into it a little earlier already have a lot of experience. Sometimes I wonder: is it possible to catch up? Judging by most people’s examples, it seems that as long as you’re willing to work hard, willing to put in the time, and quick to grasp things, catching up is possible—and I’ve since seen many examples of successful transitions. Though I’m not one of the “willing to work hard, willing to put in the time, quick to grasp things” crowd (by now I’ve made peace with my own nature, so I just take things as they come and have no plans to catch up with anyone). But the those people I mentioned above—those who used to work on theory, they’ll surely catch up in the end, through their hard work and their brilliance.</p>

  <p>By 2026, almost every person met while applying for PhDs who used to work on theory had switched to LLMs. The trigger for writing this piece was that the friend Leo I mentioned earlier, the one who had wanted to go into quant, told me today that he just switched to LLMs this semester—he who had once been so resolute even in his most difficult time when he can’t find an advisor. He said he had only just changed directions, was still in the adjustment period, and was very unhappy due to the transitioning phase.</p>

  <p>As I write this, my mind is flooded with thoughts. Our PhDs—a mere three years, and yet it feels like such a long, long time has passed. So long that, unless I make an effort to remember, I’ll forget that many of those people and ephemeral moments ever existed. So long that when I sit down to write, I don’t know where to begin, or how to end. But these people and moments are still worth remembering. One of the reasons I originally wanted to work on ML theory was that I felt everyone in this fields was so nice (after all, everyone had plenty of free time, did research at an unhurried pace, and was very easygoing)—whether Leo, who didn’t usually hang out with me but showed up at my A exam to show his support, or Frank, whom I only knew each other online due to PhD applications, but were thoughtful enough to find a reason to hang out everytime when he know that we are attending the same conference. Our friendships feel so light and understated—so light that I often forget them constantly, and they might also forget me. But when something reminds us of each other, we can still catch up like old times. Even though so much has changed—we’ve all switched directions, and life and work have made us less idealistic than we were—there’s always something familiar that hasn’t changed. When we grow older, we stopped chatting with people without a specific purpose. Everyone has gotten into the habit of talking with a purpose (“with a purpose” isn’t meant as a criticism here; it’s more that a conversation needs a reason, and most of the time my reason is work or academic related). So I don’t know if we are friends or coworkers, since everying conversation feels like “meeting” or business chat.</p>

  <p>Those friendships with those old friends (who used to work on theory), though seem so light, yet don’t feel the least bit unfamiliar when picked up again a year later, are pure enough to leave me nostalgic and savoring.</p>

</div>

<div class="lang-content lang-zh" lang="zh" style="display: none;">

  <p>（备注：文中的名字都是我为了叙述方便随意起的，为保护朋友的的隐私， 我没有使用他们的真实姓名）</p>

  <p>原本想写成一个完美的书的结构，有序曲，有三个不同的章节（我的phd确实是阶段性的，几乎可以以年来划分, 化成三个章节，每个章节一个主题），有尾声。以至于在回国的飞机上了随便写了一些后，我开始花很长时间去思考怎么把我写的这些东西变得结构化，变成我心目中完美和完整的样子，再呈现给读者，结果就是，三周过去了，我在飞机上写的草稿却一直都没有完成。</p>

  <p>终于有勇气写这些不够完美的东西是因为，跟一位朋友聊天时，惊讶的发现他从理论转LLM了，顿时感慨颇多，想写些什么，想写的那些东西，本应放到我的phd回忆录里，但是我的回忆录却因为我对完美的追求，一直没有动笔。不知道是怎么养成的习惯，当把不完美的东西呈现给读者时，总要先道歉，诚实的列出所有我觉得不好的地方（这样看来，我真的是很不适合学术和创业了，不过phd经历的人和事，也让我学到了对自己少一些严苛，多一些包容）。所以，我就随意的，想到哪写哪吧，现实终究是不完美，不圆满的，如果要写的像文学作品，考虑读者的读感，我便会牺牲掉真实和随性，牺牲掉自己写作时的感受和心境的flow。而且，文学作平是有故事线的，现实则没有，我越来越能够接受世界的混沌，以及处于这个世界中的我的混沌（用褒义词叫”自由散漫”）。</p>

  <p>中午时随意打开了一篇知乎文章，看到一个朋友Leo的账号点赞了，于是微信给Leo发消息，我们已经很久没见了 ，想着和他catch up一下， 问问近况。他告诉我”他打算转去做LLM了，以及过去一年搬到了一个新的地方，和别人讲话讲的更少了”。虽然一年多没联系，聊天时还是熟悉的感觉。在23年申请phd的时候，我们都在做theory，但Leo的社交很少，不太会主动找别人玩，（他大部分时间都在做科研，读paper），但偶尔见到了我会和他聊聊天，因此，我对他的了解没有多到可以称为”熟悉”的地步。在我PhD A exam答辩的时候，他还来了（本来来的人也不多，而且，我的A exam我没有特意announce，只能在群发的邮件里看到，而他平常也不是喜欢去听presentation的人，我present的方向又和他感兴趣的方向毫不相关，所以，他注意到了，并腾出时间来，我觉得很感动）。Leo的博士之路十分坎坷，鉴于他的隐士风格，他应该不喜欢我告诉别人太多他的事情，所以我这里就省略掉好了。但即使他phd并不顺利，他一直是那么的平静和淡然，</p>

  <p>每次和周围一些人（尤其是男生）聊天，知道他们的经历时，我都会觉得，”我怎么这么不能吃苦，遇到多大点事儿，就开始吵吵闹闹，恨不得全世界都知道自己有多痛苦，有多难，同时，他们遇到更多更难的事情时，依然面无表情，平淡如水”。当然，这种自我pua的想法一般是转瞬即逝的，我倾向于以一个全面的，完整的态度看待事物，所以所有的事情都会有多个面和角度思考，并自由的掌握各个角度的权重，好处是，我不至于过于偏执以及opinionated，缺点是，有时候会让人觉得我没有个性，什么观点都能找到值得赞同的点。（又扯远了…</p>

  <p>2024 fall，我在考虑quit，Leo则在换导师以及找新的导师，我半开玩笑的说，”要不和我一起quit吧，你甚至都不用像我一样担心quit后对导师有啥影响，或者你别做理论了，换个做应用的导师吧？”（在cs系，如果Leo不在乎自己做的方向，找导师会容易很多）。但是他依然十分坚定，坚定的向我描述他想的career path。他把自己选择读phd包装成”是为了毕业后能去quant，拿到很高的工资”， 我不是很理解他的逻辑，因为在我看来，即使不读phd，或者不做理论，他也可以去做quant。但Leo却描述的像这是唯一一条路。我只是笑笑，因为，以我对他的了解，他是那种比较质朴的学术工作者， quant的”高工资”不至于让他如此坚定的去选择一条看起来更难的道路。（注意，我这里加了限定词”质朴的学术工作者”，是因为并不是所有的学术工作者都能被加上这个限定词，这也是我最开始进入学术圈时所犯的错误， 不过所有的东西都不是绝对的，不能片面的看待，当时的我只能看到人和事的某一面，并盲目的根据我所看到的东西，对事物进行定性，是我的问题。）</p>

  <p>或许是Leo的”隐士”风格让他能更少的听到世界的噪音，坚定的做他喜欢的事情，让他快乐的事情（做理论，写公式，以及读证明对一些人来说是快乐的呀）， 博一那一年，我也纠结了很久要不要放弃做理论，即使本科开始做理论的时候，就一直被本科的导师说，做理论不好招学生，不好拿funding，不好找工作…但当时，这就是能让我感到平静和快乐的事情，所以，这些现实的因素都不重要。我曾期待着自己可以一起做（所以我博士第一年其实是两边在一起做的）， 一方面，我没法放弃做理论，因为它让我感到平静，另一方面，我没法放弃做nlp，因为coding在过去几年里都是我的短板，如果我完全放弃做应用，它将再次成为我的短板。 （随之而来的便会是我的不自信，这种不自信会导致我没法站在一个客观，平等的角度看待很多的人和事， 对一些人抱有不应该有的滤镜）。就这样挣扎了一整年，最后，因为一个我不太喜欢的project，我最后决定不再做理论了。如果现在回看，我需要感谢这次命运的转折，因为我不再像以前一样分心了，之前，即使是理论和应用的project一起做，我也会prioritize 理论，因为它能让我快乐，我不在乎我是够做的够好，不在乎一个简单的证明我需要很久才能理解，也不在乎我的脑子和努力程度是否适合，我只在乎当下的快乐，以及这种慢悠悠的”一支笔，一本书，一个证明看很多天”的生活。 （虽然大佬们可能30min就看完了lol）。</p>

  <p>phd第二年开始后，我决定彻底放弃理论，专心的做llm和nlp时，当时是阵痛的，因为我不喜欢这么快的生活，也不喜欢写代码，我希望我的工具是纸和笔，我希望电脑是让我用来读证明的，而不是写code，做实验的。我依然努力去避免一些看起来很popular的方向，但确实不再能感受到在纸上写字的快乐了，也不再有之前的平静。两年后的现在，我已经习惯了并认同了现在的身份，甚至已经没法理解当时的自己为什么那么害怕放弃做理论，那么害怕做popular的方向。当时还是经历的太少，遇到一点事情就大惊小怪，不太感尝试自己心理预期之外的事情，现在则变得更加虚无主义，因为不在乎的东西多了，就不那么怕失去了，以及，见过的data多了，就知道，人总能逐渐适应的，不需要总把自己放在最舒适的环境里，也不需要把自己限制在一个框框里（现在写作是新的让我感到平静的事情，写作和写证明其实挺像的，只不过，写证明时，我觉得自己呈现了一副完美的作品，并且周围人的认可让我更确信这一点；写作的时候，我的思绪常常飘远，所以在客观的评价上，我没法呈现一个符合客观评价标准的好的作品。但是，某一天，我突然发现，周围的人和世界比我更加包容，不一定要做到完美，才能展现给别人（后面的试了几次，也收到了很多positive的feedback）。之前，我还是会觉得有点shapely，没把自己的文字发在英文的社交媒体上，只是静静的放在了我的主页上，（中文的版本则偶尔会放到一些中文的社交媒体上，希望与我生活无关的陌生人读到，但不希望熟人读到）。某一天，我收到一份陌生的英文邮件，说很喜欢我的blog，虽然她和我有着不同的经历，但我写的一些东西，她也有类似的感受。这应该就是写作的意义吧。在某一个时间点，和一个陌生人，短暂的建立一些链接，建立一条边，然后再做回陌生人（看起来没有什么意义的事情，可以人生本来就是没有意义的呢）。也因为这个邮件，在我后面的所有写作中，我都认真的校对我的英文版，而不是随意的用LLM翻译后直接放到我的主页上。</p>

  <p>24年ICML的时候，虽然当时的我已经决定了不再继续做理论，大部分时间都在和做applications人交谈。当时一起申请phd的 3个做理论的小伙伴刚好也在那儿开会，其中的一个人， Frank， 便约了我们一起city walk，我跟他们在一起，显得有些尴尬，因为那时的我已经听不懂他们在激烈讨论着的各种optimization theory和stochastic algorithm了，我只能一边听着，一边羡慕他们还在追求自己喜欢的东西，即使周围有那么多llm的声音。（Frank会叫上我一起玩，大概是因为，当时他在ICML随机抓取一个人，可能就是做LLM的或者相关方向的，所以他好像也不太能像大部分做llm的人一样，忙于社交，忙于和同方向的人交流，所以大概只能从微信列表里抓人了）</p>

  <p>25年 neurips的时候，我们上次开会一起玩的三个小伙伴里，来了两个，其中一个小伙伴已经转llm了，忙于和会上其他做LLM的人交流，忙到没时间一起玩，于是只剩Frank和我聊了很久，他说他以及剩下那个没来参会的小伙伴都准备转LLM了（当晚，我和Frank分别用发消息给他向他致以诚挚的思念）， 顺便讨论了些转方向，找实习之类的事情。因为neurips在san Diego，来的人非常多，我还再次见了一年半前见过的一个做理论的学弟，他也转LLM了，也很焦虑，我们讨论了一些就业市场的现状，那个时候，已经很多才第3年，4年便毕业的PhD了，（我当时也在找工作，想着三年毕业），我觉得，如果一群原本应该一年，两年后才进入市场的人一下子涌入市场，想我这样的本来就很普通的phd，或者是才开始转方向做LLM的人，是不是更难找工作了？（另外，还有一些phd 1， 2年级就on leave去industry的）， 学弟一边焦虑，努力乐观的往好的方向想（他那个时候刚刚博二），”或者这个动荡的时间点先在学校待着，等毕业的时候，市场已经恢复稳定了”， 而我则没有他那么乐观， 我只想着赶快逃离学校。</p>

  <p>当时还见到了一个我一度十分崇拜的一位做理论的peer，因为他是我心目中的rising star，那个”30min就能看完我需要看几天才能看懂的证明”的人， 而且即使他如此厉害而聪明，他依然对人很谦和，很nice。他说他最近几个月转了LLM，但毕竟别人比他多了几年的经验，所以他也在慢慢的摸索想要catch up。 我又一次不知道该说些什么，我想，原来那些曾今在自己领域熠熠生辉的人，面对新的东西，也会有迷茫和无所适从的时候呀，如果他继续待在他的那个领域，他会是多么耀眼的star 呀，可是LLM让很多人不得不放弃自己喜欢和擅长的方向，去做一个新的东西，而其他人早一点去做这个东西的人，已经有了很多的经验。有时候，我会觉得，这能够追得上吗？ 看大多数人的example，貌似是只要肯努力，愿意花时间，悟性强，便是可能可以追得上的，我后面也看到了很多转型成功的example，不过我不是”肯努力，愿意花时间，悟性强”的那群人中的一员，（目前已经和自己的天性和解，便得过且过，不打算追赶上谁了）， 但上面提到的这些做理论的朋友们，最后还是会凭他们的努力和聪明才智追上去的吧。</p>

  <p>到了2026年，我申请phd时认识的几乎所有做理论的朋友都已经转了llm。写下这个篇文章的trigger就是，我前面提到的那位之前想要做quant的朋友，今天告诉我他这学期转LLM了—那个当初那么难，依然如此坚定的他。他说自己刚换方向，还在磨合期，非常的不开心。</p>

  <p>当我写下这篇文章的时候，我思绪万千，我们的phd，短短三年，却又像过了好久好久了，久到很多人和事，不去努力回忆，就会忘记他们曾经存在过，久到在写作的时候不知从哪开始写起，不知道如何去收尾。这些人和事还是值得记录的，我之前想做理论的一个原因是，我觉得这个圈子里的人都很nice（毕竟，大家都比较闲，慢悠悠的做科研，又很随性），无论是我上面提到的平常不怎么一起玩，却会在我的A exam中show up来show his support的Leo，还是每次开会都想着一起聚一聚的Frank， 感觉大家的关系淡淡的，淡到我常常会忘记他们， 他们也常常忘了我，但在因为一些事情想起来的对方的时候，还是可以不带目的性的social和聊天，即使很多事情都变了，我们都转了方向，被生活和工作变得不再那么理想主义，但总有一些熟悉的感觉没有变。我刚刚才发现，自己已经很久没有不带工作目的的和别人聊过天了，大家也习惯性的带着目的聊天（”带着目的”在这里不是贬义词，更多的像是，聊天需要一个理由，大部分时间，都是工作和学术交流的目的， 我已经逐渐分不清他们是我的同事还是我的朋友了，或许他们两者都是， 习惯了之后，就觉得无所谓了）。 而和我那个曾经做理论的朋友们的这种，看起来淡淡的，但一年之后在拾起来依然不会觉得陌生的友谊，却纯粹到让我怀念和感动。</p>

</div>

<script>
(function() {
  var buttons = document.querySelectorAll('.lang-switcher .lang-btn');
  var contents = document.querySelectorAll('.lang-content');
  buttons.forEach(function(btn) {
    btn.addEventListener('click', function() {
      var lang = btn.getAttribute('data-lang');
      buttons.forEach(function(b) { b.classList.remove('active'); });
      btn.classList.add('active');
      contents.forEach(function(c) {
        if (c.classList.contains('lang-' + lang)) {
          c.style.display = '';
        } else {
          c.style.display = 'none';
        }
      });
    });
  });
})();
</script>]]></content><author><name>Jinyan Su</name><email>jinyansu6@gmail.com</email></author><category term="personal" /><category term="reflection" /><category term="life" /><category term="phd" /><category term="research" /><category term="theory" /><category term="llm" /><category term="friendship" /><summary type="html"><![CDATA[By 2026, almost every friend I met while applying for PhDs in 2023 who worked on theory had switched to LLMs. On giving up proofs for code, quiet friendships that survive years of silence, and three short years of a PhD that feel like a very long time.]]></summary></entry><entry><title type="html">英伟达为什么要保卫开放权重，以及它将如何重塑AI算力市场 / Why NVIDIA Is Defending Open-Weight Models—and How They Could Reshape the AI Compute Market</title><link href="https://jinyansu1.github.io/blog/2026/07/open-weights-letter-interest-map/" rel="alternate" type="text/html" title="英伟达为什么要保卫开放权重，以及它将如何重塑AI算力市场 / Why NVIDIA Is Defending Open-Weight Models—and How They Could Reshape the AI Compute Market" /><published>2026-07-30T00:00:00+00:00</published><updated>2026-07-30T00:00:00+00:00</updated><id>https://jinyansu1.github.io/blog/2026/07/open-weights-letter-interest-map</id><content type="html" xml:base="https://jinyansu1.github.io/blog/2026/07/open-weights-letter-interest-map/"><![CDATA[<div class="lang-switcher">
  <button type="button" class="lang-btn active" data-lang="en">English</button>
  <button type="button" class="lang-btn" data-lang="zh">中文</button>
</div>

<div class="lang-content lang-en" lang="en">

  <p>In mid-July, Moonshot released Kimi K3, a 2.8-trillion-parameter open-weight model that beat the flagships from OpenAI and Anthropic on the FrontierSWE coding benchmark. A few days later, Alibaba shipped a new version of Qwen. On July 20, Axios reported that the Trump administration was again pushing for a de facto ban on Chinese open-weight models; the instruments under discussion included Entity List designations, federal procurement restrictions, security advisories, liability rules, and pressure on US companies running Chinese models in production. Four days after that, on July 24, Jensen Huang used the first X post of his life to publish a policy letter titled “Open Weights and American AI Leadership.” The ask: Washington should not impose “premature restrictions” on downloadable AI models. The first version carried 25 corporate signatures, including NVIDIA, Microsoft, and Meta. Within a day it doubled to 50 — OpenAI and Google had signed; Amazon and Anthropic had not. By July 30, the official page hosted by Microsoft listed more than 230 signatories, and Amazon had appeared among them. The roster spans chips, servers, clouds, neoclouds, inference platforms, enterprise software, developer tools, and venture capital. Anthropic is the only frontier lab that has stayed away throughout.</p>

  <h2 id="two-ways-inference-demand-can-converge">Two ways inference demand can converge</h2>

  <p>The center of gravity in AI compute demand is shifting from training to inference. At a press Q&amp;A at CES 2026, Huang offered a figure: one out of every four tokens generated today comes from an open model. There are two extreme shapes that inference demand could converge toward:</p>

  <p><strong>(1) Concentrated.</strong> Demand pools into a handful of closed frontier model companies. Enterprises rent intelligence, and tokens flow out of a few API endpoints.</p>

  <p><strong>(2) Diffused.</strong> Demand sinks down to tens of thousands of enterprises, inference platforms, neoclouds, sovereign AI programs, and application companies, each running its own specialized model.</p>

  <p>Open weights are the condition that makes diffusion cheap and scalable. So this is a fight over market structure. And market structure determines whether NVIDIA faces five buyers or fifty thousand, and whether enterprises have any alternative to bring to the table when negotiating with closed APIs.</p>

  <h2 id="what-nvidia-wants-is-a-fragmented-buyer-base">What NVIDIA wants is a fragmented buyer base</h2>

  <p>On the surface, NVIDIA should be neutral on model paradigms — whether closed labs dominate or an open ecosystem does, both sides buy GPUs. As long as AI workloads grow, NVIDIA makes money.</p>

  <p>But NVIDIA cannot be neutral on the <em>structure</em> of its buyers. Its customer concentration is rising fast: in FY2026 Q3, four direct customers each accounted for more than 10% of total revenue, adding up to 61%; a year earlier it was three customers at 12% each, totaling 36%. We can only see concentration at the procurement layer, not the names of the end demand. But there is little disagreement in the market about who that procurement ultimately serves: Google, Amazon, Meta, Microsoft, OpenAI. And those same companies are the only ones capable of building an alternative to NVIDIA. Google has TPU, Amazon has Trainium, Meta has MTIA, Microsoft has Maia, and OpenAI is co-developing silicon with Broadcom. The weaknesses of these ASICs — narrow ecosystems, high CUDA migration costs — are not fatal for a hyperscale platform with a fixed internal workload, and those weaknesses are shrinking: both TPU and Trainium are now sold externally. Anthropic, for instance, uses Google TPU, AWS Trainium, and NVIDIA GPUs simultaneously, with the stated rationale of “matching the workload to the most suitable chip” — which is to say, large-scale frontier training can run on non-NVIDIA silicon. (NVIDIA is also one of Anthropic’s investors, so the two are not purely adversarial.) Which is why NVIDIA needs a world with a more fragmented buyer base. Tens of thousands of customers who can neither afford nor build their own chips are a far safer foundation than a few giants who are actively building substitutes. The Nemotron family, and the Nemotron alliance announced at GTC 2026 — with roughly $26 billion of company investment over five years — all indicate that NVIDIA is paying out of pocket to manufacture the fuel for a diffused world.</p>

  <p>(That said, as NVIDIA’s own 10-K risk factors note, open-source AI depends on developer adoption, and if it is deployed on competitors’ platforms it could reduce demand for NVIDIA’s products. Open weights push demand downward, but which silicon it lands on once it gets there is not NVIDIA’s call.)</p>

  <h2 id="sovereign-ai-a-new-national-scale-demand-category">Sovereign AI: a new national-scale demand category</h2>

  <p>Sovereign AI refers to an AI capability stack that a country builds and controls itself: compute located within its borders, models under its own legal jurisdiction, and training data that includes its own languages, public data, and industrial knowledge. Three forces drive it — data localization (healthcare, financial, government, and defense data not flowing to foreign APIs), national security (critical systems cannot depend indefinitely on foreign companies’ closed models and terms of service), and language and culture (leading frontier models under-serve a great many non-English languages, dialects, and administrative and legal systems).</p>

  <p>By NVIDIA’s own disclosure, sovereign AI revenue exceeded $30 billion for full-year FY2026, more than tripling year over year, with the main contributions coming from the UK, France, the Netherlands, Canada, and Singapore; FY2027 Q1 added new AI factory projects in Japan, South Korea, and Germany. The buyers of supercomputers used to be research institutions; the buyers of AI factories are finance ministries, defense ministries, national telecom operators, and sovereign wealth funds. Saudi money is betting on both tracks at once: domestically, PIF-owned HUMAIN is building gigawatt-scale compute and the Arabic model ALLAM, while Aramco Ventures led Together AI’s $800 million round in July, investing directly into the American open-weight inference layer. Nearly all of these countries are US allies, and nearly all of what they buy is NVIDIA. So what “sovereign AI” is actually doing at this stage is trading API dependence for chip dependence — and the chips still come from NVIDIA. For NVIDIA, sovereign AI is therefore a demand category that expands the number of buyers while posing no threat at all to its own moat.</p>

  <p>For policymakers, a country that can only call foreign closed APIs does not have real sovereign AI; it needs models it can download, inspect, deploy, fine-tune, and maintain over the long term. Kimi, DeepSeek, Qwen, and GLM are mostly released under permissive licenses like MIT, which is exactly what sovereign programs need. If the US restricts its own open models, sovereign AI programs will naturally turn to Chinese ones.</p>

  <h2 id="inference-providers-sell-model-utilization">Inference providers sell model utilization</h2>

  <p>Fireworks, Baseten, and Together are the most direct beneficiaries in this ecosystem. All three signed the letter. What they sell is the ability to turn a model into a production system: deployment, fine-tuning, adapters, distillation, autoscaling, GPU scheduling, and latency and cost optimization.</p>

  <p>Capital markets placed their bets on this layer in a dense three-month stretch:</p>

  <table>
    <thead>
      <tr>
        <th>Company</th>
        <th>Round</th>
        <th>Date</th>
        <th>Amount</th>
        <th>Valuation</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td>Baseten</td>
        <td>Series F</td>
        <td>2026-06-22</td>
        <td>$1.5B</td>
        <td>$11B / $13B (two tranches)</td>
      </tr>
      <tr>
        <td>Together AI</td>
        <td>Series C</td>
        <td>2026-07-01</td>
        <td>$800M</td>
        <td>$8.3B</td>
      </tr>
      <tr>
        <td>Fireworks</td>
        <td>Series D</td>
        <td>2026-07-16</td>
        <td>$1.505B</td>
        <td>$17.5B</td>
      </tr>
    </tbody>
  </table>

  <p>What these companies really are is open-weight inference foundries. Fireworks has disclosed that more than 95% of the tokens it serves come from models specialized on customer data: fine-tunes, adapters, distillations, and models customers trained themselves and brought over to be hosted. In that last case, the inference provider takes no part in training and handles only serving — it is paid for the production system after the model goes live.</p>

  <p>(A note: the service economics of adapters differ from traditional fine-tuning. Under the traditional logic, each customer gets its own copy of the model, and deployment costs are extremely high. Under multi-LoRA, one base model stays resident in GPU memory while hundreds of customer adapters are mounted on top of it, hot-swapped at the request level. The same fleet of GPUs serves a large number of customers’ “dedicated models,” and utilization is very high.)</p>

  <p>On cost: Fireworks CEO Lin Qiao says that at equivalent quality, the cost is 5–10x lower than closed models; Decagon, a Together customer, says its costs after migrating fell to between one-fifth and one-seventh of the closed-model alternative.</p>

  <p>The capability gap has also narrowed to a point where it can be negotiated with. Stanford’s 2026 AI Index puts the open–closed gap at 3.3 percentage points. When capability differs by a few points and price differs by a multiple, a large share of workloads will move to open-weight models — though the hardest ones will not.</p>

  <p><strong>Inference providers are not the SaaS of a new era.</strong> Ordinary SaaS can carry gross margins above 70% because marginal cost is near zero: one more user means a bit more server and bandwidth, not a linear increase in core cost. Inference providers face linear variable costs and cannot amortize fixed overhead through scale. Double the tokens served and the GPU bill roughly doubles too. Sacra estimates Fireworks’ gross margin at around 50%, against a company target of 60% — below SaaS’s 70%+, because GPU cost lands directly in COGS (cost of goods sold, i.e., the direct cost of delivering the product). Margin improvement therefore has to come from three directions: technical efficiency, moving up into customization, and moving down to lock in compute supply.</p>

  <p>Progress on the technical efficiency side is genuinely remarkable. Per SemiAnalysis and NVIDIA, Blackwell delivers roughly 30x the tokens/sec/GPU of Hopper a year earlier on frontier inference workloads, and the cost per million tokens is falling by order-of-magnitude increments annually (EpochAI’s figure is about 10x per year). But compute prices are rising at the same time. In April 2026, spot rental for H100s had risen from about $1.70/hour last October to $2.35; the Blackwell spot index went from $2.75 to $4.08/hour in two months. Unit compute prices are rising, but throughput is rising faster, so cost per token continues to fall. This means that even as competition keeps pushing token prices down, inference providers’ gross margins need not compress — as long as costs fall faster than prices. That said, Sacra’s risk assessment of Fireworks notes that if open-source frameworks like vLLM and SGLang close the performance gap, what remains is GPU resale at 50% margins.</p>

  <h2 id="circular-capital-courtesy-of-nvidia">Circular capital, courtesy of NVIDIA</h2>

  <p><strong>NVIDIA sells the cards and also invests in the people buying them.</strong> It is a shareholder in Fireworks, Baseten, and Together; it holds roughly 6% of CoreWeave and added a $2 billion private placement at $87.20 per share in January 2026 — and CoreWeave’s single largest expense, by order of magnitude, is buying NVIDIA GPUs. The money NVIDIA puts out comes back as demand for NVIDIA chips. So part of the demand on NVIDIA’s income statement is generated by its own capital rather than being fully exogenous market demand.</p>

  <h2 id="the-hyperscalers-three-layer-business">The hyperscalers’ three-layer business</h2>

  <p>Hyperscale clouds operate at three layers:</p>

  <p><strong>Layer one: bare GPU rental (IaaS).</strong> The customer rents an instance with eight H100s or B200s and installs the OS, drivers, inference framework, and model themselves, billed by the hour. AWS P5 and the Azure ND series sit here.</p>

  <p><strong>Layer two: managed model deployment (PaaS).</strong> The customer uploads or selects a model, the platform runs it and hands back an endpoint, with autoscaling, monitoring, and operations included. SageMaker and Vertex sit here.</p>

  <p><strong>Layer three: model-as-API (billed per token).</strong> The customer never sees a GPU and pays only for input and output tokens. Bedrock, Azure AI Foundry, the OpenAI API, the Anthropic API, and the Gemini API sit here.</p>

  <p>Each layer up generally produces higher revenue and higher margin from the same GPU. But the clouds’ positions are complicated.</p>

  <p><strong>Microsoft</strong> is OpenAI’s largest partner: tied to OpenAI on one side, developing its own MAI and the open-weight Phi family on another, and simultaneously selling everyone’s models on Azure rather than betting on a single one. <strong>Google</strong> has both Gemini and Gemma; it wants to sell closed APIs and also wants Vertex to be the platform where enterprises deploy every kind of model. <strong>Amazon</strong> is the subtler case. It has no genuinely first-tier frontier model of its own, and it shut down its AGI lab on July 22. Bedrock’s marquee offering has long been Anthropic. Amazon’s cumulative <strong>actual</strong> investment in Anthropic has reached roughly $13 billion, with up to another $20 billion tied to commercial milestones, for a cap of about $33 billion; in return, Anthropic has committed to spend more than $100 billion with AWS over the next decade and gets access to up to 5GW of Trainium capacity. Widespread open weights would erode Bedrock’s Anthropic-centered differentiation — but Amazon is also an IaaS provider and an aggregator, which is why, late as it was, it signed in the end.</p>

  <h2 id="fragmentation-is-a-survival-condition-for-neoclouds">Fragmentation is a survival condition for neoclouds</h2>

  <p>CoreWeave, Lambda, Nebius, and Crusoe — the neoclouds — operate at layer one: buying GPU clusters at scale, typically financed with debt, then renting out compute on long-term contracts. What separates them from the big three clouds is that they have only GPUs and no full cloud product line — no databases, no decades of enterprise customer relationships, no complete set of compliance certifications. So they can only compete on the price, delivery speed, and availability of raw compute. Open weights expand the number of entities that need to run their own GPUs, which is very much to the neoclouds’ benefit.</p>

  <p>But while fragmentation is a long-term survival condition for neoclouds, it is not the current state of affairs. CoreWeave’s FY2025 annual report shows Microsoft alone accounting for roughly <strong>67%</strong> of revenue (62% in FY2024), with no second customer above 10%; in Q1 2026 the top two customers together came to about 65%. Its contracted backlog is heavily concentrated in OpenAI (roughly $22.4 billion in cumulative commitments) and Meta (roughly $35.2 billion). At the same time it carries tens of billions of dollars in debt and 2026 capex guidance of $31–35 billion. In that structure, a single largest customer declining to renew could leave it insolvent.</p>

  <p>On top of that, its biggest customers are becoming its competitors. Meta, for example, is standing up a cloud business called Meta Compute to sell the surplus compute from its $115–145 billion of 2026 capex, in forms including model access through Muse Spark and raw GPU cycles. SpaceX’s Colossus site was leased in 2026 to Anthropic (roughly $45 billion through mid-2029), Google (roughly $30 billion), and Reflection ($6.3 billion). And OpenAI’s Stargate is the build-it-yourself path itself.</p>

  <p>Neoclouds hold no model assets and have nothing to win or lose at the model layer. What they can do is find enough buyers to fill capacity they have already bought with debt — an idle GPU is pure loss. Open-weight models expand the number of long-tail buyers (enterprises, sovereign AI programs, AI application companies, vertical model companies, inference platforms, research institutions), which is the most direct route to de-concentrating their customer base.</p>

  <h2 id="enterprise-bargaining-power">Enterprise bargaining power</h2>

  <p>Enterprises have data concerns, but the overwhelming majority of small and mid-sized companies will not actually buy cards and run models themselves.</p>

  <p>The reason is TCO (total cost of ownership). Self-hosting means not just buying GPUs but building and maintaining the infrastructure and employing the engineers to do it. Then there is utilization: an API is a purely variable cost — no calls, no spend — while owned GPUs are a fixed cost billed by the hour. Enterprise traffic is typically high during the day and low at night, so average utilization may be poor. A common industry rule of thumb is that self-hosting only becomes worth discussing once annual API spend reaches the seven-figure range — and that is before accounting for operational risk, hiring difficulty, and opportunity cost.</p>

  <p>The most important value of open weights to enterprises comes down to three things:</p>

  <p><strong>(1) Portability.</strong> No lock-in to a single API. If a vendor changes prices, retires a model, or changes its data policy, the enterprise has a migration path.</p>

  <p><strong>(2) Auditability.</strong> Holding the weights yourself means the model will not be swapped out or degraded without your knowledge, and in compliance settings you can reproduce the behavior of one specific version.</p>

  <p><strong>(3) Negotiating leverage.</strong> Even if the enterprise ends up using a closed API anyway, having an open alternative that is good enough for most tasks puts it in a completely different negotiating position. There is no stable relationship between a closed model’s marginal inference cost and its list price; list price is set mainly by competitors, substitutes, and willingness to pay. The existence of open-weight models effectively caps what closed models can charge.</p>

  <p>For an enterprise, if a single vendor controls the model, the pricing, the access, and the institutional knowledge the company has accumulated, then that vendor increasingly controls the company’s business.</p>

</div>

<div class="lang-content lang-zh" lang="zh" style="display: none;">

  <p>7 月中旬，Moonshot 发布 Kimi K3，一个 2.8 万亿参数的开放权重模型，在 FrontierSWE 编码基准上超过了 OpenAI 和 Anthropic 的旗舰。几天后阿里发布新版 Qwen。7 月 20 日，Axios 报道特朗普政府正在重新推动对中国开放权重模型的事实性封禁，讨论中的工具包括实体清单指定、联邦采购限制、安全公告、责任规则，以及对在生产环境使用中国模型的美国公司施压。四天后，也就是 7 月 24 日，Jensen Huang 用自己人生第一条 X 推文发了一封政策信，标题是《Open Weights and American AI Leadership》，诉求是：华盛顿不要对可下载模型（downloadable AI models）施加”过早的限制”（premature restrictions）。初版 25 家公司联名，包括 NVIDIA、Microsoft、Meta 等。一天之内翻倍到 50 家，OpenAI 和 Google 都签了，但 Amazon 和 Anthropic 没有。到 7 月 30 日，微软托管的官方页面显示签署方超过 230 家，Amazon 已经出现在名单上。名单横跨芯片、服务器、云、neocloud、推理平台、企业软件、开发者工具、VC。Anthropic 是唯一持续缺席的前沿实验室。</p>

  <h2 id="section">推理需求的两种收敛形态</h2>

  <p>AI 的算力需求重心正在从训练转向推理。Huang 在 CES 2026 的记者问答上给过一个数字：今天生成的每四个 token 里，就有一个来自开放模型。推理需求往哪里收敛，有两种极端形态：</p>

  <p><strong>（1）集中式</strong>：需求汇聚到少数闭源前沿模型公司，企业租用智能，token 从几个 API 端点流出。</p>

  <p><strong>（2）扩散式</strong>：需求下沉到几万家企业、推理平台、neocloud、主权 AI 项目和应用公司，每家跑自己特化过的模型。</p>

  <p>Open weights 是让扩散变得便宜、可规模化的条件。所以这是一场市场结构之争。而市场结构决定NVIDIA 面对的是五个买家还是五万个，以及企业在闭源 API 面前有没有替代品可以拿来谈判。</p>

  <h2 id="nvidia-">NVIDIA 想要的是一个分散的买方结构</h2>

  <p>表面上，NVIDIA 对模型范式应该中立——不管闭源实验室主导还是开放生态主导，两边都要买 GPU。只要 AI workload 增长，NVIDIA 都赚钱。</p>

  <p>但 NVIDIA 不可能对买方结构中立。它的客户集中度在快速上升：FY2026 Q3，四个直接客户各自超过总收入 10%，合计 61%；一年前是三家各 12%，合计 36%。 我们只能看到采购环节的集中，看不到终端需求方的名单。但这批采购最终服务于谁，市场上没有太多分歧：Google、Amazon、Meta、Microsoft、OpenAI。而这几家，同时是唯一有能力做 NVIDIA 替代品的公司。Google 有 TPU，Amazon 有 Trainium，Meta 有 MTIA，Microsoft 有 Maia，OpenAI 在和 Broadcom 合作自研。这些 ASIC 的短板——生态窄、CUDA 迁移成本高——对一个拥有固定内部 workload 的超级平台来说并不致命，而且短板还在缩小：TPU 和 Trainium 现在都在对外供给。比如，Anthropic 同时使用 Google TPU、AWS Trainium 和 NVIDIA GPU，公开的理由是”把 workload 匹配到最合适的芯片”， 也就是大规模前沿训练是可以跑在非 NVIDIA 硅片上的（当然，NVIDIA 也是 Anthropic 的投资方之一，双方不是纯粹的对立关系。）所以 NVIDIA 需要一个买方更分散的世界。几万个买不起、也做不了自研芯片的客户，比几个正在造替代品的巨头，是安全得多的客户基础。Nemotron 系列以及 GTC 2026 宣布的 Nemotron 联盟，公司称五年投入约 260 亿美元都indicate了它在自费制造扩散式世界的燃料。（当然，就像NVIDIA 自己的 10-K 风险因素里写的，开源 AI 依赖开发者采纳，如果它部署在竞争对手平台上，可能减少对 NVIDIA 产品的需求。开放权重让需求下沉，但下沉之后落在哪块硅上，并不由 NVIDIA 决定。）</p>

  <h2 id="ai">主权 AI：一个新的国家级需求类别</h2>

  <p>主权 AI 指一个国家自己建设、自己控制的 AI 能力栈：算力在境内，模型在本国法律管辖下，训练数据包含本国语言、公共数据和产业知识。推动力有三类——数据本地化（医疗、金融、政府、国防数据不流向外国 API）、国家安全（关键系统不能长期依赖外国公司的闭源模型和服务条款）、语言文化（主流前沿模型对英语以外的大量语言、方言、行政与法律体系支持不足）。</p>

  <p>按 NVIDIA 披露的口径，FY2026 全年主权 AI 收入超过 300 亿美元，同比增长三倍以上，主要贡献来自英国、法国、荷兰、加拿大和新加坡；FY2027 Q1 又新增日本、韩国、德国的 AI 工厂项目。过去买超算的是科研机构，现在买 AI 工厂的是财政部、国防部、国家电信商和主权基金。沙特的钱在两条路上同时下注：国内由 PIF 旗下的 HUMAIN 建吉瓦级算力和阿拉伯语模型 ALLAM，同时 Aramco Ventures 领投了 Together AI 7 月那轮 8 亿美元融资，直接投进美国的开放权重推理层。上面这批国家几乎全是美国盟友，买的几乎全是 NVIDIA。所以现阶段的”主权 AI”实际在做的，是用芯片依赖换掉 API 依赖，其芯片依然依赖NVIDIA。所以主权 AI对于Nividia是一个既能扩大买方数量、又完全不威胁自身护城河的需求类别。</p>

  <p>对政策制定者来说，一个国家如果只能调用外国闭源 API，它就没有真正的主权 AI；它需要能下载、检查、部署、微调、长期维护的模型。Kimi、DeepSeek、Qwen、GLM 大多以 MIT 一类的宽松许可发布，这正是主权项目需要的。如果美国限制自己的开放模型，主权 AI 项目会自然转向中国的模型。</p>

  <h2 id="section-1">推理厂卖模型的利用率</h2>

  <p>Fireworks、Baseten、Together 是这轮生态里最直接的受益方。三家都签了那封信。它们卖的是”把模型变成生产系统”的能力：部署、微调、adapter、蒸馏、自动扩缩容、GPU 调度、延迟与成本优化。</p>

  <p>资本市场在这一层的下注，三个月内密集落地：</p>

  <table>
    <thead>
      <tr>
        <th>公司</th>
        <th>轮次</th>
        <th>时间</th>
        <th>金额</th>
        <th>估值</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td>Baseten</td>
        <td>Series F</td>
        <td>2026-06-22</td>
        <td>15 亿美元</td>
        <td>110 亿 / 130 亿两档</td>
      </tr>
      <tr>
        <td>Together AI</td>
        <td>Series C</td>
        <td>2026-07-01</td>
        <td>8 亿美元</td>
        <td>83 亿美元</td>
      </tr>
      <tr>
        <td>Fireworks</td>
        <td>Series D</td>
        <td>2026-07-16</td>
        <td>15.05 亿美元</td>
        <td>175 亿美元</td>
      </tr>
    </tbody>
  </table>

  <p>这类公司的本质是 open-weight inference foundry。Fireworks 披露，它服务的 token 里超过 95% 来自在客户数据上特化过的模型：包括微调、adapter、蒸馏，以及客户自己训完拿来托管的模型。在最后一种情况下，推理厂不参与训练，只负责 serving，收的是模型上线后的生产系统的钱。</p>

  <p>（注：adapter的服务经济学和传统 fine-tuning 不同。传统逻辑里，每个客户一份模型，部署成本极高。multi-LoRA 逻辑下，一份基础模型常驻显存，同时挂载几百个客户的 adapter，请求级别热切换。同一批 GPU 服务大量客户的”专属模型”，利用率极高。）</p>

  <p>从成本的角度，Fireworks CEO Lin Qiao 说同等质量下成本比闭源模型低 5–10 倍；Together 的客户 Decagon 说迁移后成本降到闭源方案的五分之一到七分之一。</p>

  <p>能力差距也小到了可以谈判的程度。斯坦福 2026 AI Index 给出的开闭源差距是 3.3 个百分点。当能力差几个百分点而价格差是数倍，大量工作负载会转向开放权重模型（虽然最难的那批不会）<strong>。</strong></p>

  <p>推理厂并不是新时代的 SaaS。 普通 SaaS 毛利可以超过 70%，因为边际成本接近零：多一个用户，多一些服务器和带宽，不会线性增加核心成本。推理厂则是线性可变成本，不能靠规模把固定开销摊薄。服务的 token 翻倍，GPU 账单大体也翻倍。Sacra 估计 Fireworks 毛利约 50%，公司对外目标 60%，低于 SaaS 的 70%+，因为 GPU 成本直接进 COGS(营业成本, i.e.， 交付产品的直接成本)。所以毛利改善主要来自三个方向：技术效率、往上做定制化、往下锁算力供给。一方面，硬件效率的提升速度确实惊人：SemiAnalysis 与 NVIDIA 的口径是，Blackwell 在前沿推理 workload 上的 tokens/sec/GPU 大约是一年前 Hopper 的 30 倍；每百万 token 的成本按年以数量级速度下降（EpochAI 的口径是每年约 10 倍）。但算力价格同时在涨。2026 年 4 月，H100 现货租赁从去年 10 月的约 1.70 美元/小时涨到 2.35 美元；Blackwell 现货指数两个月内从 2.75 涨到 4.08 美元/小时。虽然算力单价在涨，但吞吐涨得更快，所以每 token 的成本仍在下降。这意味着即使竞争持续把 token 售价打下来，只要成本降得比售价更快，推理厂的毛利率就未必被压缩。 当然，Sacra 对 Fireworks 的风险判断里提到：如果 vLLM、SGLang 这类开源框架把性能优势追平，剩下的就是 50% 毛利的 GPU 转售。</p>

  <h2 id="nvidia--1">由 NVIDIA 催生的循环资本</h2>

  <p>NVIDIA 既卖卡，也投资买卡的人。 它是 Fireworks、Baseten、Together 的股东；持有 CoreWeave 约 6% 股份，并在 2026 年 1 月以 87.20 美元/股追加了 20 亿美元定增，而 CoreWeave 数量级上最大的开支就是买 NVIDIA GPU。所以NVIDIA 出的钱，最终还是变回了对 NVIDIA 芯片的需求。所以 NVIDIA 报表上的一部分需求，是它自己的资本催生出来的，而不是完全外生的市场需求。</p>

  <h2 id="section-2">大型云厂商的三层生意</h2>

  <p>超大云厂分三层：</p>

  <p><strong>第一层：裸 GPU 出租（IaaS）。</strong> 客户租一台带 8 张 H100 或 B200 的实例，操作系统、驱动、推理框架、模型都自己装，按小时计费。AWS P5、Azure ND 系列在这一层。</p>

  <p><strong>第二层：托管模型部署（PaaS）。</strong> 客户上传或选择一个模型，平台帮你跑起来，给一个 endpoint，自动扩缩容，带监控和运维。SageMaker、Vertex 在这一层。</p>

  <p><strong>第三层：模型即 API（按 token 计费）。</strong> 客户看不到 GPU，只按输入输出 token 付钱。Bedrock、Azure AI Foundry、OpenAI API、Anthropic API、Gemini API 在这一层。</p>

  <p>每往上一层，同一块 GPU 产生的收入和毛利通常更高。但云厂商的立场比较复杂。</p>

  <p>Microsoft 是 OpenAI 最大合作方：一边和 OpenAI 绑定，一边自研 MAI 与开放权重的 Phi 系列，同时还在 Azure 上卖各家模型，而非押注单一模型。<strong>Google</strong> 有 Gemini 也有 Gemma；既想卖闭源 API，也想让 Vertex 成为企业部署各种模型的平台。<strong>Amazon</strong> 则比较微妙。它没有真正一线的自有前沿模型，并在7月22号关闭了AGI lab。Bedrock 的招牌长期是 Anthropic。Amazon 对 Anthropic 的累计<strong>实际</strong>投资已达约 130 亿美元，另有最高 200 亿与商业里程碑挂钩，上限合计约 330 亿；同时 Anthropic 承诺未来十年向 AWS 投入超过 1000 亿美元，并获得最高 5GW Trainium 产能。open-weight 普及会削弱 Bedrock 围绕 Anthropic 的差异化，但 Amazon 同时是 IaaS 和聚合器，所以虽然签得晚，它最终也签了。</p>

  <h2 id="neocloud">分散是Neocloud的生存条件</h2>

  <p>CoreWeave、Lambda、Nebius、Crusoe 这类 neocloud 做的是上一节说的第一层：大规模采购 GPU 集群，通常靠债务融资，然后以长期合约出租算力。它们和三大云的区别在于只有 GPU，没有完整云产品线——没有数据库、几十年的企业客户关系、全套合规认证。所以只能在裸算力上打价格、交付速度和 GPU 可得性。 open weights扩大了”需要自己跑 GPU 的实体数量”， 所以对neocloud非常有利。</p>

  <p>虽然分散是 neocloud 的长期生存条件，却不是当前状态<strong>。</strong> CoreWeave 的 FY2025 年报显示，Microsoft 一家占其收入约 <strong>67%</strong>（FY2024 是 62%），除微软外没有第二个客户超过 10%；2026 年 Q1 前两大客户合计约 65%。合约储备高度集中在 OpenAI（累计承诺约 224 亿美元）和 Meta（累计约 352 亿美元）身上。同时它背着数百亿美元级的债务和 310–350 亿美元的 2026 年 capex 指引。在这种结构下，最大客户不续约可能会让它们资不抵债。</p>

  <p>此外，他们最大的客户正在变成自己的竞争对手。比如，Meta 正在筹建名为 Meta Compute 的云业务，把自己 2026 年 1150–1450 亿美元 capex 买来的多余算力对外出售，形式包括 Muse Spark 的模型访问和裸 GPU 周期。<strong>SpaceX的</strong>Colossus 站点在 2026 年租给了 Anthropic（约 450 亿美元至 2029 年中）、Google（约 300 亿美元）、以及 Reflection（63 亿美元）。而OpenAI的Stargate 是自建路线本身。</p>

  <p>neocloud 没有模型资产，在模型层没有输赢。它们能做的就是找到足够多的买家，来填满已经用债务买下来的产能， 否则空转的 GPU 是纯亏损。open-weight 模型扩大长尾买家的数量（企业、主权 AI、AI 应用公司、垂直模型公司、推理平台、研究机构），是去客户集中化最直接的一条路。</p>

  <h2 id="section-3">企业客户的议价权</h2>

  <p>虽然企业有数据上的顾虑，但绝大多数中小企业不会真的自己买卡跑模型。</p>

  <p>原因是 TCO（Total Cost of Ownership）。自部署不仅要采购 GPU，还要搭建和维护基础设施，以及养相应的工程师。此外还有利用率的考量：API 是完全可变成本，不调用就不花钱；自有 GPU 是固定成本，按小时计费。企业流量通常白天高、晚上低，平均利用率可能不高。业内常见的经验值是，每年 API 支出到百万美元量级，自建才开始有讨论的意思（这还没算运维风险、招聘难度和机会成本）。</p>

  <p>open-weight 对企业最重要的价值在于三点：</p>

  <p><strong>（1）可移植性。</strong> 不被单一 API 锁死。如果供应商改价、退役模型、改变数据政策，企业能有迁移路径。</p>

  <p><strong>（2）可审计性。</strong> 权重固定在自己手上，意味着模型不会在你不知情时被更换或降级；合规场景下能复现某个具体版本的行为。</p>

  <p><strong>（3）议价筹码。</strong> 即使最后还是用闭源 API，手上有一个大部分任务都够用的开放替代，企业的谈判位置完全会很不一样。闭源模型的边际推理成本和标价之间没有稳定关系，标价主要看竞品、替代品和客户愿付能力。open-weight 模型的存在，相当于给闭源模型的价格设了一个上限。</p>

  <p>对企业来说，如果一个供应商控制了模型、定价、访问权和企业积累的机构知识，它就在越来越大的程度上控制企业的生意。</p>

</div>

<script>
(function() {
  var buttons = document.querySelectorAll('.lang-switcher .lang-btn');
  var contents = document.querySelectorAll('.lang-content');
  buttons.forEach(function(btn) {
    btn.addEventListener('click', function() {
      var lang = btn.getAttribute('data-lang');
      buttons.forEach(function(b) { b.classList.remove('active'); });
      btn.classList.add('active');
      contents.forEach(function(c) {
        if (c.classList.contains('lang-' + lang)) {
          c.style.display = '';
        } else {
          c.style.display = 'none';
        }
      });
    });
  });
})();
</script>]]></content><author><name>Jinyan Su</name><email>jinyansu6@gmail.com</email></author><category term="technical" /><category term="ai" /><category term="open-weights" /><category term="inference" /><category term="nvidia" /><category term="cloud" /><summary type="html"><![CDATA[Open weights are not just a model-release choice; they reshape who buys compute, who controls inference demand, and how much bargaining power enterprises have against closed APIs.]]></summary></entry><entry><title type="html">The Evolution of Agents: From Context Engineering to Long-running Harnesses / Agent 从 Context Engineering 到 Long-running Harness 的演变过程</title><link href="https://jinyansu1.github.io/blog/2026/07/agent-context-engineering-long-running-harness/" rel="alternate" type="text/html" title="The Evolution of Agents: From Context Engineering to Long-running Harnesses / Agent 从 Context Engineering 到 Long-running Harness 的演变过程" /><published>2026-07-06T00:50:00+00:00</published><updated>2026-07-06T00:50:00+00:00</updated><id>https://jinyansu1.github.io/blog/2026/07/agent-context-engineering-long-running-harness</id><content type="html" xml:base="https://jinyansu1.github.io/blog/2026/07/agent-context-engineering-long-running-harness/"><![CDATA[<div class="lang-switcher">
  <button type="button" class="lang-btn active" data-lang="en">English</button>
  <button type="button" class="lang-btn" data-lang="zh">中文</button>
</div>

<div class="lang-content lang-en" lang="en">

  <blockquote>
    <p><strong>Important Note:</strong> Although I try to keep academic/technical blog posts serious, I still cannot help inserting some completely unrelated things while writing. To avoid polluting the context, I will use the <code class="language-plaintext highlighter-rouge">/btw</code> command to separate them from the technical parts. Readers can skip these “by the way” sections.</p>
  </blockquote>

  <p>Over the past few years, the main thread of progress in large models has mostly revolved around “the model itself”: parameters, data, pretraining, post-training, and reasoning. In the early days, when we talked about agents, the most common definition was also very simple: LLM + tool use. Later, this gradually became context engineering: managing the context the model sees at each inference step, so that multi-turn tool use is not drowned by history, noise, tool definitions, and intermediate results. Later still, as tasks evolved into long-horizon tasks, agent capability became a system capability composed of the model, harness, context, tools, evals, sandbox, and state management together: within a finite context, external tools, and a changing environment, the agent must keep pushing toward a goal and get closer to completion over time.</p>

  <p>In this blog, we mainly focus on context engineering and long-running harnesses.</p>

  <p>Context engineering grew out of prompt engineering. When an agent changes from a single-turn answering system into a multi-turn action system, the input the model sees at inference time changes too. It is no longer a relatively independent external input, namely a prompt, but a context related to the model’s continuous interaction with tools and the environment. This context may include tool definitions, file contents, web observations, historical messages, test outputs, MCP server descriptions, external documents, progress records, and so on. Context engineering decides which information should be placed in the prompt up front, which should be retrieved on demand, which should be written into external memory, and which should be handled by code or tools rather than stuffed into the model context. Anthropic systematically explained this concept in <a href="https://www.anthropic.com/engineering/effective-context-engineering-for-ai-agents"><em>Effective context engineering for AI agents</em></a> in September 2025. A concrete context engineering example is: when there are too many MCP tools and too much data, we should not let every tool definition and intermediate result flow through context. Instead, the agent should write code to call tools on demand, filter the data, and bring only high-signal results back to the model. Context engineering also includes compaction, structured note-taking, and even multi-agent patterns, but these mostly serve the question of “how should context be managed?” The long-running agent harness discussed later goes one step further: it does not only manage context, but separates planning, implementation, evaluation, revision, and final acceptance into different processes.</p>

  <p>By the end of 2025, as coding agents became able to make longer continuous progress on software engineering tasks, the center of gravity quickly shifted toward long-running agent harnesses: from the initial focus on the model’s coding ability to the ability to continue executing a task across multiple context windows / sessions. In November, Anthropic released <a href="https://www.anthropic.com/engineering/effective-harnesses-for-long-running-agents"><em>Effective harnesses for long-running agents</em></a>, which can be viewed as the first version of the long-running harness. The system started to shift from “managing one agent’s context” to “managing multiple sessions.” This version of the harness introduced a minimal role split between an initializer agent and a coding agent. The initializer’s role is to establish an external project state that can be handed off: it breaks the task into a smaller feature list, writes a progress file, creates an init script, initializes a git repo, and marks each feature as pending. Later, each coding agent session only advances one bounded increment, such as implementing one feature or fixing one specific issue. The harness requires it to test, update records, commit, and leave the repo in a clean state before ending. That way, even if the next session starts from a new context, it can reconnect to the task through the progress file, feature list, git log, and test results.</p>

  <p>In January 2026, Anthropic published <a href="https://www.anthropic.com/engineering/demystifying-evals-for-ai-agents"><em>Demystifying evals for AI agents</em></a>. This article systematized agent evals: because agents act in environments, call tools, and modify state over multiple turns, evals cannot only look at the final sentence. They also have to look at the transcript / trajectory and whether the final environment state is actually correct. Roughly speaking, it makes two points. One is task-level: how do we determine that the agent really did the task and did it well, rather than producing something that looks acceptable on the surface but is actually buggy or incomplete? The other is harness-level: we also need to evaluate whether each component of the harness is actually load-bearing, rather than just adding useless stuff.</p>

  <p>By March 2026, in <a href="https://www.anthropic.com/engineering/harness-design-long-running-apps"><em>Harness design for long-running application development</em></a>, this idea became the second version of the harness: initializer + coding agent was expanded into planner + generator + evaluator. The evaluator uses Playwright MCP to operate the application like a user, test UI, API, and database state, and reject outputs that fail certain criteria. Whether this evaluator should exist depends on whether the task exceeds the current model’s reliable solo capability. For example, on Opus 4.5 it was clearly useful; by Opus 4.6, the model itself had become stronger, and some scaffold could be removed or weakened. These adjustments and transitions naturally make us think about a longer-term system design problem (see their April post <a href="https://www.anthropic.com/engineering/managed-agents"><em>Scaling Managed Agents</em></a>): a harness is not a fixed structure, but co-evolves with model capability. Earlier Sonnet 4.5 / Opus 4.5 had context anxiety and would under-scope, so they needed more scaffold: context reset, sprint decomposition, evaluator feedback loops. But by Opus 4.6, the model itself was better at long-running agentic tasks, code review, debugging, and long-context retrieval. Some structures that were originally necessary started to become less necessary. For tasks the model can already complete reliably solo, an evaluator may no longer be worth the cost. Of course, for tasks that sit just beyond the model’s capability boundary, an evaluator can still bring real lift. Many designs in a harness essentially contain assumptions about “what the current model cannot do well.” After the model upgrades, these assumptions may no longer hold. So we should not treat one generation of harness as an architecture that can be used forever. Instead, we should split the system into relatively stable abstractions: use sessions to record what happened, use the harness to manage the agent loop and tool use, use the sandbox to provide a controlled execution environment, and so on. This way, the underlying harness can keep being replaced, but the agent product is not tied to one generation of scaffold.</p>

  <h2 id="context-engineering"><strong>Context engineering</strong></h2>

  <p>People used to focus on prompt engineering, namely how to write the system prompt. But as agents become more multi-turn and longer-running, the focus becomes: at each inference step, what did the model see? For example, an agent’s context may contain the system prompt, developer instructions, tool definitions, MCP server descriptions, user messages, conversation history, file contents, command output, browser observations, screenshots, errors, progress notes, retrieved documents, evaluator feedback. These things cannot all be blindly stuffed in. Even if the context window becomes larger, we still need to choose selectively, because noise in a long context distracts the model and increases cost and latency. So a good context is the minimal high-signal context that lets the model complete the next step at the current step. In general, we use just-in-time context: instead of stuffing all documents, tools, and history into the model, we keep references, such as paths, URLs, commit hashes, log files, database table names, and so on. When the model needs them, it loads them through tools. In this way, the agent’s working memory keeps indexes and currently relevant fragments, rather than all of the context.</p>

  <p>Common context techniques in long tasks include:</p>

  <ul>
    <li>
      <p><strong>Compaction:</strong> When the context is almost full, compress the current conversation trace into a summary, then use that summary to start the next context. Usually this is still the continuation of the same task and the same agent loop. Its goal is to preserve conversational continuity as much as possible. In other words, the model should feel that “what I was just doing is still here”; only the history has been compressed.</p>
    </li>
    <li>
      <p><strong>Structured note-taking:</strong> Let the agent actively write task state into persistent external artifacts, such as <code class="language-plaintext highlighter-rouge">progress.md</code>, <code class="language-plaintext highlighter-rouge">feature_list.json</code>, <code class="language-plaintext highlighter-rouge">NOTES.md</code>, or git commits. It is not necessarily only for the same task. A project-level <code class="language-plaintext highlighter-rouge">NOTES.md</code> can be read by later sessions, by planner/generator/evaluator, or reused in neighboring tasks.</p>
    </li>
    <li>
      <p><strong>Context reset:</strong> Use external artifacts, such as files produced by note-taking, git logs, test results, task lists, and so on, as startup material to open a clean new context/session. It does not preserve the full conversation history, and can clear noise and bad assumptions so that a new agent can reorient itself.</p>
    </li>
    <li>
      <p><strong>Multi-agent architecture:</strong> Do role division and context isolation. Different agents receive different context, do different subtasks, and finally pass only high-density results back to the main flow.</p>
    </li>
  </ul>

  <h2 id="tool-use"><strong>Tool use</strong></h2>

  <p>There are also some things to watch out for in tool use. For example, the number of tools cannot expand without limit, otherwise the model wastes attention on choosing. Tools should not overlap too much in functionality, otherwise the model does not know which one to use. Tool descriptions should clearly explain when to use them and when not to use them, namely they should make the boundaries clear. Return values should be token-efficient and should not pour irrelevant data into context. Returned error messages should let the model know what to repair next. Names should be clear, so the agent can infer boundaries from the names. Also, tools are preferably not exposed directly to the model as direct tool calls, but mapped into code APIs / a file tree, so the agent can call them through code. This way, the agent can read only the tool definitions it currently needs, filter large data inside the code execution environment, and return only summaries or a small number of results to the model. It can use loops, conditionals, and exception handling to complete complex control flow, or write intermediate state into files instead of stuffing it into context. Tool outputs are deterministic; we should leave deterministic computation to code. Judgment and planning, such as how to call tools, which tools to call, in what order, and how many times, should be left to the model.</p>

  <h2 id="the-problem-of-long-running-agents"><strong>The problem of long-running agents</strong></h2>

  <p><strong>1. Context window</strong></p>

  <p>Long tasks will definitely exceed a single context window. Even if the model supports a very long context, context is always a finite resource: every extra piece of information consumes part of the model’s attention budget. This brings three common phenomena:</p>

  <ul>
    <li>
      <p><strong>Amnesia:</strong> A new session does not know what the previous session did.</p>
    </li>
    <li>
      <p><strong>Context rot:</strong> The longer the context, the easier it is for the model to lose the point; earlier information gets buried by noise.</p>
    </li>
    <li>
      <p><strong>Context anxiety:</strong> When the model feels that it is approaching the end of the context, it rushes to wrap things up and calls a half-finished product complete.</p>
    </li>
  </ul>

  <p><strong>2. Planning and hand-off</strong></p>

  <p>Many complex tasks contain dozens of mutually dependent features, bugs, design decisions, and validation steps. If the model starts directly from a high-level prompt, it easily tries to do everything at once, then runs out of context halfway through, leaving something that appears to have a lot of work in it but does not actually work. Also, even if some things are useful for the next agent, the next agent does not know which things are useful: is something that looks like a bug intentionally made that way, or is it something the previous session did not have time to clean up?</p>

  <blockquote>
    <p>/btw</p>

    <p>I believe many of you, in PhD work or at work, have had the experience of inheriting a collaborator’s mess. Although by the late stage of my PhD, around December 2025, agents were developing so fast that I felt a lot of anxiety and insecurity, deeply felt that I could no longer stay in academia, and had completely lost the motivation to keep publishing papers, I also became the kind of person I once disliked: someone who leaves collaborators with a pile of messes.</p>
  </blockquote>

  <p><strong>3. Self-evaluation</strong></p>

  <p>The model does not necessarily judge what it generated strictly. It may see that a button shows up and think the feature is complete; see that a page roughly looks right and think the design is good; or run part of the tests and think the whole system is usable. In Anthropic’s long-running application harness post, they mention that letting the same agent be both generator and reviewer often leads to overly lenient judgments. Especially for front-end design, product completeness, and edge interactions, where there is no unit test directly defining the thing, the model can easily convince itself.</p>

  <blockquote>
    <p>/btw</p>

    <p>After all, the world is a giant makeshift operation, and models have learned a lot from us. Also, a lot of the time, people only need to convince themselves.</p>
  </blockquote>

  <h2 id="harness"><strong>Harness</strong></h2>

  <p>An agent harness, also called a scaffold, is the system that allows a model to act as an agent. It handles inputs, organizes tool calls, manages state, executes loops, and returns results to the model. It includes the file system, task board, test scripts, browser, shell, git, logs, sandbox, permission system, checkpoints, handoff notes, and so on.</p>

  <p>The core design of the first generation of long-running harnesses was quite simple. It mainly used two types of agents:</p>

  <ul>
    <li>
      <p><strong>Initializer agent:</strong> Runs at the very beginning to set up the working framework and environment.</p>
    </li>
    <li>
      <p><strong>Coding agent:</strong> Makes incremental progress session by session, and leaves structured handoff artifacts before ending.</p>
    </li>
  </ul>

  <p>The initializer agent does several things.</p>

  <p><strong>1. Create a task list.</strong></p>

  <p>For example, if the user only says “build a claude.ai clone,” the initializer does not let later agents directly start building. Instead, it breaks the task into many verifiable features, such as creating a new chat, entering a message, pressing Enter to send, receiving a response, switching themes, loading historical conversations, and so on. Each feature’s initial status is marked failing.</p>

  <p><strong>2. Create a progress file.</strong></p>

  <p>For example, <code class="language-plaintext highlighter-rouge">claude-progress.txt</code> or a similar file records what each round did, what remains, and what later agents should pay attention to.</p>

  <p><strong>3. Create a startup script.</strong></p>

  <p>For example, <code class="language-plaintext highlighter-rouge">init.sh</code> tells later agents how to install dependencies, start the service, and run basic checks.</p>

  <p><strong>4. Initialize a git repo.</strong></p>

  <p>At the end of each round, commit. This way, later agents can understand recent changes through <code class="language-plaintext highlighter-rouge">git log</code>, and the system can roll back, diff, and audit.</p>

  <p>Later coding agents roughly do three parts:</p>

  <ol>
    <li>
      <p>Understand the current engineering state they are receiving (<strong>orient</strong>): confirm the current working directory, read the progress file and feature list, look at the recent git log, and run an end-to-end test to confirm that the basic functionality is not broken.</p>
    </li>
    <li>
      <p>Select and finish one feature (<strong>select &amp; implement &amp; validate</strong>): choose the highest-priority unfinished feature, implement one relatively independent increment, test it, and evaluate that feature.</p>
    </li>
    <li>
      <p>Hand off a clean state to the next round, so that the current code can be understood by the next agent: for example, update the feature status and progress file and commit. If a new feature is not finished, leave a clear boundary instead of pretending it is done.</p>
    </li>
  </ol>

  <p>A long-running agent is essentially using multiple short sessions to stitch together one long task. If every session leaves behind a small mess, errors compound with interest. So a harness should not only reward “verifiable increments,” but also reward the state of the system it leaves behind. If a session writes three more features but breaks the startup flow, the next round may have to spend a large number of tokens first recovering the environment. In the long run, this kind of progress is actually negative return.</p>

  <h2 id="the-three-roles-of-planner--generator--evaluator"><strong>The three roles of planner / generator / evaluator</strong></h2>

  <p>The first-generation harness solved the context handoff problem, but there was still one big problem: agents are not good at judging themselves. So Anthropic introduced a multi-agent structure in the second generation. The final form roughly contains three roles:</p>

  <ul>
    <li>
      <p><strong>Planner:</strong> Expands the user’s high-level prompt into a specification, feature list, design direction, and implementation plan.</p>
    </li>
    <li>
      <p><strong>Generator:</strong> Implements features according to the plan: writes code, changes UI, connects the backend, and runs tests.</p>
    </li>
    <li>
      <p><strong>Evaluator:</strong> Acts like QA, operates the application, checks the result, points out problems, and decides whether it passes.</p>
    </li>
  </ul>

  <p>Different roles correspond to different failure modes.</p>

  <p>Planner solves under-scoping. Without a planner, the generator often understands the task too narrowly. For example, for “build a 2D retro game maker,” a single agent might build a page where you can place some tiles and think it is done. The planner expands it into more complete product specifications such as a level editor, sprite editor, entity behavior, playable test mode, animations, export, sound effects, AI-assisted generation, and so on.</p>

  <p>Generator solves execution. It is still the main labor force, but it no longer decides the entire product boundary from nothing; it works inside a clear spec and current feature contract. Generator also does not have to be a single agent. It is more like a role: multiple generator sessions or coding agents sequentially hand off execution. Each round of generator reads the planner spec, current code, progress file, and previous evaluator feedback, then completes a bounded increment, writes state back, and exits. The next generator then reads these artifacts and continues. So the continuity of a long-running harness is placed in external project state, such as progress files, feature lists, git commits, and test results.</p>

  <p>Evaluator solves self-evaluation. It is not just reading code and then giving a score or feedback; it operates the application through Playwright or browser automation like a user, checking UI functionality, APIs, database state, and edge cases. So this moves from previous LLM-as-a-judge to agent-as-a-judge.</p>

  <p>At the beginning of each sprint, the generator and evaluator first negotiate “what counts as done for this piece,” rather than having the generator finish first and then ask the evaluator to criticize it. Before writing code, both sides communicate and reach consensus. This “negotiation” happens by exchanging structured artifacts through files and the workspace: the generator writes a sprint contract proposal, explaining what this round will do, what the acceptance criteria are, and what is out of scope; the evaluator reads the planner spec and proposal, fills in missing boundary conditions or rejects an overly broad scope; the generator then revises the contract. What they share is the spec, contract, progress, code, test results, and feedback.</p>

  <p>In this negotiation process, vague user stories become testable contracts. It is a bit like product requirement clarification + QA test plan in a human team.</p>

  <p>However, giving evaluation to another LLM does not automatically solve the problem. Claude was not a good QA agent at first either. It would find real problems, then convince itself that they were not serious; or it would only do shallow tests and not touch edge paths. So the evaluator itself also needs to be tuned. It needs a clear rubric, failure cases, judgment criteria, interaction paths it must explore, and bug types it must not let go too easily. Ideally, we should read its logs, find where it disagrees with human judgment, and update and iterate on the evaluator prompt.</p>

  <p>Anthropic’s frontend harness used several scoring dimensions:</p>

  <ul>
    <li>
      <p><strong>Design quality:</strong> Whether the whole thing has a clear character, rather than being a pile of components. Aesthetic quality.</p>
    </li>
    <li>
      <p><strong>Originality:</strong> Whether there are custom design decisions, avoiding templates, default libraries, and an “AI feel.” Originality.</p>
    </li>
    <li>
      <p><strong>Craft:</strong> Typography, spacing, color, contrast, and so on. Usability at the craft level.</p>
    </li>
    <li>
      <p><strong>Functionality:</strong> Understanding and completing the task. The more important functionality side of usability.</p>
    </li>
  </ul>

  <p>So when using a judge, we cannot ask abstractly whether this is “good.” We need to break “good” into multiple checkable dimensions. Similarly, in the application development harness, the evaluator scores dimensions such as product depth, functionality, visual design, and code quality, and every dimension has a hard threshold. As long as one key dimension is below the hard threshold, this sprint fails, and the generator must continue revising based on concrete feedback.</p>

  <p>When evaluating, what we evaluate should not be “the agent says it is done,” but the final environment state and outcome. A flight-booking agent saying “I booked it for you” is meaningless; what matters is whether there is actually a reservation in the database. A coding agent saying “bug fixed” is meaningless; what matters is whether the tests pass (outcome), and whether it damaged the original code (state).</p>

  <blockquote>
    <p>/btw</p>

    <p>Many life lessons can apply here. For example, when evaluating a person, what the other person did matters more than what they said. Because of my unique “therapist trait,” I often end up talking about related topics when discussing relationship problems with the girls around me. Processing and analyzing other people’s dilemmas is much easier than walking out of my own life difficulties. On one side I am being other people’s therapist; on the other side I need to find a therapist myself, but it is hard to find one I trust. After I started trying to write blogs, I actually felt much calmer. Maybe I am my own best therapist. Writing lets me quiet down and talk to myself. Before, I gave all my time to other people and almost did not allocate any time to myself. Also, although I have been anxious about finding a job, and about being replaced by LLMs as a researcher in the near future, I still think I am better at therapy than the most state-of-the-art LLMs. Unfortunately, this trait cannot make me a living and was never on my career-planning path. I have wandered too far.</p>
  </blockquote>

  <p>Some points worth noting: the planner usually mainly solves initial under-scoping. For example, a user’s one-sentence prompt is often too broad, such as “build a 2D retro game maker,” and the planner can make it concrete: what core modules should this product have, which are must-haves, which can be done later, and how each feature should be accepted. After the project moves forward, the evaluator takes on part of the local planner role and does feedback-driven replanning. The evaluator modifies artifacts left by the planner. For example, the planner initially wrote <code class="language-plaintext highlighter-rouge">sprite editor</code>, only requiring draw and save. After real testing, the evaluator may add new acceptance criteria: brush size must work, transparent pixels must be preserved, saved sprites must appear in the entity palette, and state must not be lost after reloading the project. The planner can implement replanning by modifying external files such as <code class="language-plaintext highlighter-rouge">feature_list</code>, <code class="language-plaintext highlighter-rouge">sprint_contract</code>, <code class="language-plaintext highlighter-rouge">known_issues</code>, and <code class="language-plaintext highlighter-rouge">next_actions</code>.</p>

  <p>So a multi-agent harness puts planning, execution, evaluation, and revision into external artifacts, so each round of agent can take over with limited context.</p>

  <h2 id="more-durable-design"><strong>More durable design</strong></h2>

  <p>Every component of a harness implicitly contains assumptions: assumptions about what the model cannot do well by itself. As models become stronger, these assumptions may no longer be valid. For example, if a model has context anxiety, the harness adds context reset. Later, if the model no longer has this problem, reset may turn from a necessary structure into latency and cost. If a model cannot plan, we add a planner. Later, if the model’s planning ability improves, the planner may only be valuable on large tasks. If the generator can already reliably complete a task by itself, the evaluator may become unnecessary overhead; but on tasks that sit just beyond the model’s capability boundary, the evaluator can again bring a large lift. So a harness is not better just because it is more complex. We should start from the simplest workable system, use evals to identify failure modes, then add corresponding structure for these real failure modes, and as models upgrade, periodically remove components that are no longer load-bearing, rather than building an overcomplicated agent framework from the beginning.</p>

  <p>An agent system can be split into several relatively stable abstractions:</p>

  <ul>
    <li>
      <p><strong>Session:</strong> an append-only log of what happened.</p>
    </li>
    <li>
      <p><strong>Harness:</strong> the control layer that calls the model, routes tools, and executes the agent loop.</p>
    </li>
    <li>
      <p><strong>Sandbox:</strong> the environment where the agent can run code and modify files.</p>
    </li>
  </ul>

  <p>After decoupling them, the underlying implementation can keep changing while the external interface stays stable. Because the harness of long-running agents will keep evolving, stable abstractions let agent products avoid being tied to one generation of harness.</p>

  <h2 id="agent-eval"><strong>Agent Eval</strong></h2>

  <p>Agent behavior is nondeterministic. Running the same prompt twice may succeed once and fail once. A task passing once does not mean the system is reliable; a task failing once may also mean the grader was wrong, the environment had a problem, or the task itself was ambiguous. Compared with ordinary LLM evals, for agent evals we should not only look at output text, but at the result that a sequence of actions causes in the environment. So we need sandbox, database, browser, file system, mock API, resettable environment, and so on. Different tasks may care about different metrics. For a coding agent, if we allow the agent to try multiple times, <code class="language-plaintext highlighter-rouge">pass@k</code> (the probability that at least one of k attempts succeeds) is a relatively suitable metric, because as long as one patch is correct, it can enter review. But for customer service, reimbursement, flight booking, and other agents used directly by users, <code class="language-plaintext highlighter-rouge">pass^k</code> (the probability that all k attempts succeed) is more important, because users expect reliability every time, not “one of ten attempts is right.”</p>

  <p>There is also the difference between capability eval and regression eval. Capability evals contain some tasks the current system does not do well. Regression evals evaluate “can it still do what it used to know how to do?” This should be close to 100% pass, and is used to prevent regressions after system upgrades, model switches, or prompt changes.</p>

  <h2 id="agentic-safety-the-importance-of-a-good-rl-environment"><strong>Agentic Safety (the importance of a good RL environment)</strong></h2>

  <p>In the non-agentic era, because the model could only answer text, the blast radius of mistakes was small. But now agents can run shell, modify files, access databases, call SaaS APIs, send Slack messages, and open PRs. The cost of mistakes can be much larger. For safety, we cannot rely only on “the model will judge whether a command is dangerous” to protect the system. The safer approach is to restrict what the agent can access, where it can write, what networks it can reach, which tools require approval, which state can persist, and which secrets are never visible. But this requires a good RL environment. Of course, once we mention RL environment, we have to mention reward hacking: we should not put shortcuts we do not want the agent to use into its environment. For example, in a coding eval, future commits should not be placed in <code class="language-plaintext highlighter-rouge">.git/objects</code>, hidden tests should not be placed inside the container, and secrets that can access production systems, such as API keys, OAuth tokens, cloud provider keys, and SSH keys, should not be directly exposed to the agent. We can instead use controlled tool capabilities, and implement permission checks, parameter constraints, and auditing inside the tool.</p>

</div>

<div class="lang-content lang-zh" lang="zh" style="display: none;">

  <blockquote>
    <p><strong>Imortant Note:</strong> 虽然学术性blog我尽量保持严肃，但在写的过程中还是忍不住插一些毫无关系的东西，为了避免污染context，我会用<strong>“<em>/btw”</em></strong> command将其和technical的部分分开，读者们可以将这些“by the way”的部分跳过。</p>
  </blockquote>

  <p>过去几年，大模型进步的主线大多围绕“模型本身”：参数、数据、pretraining、post-training、reasoning。早期我们谈 agent，最常见的定义也很简单：LLM + tool use， 再后面，逐渐变成 context engineering：管理模型每一步 inference 时看到的上下文，让多轮工具使用不被历史、噪声、工具定义和中间结果淹没。在后面， 演变为long horizon的task，agent 能力就变成了模型、harness、context、tools、eval、sandbox、state management 一起构成的系统能力: 在有限上下文、外部工具和可变环境中，持续推进一个目标，而且越做越接近完成。</p>

  <p>在这篇blog中，我们主要focus 在Context engineering 和 long-running harness的部分。</p>

  <p>Context engineering 的前身是 prompt engineering。当 agent 从单轮回答变成多轮行动系统时，模型在 inference 时看到的 input，也从相对独立的外部输入，也就是 prompt，变成了和模型、工具、环境持续交互有关的 context。这个 context 可能包括工具定义、文件内容、网页观察、历史消息、测试输出、MCP server 描述、外部文档、进度记录等。  Context engineering 要决定哪些信息应该提前放进 prompt，哪些应该按需检索，哪些应该写到外部 memory，哪些应该交给代码或工具处理，而不是塞进模型上下文。Anthropic 在 2025 年 9 月的 <a href="https://www.anthropic.com/engineering/effective-context-engineering-for-ai-agents"><em>Effective context engineering for AI agents</em></a>里系统化地阐释了这个概念。一个具体的 context engineering example是：当 MCP tools 太多、数据太大时，不应该让所有工具定义和中间结果都流过 context，而应该让 agent 写代码按需调用工具、过滤数据，只把高信号结果带回模型。  context engineering里面也包含 compaction、structured note-taking，甚至 multi-agent 之类的，但它们主要服务于“上下文怎么管理”。而后面讲到的 long-running agent harness 的重点更进一步，不只是管理 context，而是会把计划、实现、评价、修订和最终验收等拆开成各个流程。</p>

  <p>到 2025 年底，随着 coding agent 已经能在软件工程任务上连续推进更久，问题的重心很快转向了 long-running agent harness：从最开始关注的模型的代码能力，变成了跨越多个 context window / session 时依然能够继续执行任务的能力。11 月，Anthropic 发布了 <a href="https://www.anthropic.com/engineering/effective-harnesses-for-long-running-agents"><em>Effective harnesses for long-running agents</em></a>，这可以看作第一版 long-running harness：系统开始从“管理一个 agent 的上下文”shift到“管理多个 session ”。这版 harness 引入了 initializer agent 和 coding agent这样的最小角色分工。Initializer 的作用是建立一个可接力的外部项目状态：它会把任务拆成更小的 feature list，写 progress file，创建 init script，初始化 git repo，并把每个 feature 标成待完成状态。后续 coding agent 每个 session 只推进一个有限增量，比如实现某个 feature 或修复某个明确问题。Harness 会要求它在结束前测试、更新记录、commit，并尽量把 repo 留在 clean state。这样即使下一个 session 是一个新的 context，也能通过 progress file、feature list、git log 和测试结果重新接上任务。</p>

  <p>2026 年 1 月，Anthropic 发了 <a href="https://www.anthropic.com/engineering/demystifying-evals-for-ai-agents"><em>Demystifying evals for AI agents</em></a>。这篇文章把 agent eval 系统化：因为agent会在环境中多轮行动、调用工具、修改状态，所以 eval 不能只看最后一句回答，还要看 transcript / trajectory，以及最终环境状态是否真的正确。大概说了两个point：一是 task-level 的：怎么确定agent真的把task给做出来并且做好了，而不是只做出一个表面看起来可以、但实际有 bug 或不完整的结果；另一层是 harness-level 的，说明我们也需要评估 harness 的每个 component 是否真的 load-bearing，而不是只是加了一些没用的东西。</p>

  <p>到 2026 年 3 月的 <a href="https://www.anthropic.com/engineering/harness-design-long-running-apps"><em>Harness design for long-running application development</em></a>，这个思路变成了第二版 harness：initializer + coding agent 被扩展成 planner + generator + evaluator。Evaluator 会用 Playwright MCP 像用户一样操作应用，测试 UI、API 和数据库状态，并根据一些标准拒绝不合格结果。这个evaluator是否应该存在取决于任务是否超出当前模型 solo 完成的可靠边界， 比如，Opus 4.5 上它明显有用；到 Opus 4.6，模型本身变得更强，一些 scaffold 就可以被移除或弱化。这些调整和转变会很自然的让我们思考更长期的系统设计问题 （可以看他们四月份的post <a href="https://www.anthropic.com/engineering/managed-agents"><em>Scaling Managed Agents</em></a> ）：harness 不是固定结构，而是和模型能力共同演化的。早期 Sonnet 4.5 / Opus 4.5 会 context anxiety，会 under-scope， 就需要更多 scaffold：context reset、sprint decomposition、evaluator feedback loop。但到了 Opus 4.6，模型本身更擅长长时间 agentic tasks、代码审查、debugging 和长上下文检索。一些原本必要的结构开始变得没那么必要，比如，对于模型已经能稳定 solo 完成的任务，evaluator 可能不再值得成本。当然，对于刚好处在模型能力边界之外的任务，evaluator 仍然能带来 real lift。harness 里的很多设计，本质上都包含了一些“当前模型做不好什么”的假设。模型升级以后，这些假设可能就不再成立，所以不能把某一代 harness 当成一个一直可以用的构架。而应该把整个系统拆成相对稳定的抽象，用session 来记录发生了什么，用harness 负责 agent loop 以及工具的使用，sandbox 提供可控执行环境等。这样底层 harness 可以不断替换，但 agent 产品不会和某一代的scaffold 绑死。</p>

  <h2 id="context-engineering-1"><strong>Context engineering</strong></h2>

  <p>过去大家关注 prompt engineering，也就是怎么写系统提示词；但 agent 越来越多轮、越来越长之后，问题focus变成了，每一步 inference 时，模型看到了什么。比如，一个 agent 的 context 里可能有system prompt， developer instructions， tool definitions， MCP server descriptions， 用户消息， 历史对话， 文件内容， command output， browser observations， screenshots， errors， progress notes， retrieved documents， evaluator feedback， 这些东西不能全部无脑塞进去。即使上下文窗口变大， 也需要选择性的放。因为长上下文里的噪声会让模型分心，也会增加成本和延迟。所以，一个好的 context是在当前这一步，让模型足够完成下一步的最小高信号上下文。一般我们会使用just-in-time context，不把所有文档、工具、历史都塞给模型，而是保留引用， 比如路径， URL，commit hash，log 文件，数据库表名等，模型需要的时候再通过工具加载。这样 agent 的工作记忆里保留的是索引和当前相关片段，而不是所有的context。</p>

  <p>长任务里常见的 context 技术包括：</p>

  <ul>
    <li>
      <p><strong>compaction</strong>：（在 context 快满时）把当前 conversation trace 压缩成一段摘要，然后用这个摘要开启下一段 context。它通常还是同一个任务、同一条 agent loop 的延续。它的目标是尽量保留 conversational continuity。也就是说，模型应该感觉“我刚才做的事情还在”，只是历史被压缩了。</p>
    </li>
    <li>
      <p><strong>structured note-taking</strong>：让 agent 主动把任务状态写到外部持久化 artifact 里，例如 progress.md、feature_list.json、NOTES.md、git commit。（它也不一定只给同一个任务用。一个项目级 NOTES.md 可以被后续 session 读，也可以被 planner、generator、evaluator 读；或者在相邻任务里复用。）</p>
    </li>
    <li>
      <p><strong>context reset</strong>：用外部 artifact （比如， note-taking 产生的文件， git log、测试结果、任务列表等）作为启动材料开一个干净的新 context/session。它不会保留完整 conversation history， 可以清掉噪声和坏假设，让新 agent 重新定向。</p>
    </li>
    <li>
      <p><strong>multi-agent architecture</strong>：做角色分工和上下文隔离，不同 agent 拿不同上下文、做不同子任务，最后只把高密度结果交回主流程。</p>
    </li>
  </ul>

  <h2 id="section"><strong>工具调用</strong></h2>

  <p>工具调用上也有一些需要注意的点， 比如工具数量不能无限膨胀，否则模型会在选择上浪费注意力。工具之间不要有过多功能重叠，否则模型不知道该用哪个。工具描述要清楚说明什么时候用、什么时候不用（就是要讲清楚边界）。返回值要 token-efficient，不要把无关数据全倒进 context。返回的错误信息要让模型知道下一步怎么修。命名要清晰，让 agent 能从名字推断边界。而且工具最好不要作为直接 tool call 暴露给模型，而应该映射成代码 API / 文件树，让 agent 用代码调用。这样 agent 可以只读取当前需要的 tool definition， 然后在代码执行环境里过滤大的数据， 只把摘要或少量结果返回给模型。用循环、条件、异常处理完成复杂控制流，或者把中间状态写到文件里，而不是塞进 context。工具返回的东西是确定性的，我们应该把确定性计算留给代码，如何调用工具，调用哪些，以什么顺训调用，调用多少次这样的把判断和规划则应该留给模型。</p>

  <h2 id="long-running-agent-"><strong>long running agent 的问题</strong></h2>

  <p><strong>（1）上下文窗口</strong></p>

  <p>长任务一定会超过单个 context window。即使模型支持很长上下文，context 始终是有限资源：每多塞一点信息，都会占用模型的注意力预算。这带来三种常见现象：</p>

  <ul>
    <li>
      <p><strong>amnesia</strong>：新 session 开始时不知道前一个 session 做了什么。</p>
    </li>
    <li>
      <p><strong>context rot</strong>：上下文越长，模型越容易失去重点，早期信息会被噪声淹没。</p>
    </li>
    <li>
      <p><strong>context anxiety</strong>：模型感觉自己快到上下文末尾时，会急着收尾，把半成品说成完成品。</p>
    </li>
  </ul>

  <p><strong>（2）规划和hand-off</strong></p>

  <p>很多复杂任务会包含几十个互相依赖的 feature、bug、设计决策和验证步骤。模型如果直接从一句high level prompt 开始做，很容易一上来什么都想做，然后做到一半上下文耗尽，留下一个看似做了很多，但实际完全不work的东西。并且，即使一些东西对下一个agent有用的，下一轮agent也不知道哪些是有用的：一些看似bug的东西，是故意做成这样的，还是上一个 session 没来得及收拾？</p>

  <blockquote>
    <p>/btw</p>

    <p>相信各位在读博或者工作中，都有接手合作者留下的烂摊子的经历，虽然到了读博的后期，大约是25年12月开始，agent发展太过飞速，让我有了很多的anxiety和insecurity，深感自己没有办法在学术界继续待下去了， 也完全没有继续发paper的动力，我也成了自己曾经所讨厌的，给合作者们留下一堆烂摊子的人</p>
  </blockquote>

  <p><strong>（3）自我评价</strong></p>

  <p>模型不一定会严厉地判断自己生成的东西。它可能看到一个按钮能显示出来，就觉得这个功能完成了；会看到一个页面大概长得像，就觉得设计的很好了，或者测试跑了一部分，就觉得整个系统可用了。Anthropic 在 long-running application harness 那篇文章里提到，让同一个 agent 既当生成者又当评审，经常会得到过于宽松的判断。尤其是前端设计、产品完整性、边缘交互这类没有单元测试直接定义的东西，模型很容易说服自己。</p>

  <blockquote>
    <p>/btw</p>

    <p>毕竟世界是个巨大的草台班子，模型还是从咱们这里学到了很多东西的。以及很多时候，人只需要说服自己就够了。</p>
  </blockquote>

  <h2 id="harness-1"><strong>Harness</strong></h2>

  <p>agent harness，也叫 scaffold，是让模型能够作为 agent 行动的系统。它负责处理输入、组织工具调用、管理状态、执行循环、把结果返回给模型。包括文件系统、任务板、测试脚本、浏览器、shell、git、日志、sandbox、权限系统、checkpoint、handoff note等。</p>

  <p>第一代 long-running harness的核心设计很朴素， 主要用了两类 agent：</p>

  <ul>
    <li>
      <p><strong>Initializer agent</strong>：最开始的时候运行一下，搭好工作的框架和环境。</p>
    </li>
    <li>
      <p><strong>Coding agent</strong>：session by session的做增量进展，并在结束前留下结构化交接物。</p>
    </li>
  </ul>

  <p>Initializer agent 会做几件事。</p>

  <p><strong>（1）创建任务清单。</strong></p>

  <p>比如用户只说“做一个 claude.ai clone”，initializer 不会让后续 agent 直接开始做，而是把这个任务拆成大量可验证 feature，例如新建聊天、输入消息、回车发送、收到回复、切换主题、加载历史会话等。每个 feature 初始状态都标成 failing。</p>

  <p><strong>（2）创建进度文件。</strong></p>

  <p>比如 claude-progress.txt 或类似文件，记录每一轮做了什么、哪些还没做、哪些地方需要注意。</p>

  <p><strong>（3） 创建启动脚本。</strong></p>

  <p>比如 init.sh，告诉后续 agent 如何安装依赖、启动服务、跑基本检查。</p>

  <p><strong>（4）初始化 git repo。</strong></p>

  <p>每轮结束时 commit，这样，后续 agent 通过 git log 理解最近的变化，系统能回滚、diff、审计。</p>

  <p>后续 coding agent 大概分为三部分做：</p>

  <ol>
    <li>
      <p>搞清楚目前自己接受的工程状态（orient）：确认当前工作目录， 读 progress file和 feature list， 查看最近 git log； 跑一个 end-to-end 的 test来确认基础功能没坏；</p>
    </li>
    <li>
      <p>选择并完成一个feature （select &amp; implement&amp; validate)：选择最高优先级的未完成 feature来实现一个相对独立的增量， 自己测试并evaluate这个feature，</p>
    </li>
    <li>
      <p>hand off一个clean state给下一轮， 使得当前代码可以被下一个 agent 理解：比如，更新 feature 状态和 progress file并 commit。如果新 feature 没做完，也要留下清楚的边界， 而不是假装自己完成了。</p>
    </li>
  </ol>

  <p>long-running agent 本质上是在用多个短 session 拼一个长任务。如果每个 session 都留下小烂摊子，错误会复利增长。所以 harness 不能只奖励“可验证增量”，还要奖励“留下的系统的状态”。一个 session 结束时，如果 agent 多写了三个功能，但把启动流程弄坏了，下一轮可能要花大量 token 先恢复环境。长期看，这种进展其实是负收益。</p>

  <h2 id="planner--generator--evaluator"><strong>planner / generator / evaluator的三类角色</strong></h2>

  <p>第一代 harness 解决了上下文接力问题，但还有一个大问题：agent 不擅长判断自己。于是 Anthropic 在第二代里进一步引入了多 agent 结构。最终形态大致是三类角色：</p>

  <ul>
    <li>
      <p><strong>Planner</strong>：把user的high level prompt 展开成规格、功能列表、设计方向和实现计划。</p>
    </li>
    <li>
      <p><strong>Generator</strong>：按计划实现功能，写代码、改 UI、接后端、跑测试。</p>
    </li>
    <li>
      <p><strong>Evaluator</strong>：像 QA 一样操作应用、检查结果、指出问题、决定是否通过。</p>
    </li>
  </ul>

  <p>不同角色对应不同失败模式。</p>

  <p>Planner 解决的是 under-scoping。没有 planner 时，generator 往往会把任务理解得太窄。例如“做一个 2D retro game maker”，单 agent 可能做出一个能放点 tile 的页面就觉得完成了。Planner 则会把它展开成 level editor、sprite editor、entity behavior、playable test mode、动画、导出、音效、AI 辅助生成等更完整的产品规格。</p>

  <p>Generator 解决的是执行。它仍然是主要劳动力，但它不再凭空决定整个产品边界，而是在明确 spec 和当前 feature contract 里工作。Generator 也不一定是单个 agent。它更像一个角色：多个 generator sessions 或 coding agents sequentially 接力执行。每一轮 generator 读 planner spec、当前代码、progress file、上一轮 evaluator feedback，然后完成一个有限增量，写回状态并退出。下一轮 generator 再接着读这些 artifact 继续。所以 long-running harness 的连续性连续性是放在外部项目状态， 比如 progress file、feature list、git commit 和 test results里。</p>

  <p>Evaluator 解决自我评价。它是只是读代码，然后打分或者给出feedback，而是通过 Playwright 或浏览器自动化像用户一样点击应用，检查 UI 功能、API、数据库状态和边缘情况。（所以从之前的llm as a judge变成了agent as a judge).</p>

  <p>在每个 sprint 开始前，generator 和 evaluator 会先协商“这一块到底怎么算完成”, 而不是 generator 先写完再让 evaluator 来critic，而是在写代码之前，双方线communicate，达成consensus。这个“协商”是通过文件和 workspace 交换结构化 artifact做的：generator 写一个 sprint contract proposal，说明本轮要做什么、验收标准是什么、哪些不在 scope；evaluator 读取 planner spec 和 proposal，补充遗漏的边界条件或拒绝过宽的 scope；generator 再修订 contract。他们共享的是 spec、contract、progress、代码、测试结果和 feedback。</p>

  <p>在这个协商的过程中，把模糊的用户故事变成可测试 contract。有点像人类团队里的产品需求澄清 + QA test plan。</p>

  <p>不过，把评价交给另一个 LLM 并不自动解决问题。Claude 一开始也不是好的 QA agent。它会发现真实问题，然后又说服自己这些问题不严重；或者只做浅层测试，不去碰边缘路径。所以 evaluator 本身也要被调， 需要给它明确的 rubric、失败案例、判断标准、必须探索的交互路径、不能轻易放过的 bug 类型。最好是读一读它的 logs，找出它和人类判断不一致的地方，更新和迭代 evaluator prompt。</p>

  <p>Anthropic 的 frontend harness 使用了几类评分维度：</p>

  <ul>
    <li>
      <p>design quality：整体是否有清晰气质，而不是组件堆叠。（美学上）</p>
    </li>
    <li>
      <p>originality：是否有定制设计决策，套模版和默认库， 避免“ai 感” （原创性上）</p>
    </li>
    <li>
      <p>craft：排版、间距、色彩、对比度等。（可用性）</p>
    </li>
    <li>
      <p>functionality：理解并完成任务。（更加重要一点的functionality上的可用性）</p>
    </li>
  </ul>

  <p>所以我们在使用judge时，不能抽象的问judge这个“好不好”，而是需要把“好”拆成多个可检查维度。同样，在应用开发 harness 里，evaluator 会按 product depth、functionality、visual design、code quality 等维度打分，而且每个维度有hard threshold。只要一个关键维度低于hard threshold，这轮 sprint 就失败，generator 必须根据具体反馈继续改。</p>

  <p>在evaluate的时候，evaluate的不是”agent说自己完成了“，而应该evaluate环境最终状态以及outcome。一个航班预订 agent 说“我已经帮你订好了”没有意义，而要看数据库里是否真的有 reservation 。一个 coding agent 说“bug fixed”没有意义， 重要的是测试是否通过（outcome), 以及是否把原本的代码弄坏了(state).</p>

  <blockquote>
    <p>/btw</p>

    <p>好多生活的哲理都可以apply到这里，比如，评估一个人的时候，对方做了什么比说了什么更重要。因为自己身上独特的“therapist trait”， 这在我和周围女孩们谈论她们的情感问题时倒是常常聊到相关的话题。处理和分析别人的dilemma比走出自己的人生困境容易多了，一方便在给别人做心理医生，一方面需要找心理医生，但很难找到能让我信服的therapist。开始尝试写blog后，我倒觉得自己平静了很多，可能我才是自己最好的therapist吧， 写作让我能够静下来和自己对话，以前则是把所有的时间都给了别人， 几乎没有allocate给自己的时间。另外，虽然我一直焦虑着找工作的事，以及在不久的将来，自己作为researcher会被LLM取代这件事，我觉得自己在therapy方面还是比最state of the art LLM做的好的， 可惜这个trait没法让我make a living，也从来不在我的职业规划的路径里。 扯远了～</p>
  </blockquote>

  <p>一些需要注意的点是： planner 通常主要解决初始 under-scoping。比如，用户一句话往往太宽泛，比如“做一个 2D retro game maker”， 而planner可以将其具体化：这个产品应该有哪些核心模块、哪些是 must-have、哪些可以以后做、每个 feature 怎么验收。项目推进之后，evaluator 会承担一部分局部 planner 的角色， 来做 feedback-driven replanning。evaluator 会修改 planner 留下来的 artifact。比如 planner 最初写了 sprite editor，只要求能 draw 和 save。Evaluator 在真实测试后可能补上新的验收条件：brush size 要工作，透明像素要保留，保存后的 sprite 要出现在 entity palette，reload project 后状态不能丢。planner可以通过改 feature_list、sprint_contract、known_issues、next_actions 这些外部文件来实现replanning。</p>

  <p>所以多 agent harness 会把计划、执行、评价、修订都落到外部 artifact 上，让每一轮 agent 可以用有限上下文接手。</p>

  <h2 id="section-1"><strong>更持久性的设计</strong></h2>

  <p>harness 的每个组件都隐含了一些假设，假设模型自己做不好某件事。随着模型变强，这些假设可能会不再valid。比如某个模型有 context anxiety，于是 harness 加了 context reset。后来模型不再有这个问题，reset 可能就从必要结构变成了延迟和成本。某个模型不会规划，于是加入 planner。后来模型规划能力增强，planner 可能只在大任务上有价值。某个任务靠 generator 自己已经能稳定完成，evaluator 就可能是多余开销；但在刚好超过模型能力边界的任务上，evaluator 又会带来巨大提升。所以 harness 不是越复杂越好。而应该从最简单workable的系统开始，用 eval 找出失败模式， 然后为这些真实失败模式增加相应的结构，随着模型升级，定期移除不再 load-bearing 的组件， 而不是一开始就搭一个过度复杂的 agent framework。</p>

  <p>agent 系统可以拆成几个相对稳定的抽象：</p>

  <ul>
    <li>
      <p><strong>session</strong>：发生过什么的 append-only log。</p>
    </li>
    <li>
      <p><strong>harness</strong>：调用模型、路由工具、执行 agent loop 的控制层。</p>
    </li>
    <li>
      <p><strong>sandbox</strong>：agent 能运行代码和改文件的环境。</p>
    </li>
  </ul>

  <p>把它们解耦之后，底层实现可以不断变化，同时保持外部接口的稳定。因为 long-running agent 的 harness 会持续演化。稳定抽象能让 agent 产品不必被某一代 harness 绑死。</p>

  <h2 id="agent-eval-1"><strong>Agent Eval</strong></h2>

  <p>agent 的行为是非确定性的。同一个 prompt 跑两次，可能一次成功一次失败。一个任务 pass，不代表系统可靠；一个任务 fail，也可能是 grader 写错了、环境有问题，或者任务本身有歧义。和普通 LLM eval 相比，对于agent eval，我们不应该不只是看输出文本，而是要看一串行动对环境造成的结果。所以需要 sandbox、数据库、浏览器、文件系统、mock API、可重置环境等。不同的task关注的metric可能也不一样，对 coding agent 来说，如果我们允许 agent 多试几次，pass@k （k 次尝试里至少成功一次的概率）是一个比较合适的metric，因为只要有一次 patch 对了就可以进入 review。但对客服、报销、订票这种用户直接使用的 agent，pass^k （k 次尝试全部成功的概率）会更关键，因为用户期待每次都可靠，而不是十次里总有一次对。</p>

  <p>另外，还有Capability eval 和 regression eval的区别。做Capability eval 时包含一些当前做得不好的任务，Regression eval 则是在evaluate“它以前会的东西现在还会不会？”这个应该接近 100% pass，用来防止系统升级、模型切换、prompt 修改之后倒退。</p>

  <h2 id="agentic-safetyrl-environment"><strong>Agentic Safety（一个好的RL environment的重要性）</strong></h2>

  <p>在non-agentic时代，因为模型只能回答文本，其犯错的 blast radius 很小。但现在agent能跑 shell、改文件、访问数据库、调用 SaaS API、发 Slack、开 PR，其犯错成本会大很多。对于safety，我们不能只靠“模型会判断危险命令”来保护系统。更safe的做法是限制 agent 能访问什么、能写哪里、能联网到哪、哪些工具需要审批、哪些状态可持久化、哪些 secret 永远不可见。但这需要很好的RL environment，  当然，说到RL environment，咱就不得不提到reward hacking: 我们不应该把我们不希望 agent 使用的捷径放进它的环境里。比如，如果 coding eval 的 future commit 不应该放在 .git/objects 里， hidden tests 不应该放在容器里， 对于能访问生产系统的 secret，比如 API key、OAuth token、云厂商密钥、SSH key，都不应该直接暴露给 agent（可以用受控 tool capability， 然后在tool内部做好权限的检查，参数限制以及审计）。</p>

</div>

<script>
(function() {
  var buttons = document.querySelectorAll('.lang-switcher .lang-btn');
  var contents = document.querySelectorAll('.lang-content');
  buttons.forEach(function(btn) {
    btn.addEventListener('click', function() {
      var lang = btn.getAttribute('data-lang');
      buttons.forEach(function(b) { b.classList.remove('active'); });
      btn.classList.add('active');
      contents.forEach(function(c) {
        if (c.classList.contains('lang-' + lang)) {
          c.style.display = '';
        } else {
          c.style.display = 'none';
        }
      });
    });
  });
})();
</script>]]></content><author><name>Jinyan Su</name><email>jinyansu6@gmail.com</email></author><category term="technical" /><category term="agents" /><category term="context-engineering" /><category term="harness" /><category term="evals" /><category term="anthropic" /><summary type="html"><![CDATA[From LLM + tool use to context engineering, and then to long-running agent harnesses: agent capability is becoming a system property composed of the model, harness, context, tools, evals, sandbox, and state management.]]></summary></entry><entry><title type="html">The Age of AI: When Knowledge No Longer Makes Us Feel Safe / AI时代：当知识不再给我们带来安全感</title><link href="https://jinyansu1.github.io/blog/2026/06/ai-era-knowledge-security/" rel="alternate" type="text/html" title="The Age of AI: When Knowledge No Longer Makes Us Feel Safe / AI时代：当知识不再给我们带来安全感" /><published>2026-06-30T00:00:00+00:00</published><updated>2026-06-30T00:00:00+00:00</updated><id>https://jinyansu1.github.io/blog/2026/06/ai-era-knowledge-security</id><content type="html" xml:base="https://jinyansu1.github.io/blog/2026/06/ai-era-knowledge-security/"><![CDATA[<div class="lang-switcher">
  <button type="button" class="lang-btn active" data-lang="en">English</button>
  <button type="button" class="lang-btn" data-lang="zh">中文</button>
</div>

<div class="lang-content lang-en" lang="en">

  <p><em>(Translated from the Chinese version by ChatGPT.)</em></p>

  <p>The dust of the times, when it settles on any single person, becomes a mountain. Over the course of a life, one will most likely live through many great, era-defining changes. My own social circle is small, and I hardly know anyone from other generations, so I can’t say whether, somewhere in their lives, there was a historical stretch that could rival the hurricane AI has stirred up over these past two or three years. Every generation, meeting the great upheaval of its own time, probably laments the misfortune of being the generation it is. And yet, seen along the timeline of modern human history, even if a single life is only a tiny segment of that long river, it seems no generation ever passed through a plain, uneventful life without living through some great historical upheaval.</p>

  <p>Times of great upheaval: the shifting of thought, the reshaping of values, always come with pain. We were raised inside a system that reveres knowledge (the law-abiding, by-the-book traditional Chinese education system), taught from the very beginning to study hard, to become knowledge workers, to have “a respectable job” and a stable life. And so, along a path already laid out and validated by many, our life choices were shaped for us: go to college, earn a master’s, earn a PhD, then become a professor or a research scientist — the stable, relatively well-paid job. It was the predictability of this path that gave us our sense of safety. And then one day, the path collapsed. Because it was so stable:  we had been walking it from the moment we were born, we had long taken its existence for granted, and had never once imagined what our Plan B would be if it ever gave way. To survive, to feel safe, people keep a Plan B for all sorts of things; but in this one thing, for most of us, our past trajectory was never enough to instill any sense of crisis, until, at a certain point, it did.</p>

  <p>Value has always been the product of a particular historical moment, not a constant law of how the world runs. But life is short; our experience lets us witness only a single stretch of history, and then we take that stretch to be the world’s constant law. This makes sense, too: across a short enough span between two points, even a curve can be approximated as a straight line — how much more so across the whole long river of time.</p>

  <p>In the age of agriculture, safety came from land; in the industrial age, from physical strength; in the modern world before AI, from knowledge. For many of us, our sense of self-worth is built on “difficulty.” Things are prized for their scarcity: the harder something is, the fewer the people who can do it, and the more it grants us the safety of being “not easily replaced.” AI has made knowledge suddenly cheap, and “knowledge changes your destiny”, once engraved in our minds, is no longer a truth.</p>

  <p>Over these past few months, I’ve spent a great deal of time studying and cultivating myself, stealing a few moments of calm from an anxious age. I’ve kept up with much of the latest technical progress in my field. I’ve convinced myself that the joy learning brings me comes from my appreciation of beauty: the beauty of algorithms, of mathematics, of scheduling and optimization, of logic. And the other things, the ones not technical or logical enough, strike me as not beautiful enough. Until now, the skills that earned my living, the things I spent my time on, and the things that made me happy were all aligned; I didn’t have to think, to weigh trade-offs, to analyze. Now a rift has opened. What others value, the thing that keeps me in a decent living, and what actually makes me happy are no longer aligned, and I have to decide where my time should go, how to balance spiritual needs against material ones, or else change my own perceptions and the way I see certain things, so that all of it can be made consistent again.</p>

  <p>Uprooting something deeply rooted always hurts. I keep tracing back to find where my reverence for technical skill comes from. If I can find its source, and alter it, and through that alter the way I understand things, then perhaps I can complete this remaking of my mind more quickly and more easily.</p>

</div>

<div class="lang-content lang-zh" lang="zh" style="display: none;">

  <p>时代的尘埃，落在每个人身上都是一座大山。一个人的生命中，大抵还是会经历很多次大的时代性的变化，在我有限的社交中，我几乎不认识其他年龄段的人，所以不知道在他们的生命中，是否有哪个历史性的时间段，可以匹敌过去这两三年来AI所带来的飓风。每个时代的人，在遇到他们那个时代的巨大变革时，或许都会抱怨自己作为这代人的不幸，可是站在人类近代历史的时间线去看，即使人的一生只是这个时间长河中很小的一段，好像没有什么时代的人，没有经历重大历史性变革便平平淡淡地过完了一生。</p>

  <p>巨大变革的时代，思想的改变，价值观念的重塑，总是带着阵痛。我们在一个崇尚知识的体系中培养长大（遵纪守法，按部就班的传统中国式教育系统），一开始就被教育着要好好学习，成为知识工作者，”有个体面的工作”，安稳的生活。所以，在一条被规划好了，并经多人验证过的路径上走，这塑造了很多人的人生选择：读大学，读硕士，读博，然后成为一个教授或者科学家，稳定而相对高薪的工作。这种predictable的路径给我们带来了安全感。而有一天，这条路突然塌掉了，因为这条路太过稳定了，一出生就开始走，我们早已习惯这条路的存在，也从未想过如果有一天，路塌了，我们的plan B是什么。人为了生存，为了让自己有安全感，在很多东西上都会有plan B，但在这件事上，大部分人，过去的trajectory不足以让我有危机意识，直到某一个时间节点。</p>

  <p>价值一直以来都是某个历史阶段特定的产物，而非世界运行的恒定规律，而人生太短，我们的阅历只允许我们见证某一段历史，并将其当成世界运行的恒定规律。这也合理，在很短的两点之间，曲线也可以近似为直线，更何况是时间长河呢。</p>

  <p>在农业时代，安全感来自土地；在工业时代，安全感来自体力；在AI之前的现代社会，安全感来自知识。很多人的自我价值，建立在”难度”之上，物以稀为贵，越是难的东西，越少人可以做，越可以给我们”不容易被其他人取代”的安全感。AI让知识突然变得廉价，之前镌刻在脑子里的“知识改变命运”不再是真理了。</p>

  <p>过去的几个月里，我花了很多时间学习和修养，在这个令人焦虑的时代偷来一些能让我感到平静的时光。我看了很多本领域最新的technical的进展。我convince我自己，学习给我带来的快乐是来源于我对美的欣赏，算法的美，数学的美，调度和优化的美，逻辑的美。而其他一些不够technical/logical的东西，则让我觉得不够美。在此之前，能让我维持生活的技能，我所花时间的东西，以及让我觉得快乐的东西，都是align的，我不需要去思考，去取舍，去分析。现在，分歧出现了，大家所value的（能让我维持体面生活的），我能够感到快乐的东西不再align了，我需要去决定我的时间应该花在哪里，以及如何平衡精神和物质需求，或者改变自己的认知和对一些事物的看法，从而让这些东西重新consistent起来。</p>

  <p>把一些根深蒂固的东西连根拔起，总是会痛的。我一直在追根溯源我对技术的崇尚来自于哪里，如果我能找到来源，并通过修改它来改变我对事物的认知，或许就可以更快更轻松的完成思维的重塑。</p>

</div>

<script>
(function() {
  var buttons = document.querySelectorAll('.lang-switcher .lang-btn');
  var contents = document.querySelectorAll('.lang-content');
  buttons.forEach(function(btn) {
    btn.addEventListener('click', function() {
      var lang = btn.getAttribute('data-lang');
      buttons.forEach(function(b) { b.classList.remove('active'); });
      btn.classList.add('active');
      contents.forEach(function(c) {
        if (c.classList.contains('lang-' + lang)) {
          c.style.display = '';
        } else {
          c.style.display = 'none';
        }
      });
    });
  });
})();
</script>]]></content><author><name>Jinyan Su</name><email>jinyansu6@gmail.com</email></author><category term="personal" /><category term="reflection" /><category term="life" /><category term="ai" /><category term="knowledge" /><category term="work" /><summary type="html"><![CDATA[In the age of agriculture, safety came from land; in the industrial age, from physical strength; before AI, from knowledge. Now knowledge suddenly feels cheap, and the old promise that knowledge changes destiny no longer feels like a stable truth.]]></summary></entry></feed>