The AI Data Business Seems to Have No Moat. So Why Is It Booming? / 看起来没有壁垒的数据生意,为何如此繁荣?
This year I was job hunting, mostly for post-training roles.
As it turned out, almost every startup that reached out to me was a data company.
Even now, I still hear from recruiters for RL environment companies and from founders of data startups, plus DMs from people who want to move into this field and would like to set up a meeting with me.
I used to feel hurt when my own cold outreach went unanswered. Now that my time and energy are increasingly limited, I can no longer keep up with requests from strangers.
There’s more and more noise online, and time and attention keep getting more expensive, yet sending someone a DM costs almost nothing. With people I don’t know, saying no is often the only option I have. (Even with people I’ve met once, it’s hard to tell what kind of person they are, or whether the time I’d spend would mean anything.)
Since so many people are interested in this space, and noticeably more over the past few months, I figured I’d just put it all in one post.
In academia, post-training is small-scale tinkering. You can still play with algorithms for your own amusement. Whether my tweaked algorithm would generalize to broader settings, or how large a model it could scale to, I honestly didn’t care. As long as I learned something and had fun along the way, that was enough.
In industry, though, the LLM training recipe, especially the post-training part, has largely matured, and algorithmic innovation is getting rarer. Whether it’s the handful of open-source RL training frameworks or the in-house frameworks companies use to train their own models, they’re all mature and stable. Almost all model improvement now comes from data.
People in pretraining clean data and work on architecture, scaling, and data mixtures. People in post-training mostly deal with all kinds of RL environments.
There’s also mid-training in between, which trains on high-quality data to strengthen the model’s abilities in specialized domains.
Most people doing post-training in industry are, in practice, working on data. If we want the model to do all kinds of tasks, we have to train it on relevant data, and the more kinds of tasks we want, the more diverse the data has to be.
As for what kinds of data the so-called frontier labs, in China and abroad, are each buying (complete RL environments? trajectories generated by models? full data with chain-of-thought that someone managed to hack out?), and what each kind is used for, I honestly don’t know. My guess is that RL environments go into RL training, and high-quality model trajectories are used for an off-policy cold start (SFT), to set up on-policy distillation or RL afterward.
Data vendors also sell very different kinds of data. Many tiny, under-the-radar startups sell almost entirely synthetic data, with a human giving it a quick look. The names people in the field actually know, like Scale AI and Mercor, still hire real experts to label data.
Making synthetic data costs almost nothing. (To be fair, it depends on the task. If a task needs GPUs, the cost goes up. For browser use, computer use and the like, you only pay for tokens, and most small data shops just run everything on personal accounts, so the cost is close to negligible.) Low cost and no technical barrier mean everyone wants to give it a try.
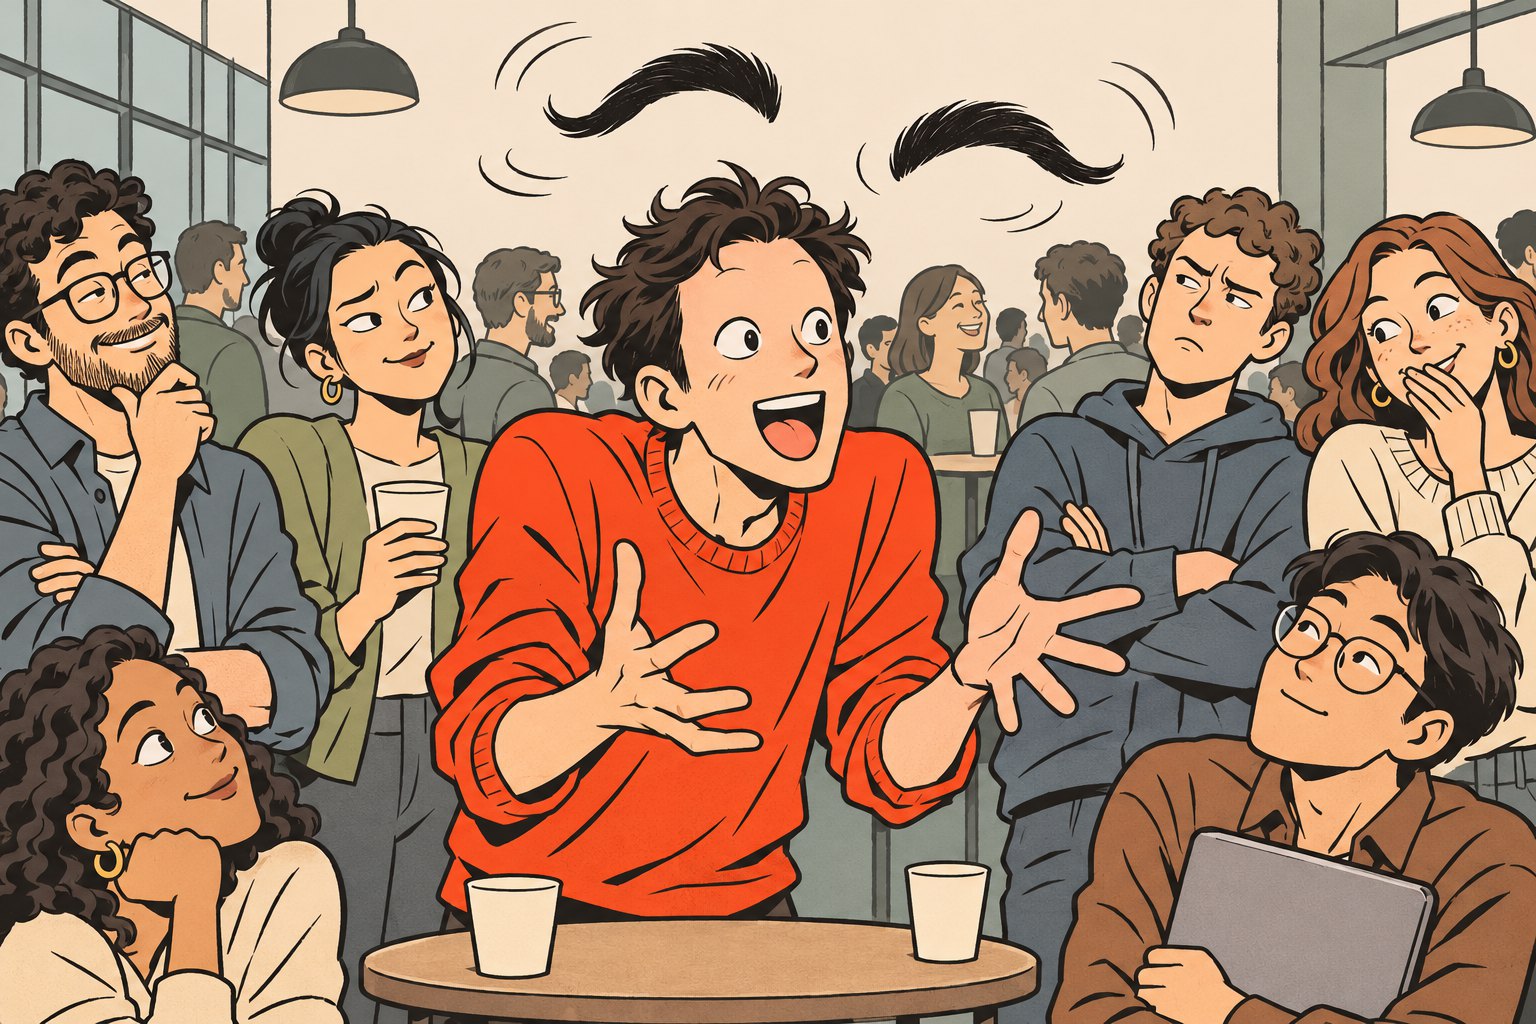
In October, at a data event in Shenzhen, I watched a freshly graduated PhD pitch a crowd with enormous passion, eyebrows flying and face dancing. I mean that literally: there’s a Chinese idiom, 眉飞色舞, “eyebrows fly, face dances,” and his expressions were so animated that every feature on his face, his eyebrows above all, really did seem to be dancing. It struck me once again how much a four-character idiom can capture in a single image.
I asked him: with so many data companies around now, what’s your edge?
He said: my company is just me, so there’s no overhead. I’ll do this for six months and see how it goes.
I’ve asked a lot of people this question. Most gave me answers like “We have better technology and a lot of accumulated know-how,” or “Frontier labs that used our data say we’re better than other data vendors.” It seems every data startup has its own know-how, its own unique edge, and the approval of its clients.
It’s like how every paper claims novelty and state-of-the-art results. When we were new to the field, we could still gaze in awe at whoever said it. After all, surely they had some secret technique that mere mortals like us could never come up with.
But after asking many companies, I never heard anything that struck me as genuinely new.
Some startups say they maintain a strong network of domain experts. What counts as an “expert,” though, is anyone’s guess.
All the answers I got were presentable talking points, the kind you use to win over investors. In my view, the only thing that can truly set a data startup apart is connections: knowing people at frontier labs, or having worked at one yourself, so you know what they want and can sell your data through those relationships. In China, I’d guess this also involves the culture of business dinners, banquet drinking, and gift-giving.
Quality matters, of course, but quality rarely becomes a moat. Plenty of startups can get quality to a certain bar, so it’s hard to stand out on quality alone.
Besides, “quality” itself is hard to define (just as hard as “expert”). When labs buy data, they mostly judge “quality” by eye, or have the vendor train a small model on it. And there have been cases where the same data worked well when one lab trained on it and poorly at another.
Very often, the details you controlled strictly and spent hours on make no difference at all to the final result.
For startups whose founders have research backgrounds but no unique edge, and no exceptional funding, limited resources usually leave three paths: build benchmarks and evals, make data, or build agent frameworks and apps. These paths also turn into one another. An agent app that fails can pivot to selling its user data. A benchmark or eval that gets noticed by the industry and the labs becomes an opening to sell data to those labs. Data vendors build benchmarks too: if one of theirs catches on, orders won’t be a problem for a while.
Here are some of the ways I’ve seen data being sold.
(1) Crowdsourcing tasks
In academia, crowdsourcing tasks to build a benchmark makes sense; resources really are scarce. Some PhDs coming out of academia, with plenty of experience doing exactly this, have taken the crowdsourcing model to new heights in their startups.
In academia, people who join crowdsourced projects want authorship and don’t care much about money. And since the work of individual PhD students has less and less impact, people welcome the chance to join a project that looks more impactful. Some Chinese students are especially drawn to these projects, because publications help with green card applications later on.
For example, one startup modeled itself on Terminal-Bench, crowdsourcing tasks and recruiting contributors on Xiaohongshu (RedNote). I recently came across a Xiaohongshu post criticizing startups like this. Opinions in the comments were mixed, and the main criticisms were:
(a) Compared with Terminal-Bench, the tasks and process weren’t very clear, and some people put in time but didn’t end up on the author list.
(b) The promise of authorship (specifically, submissions to ICLR and Nature) is basically an empty promise, since there’s no guarantee the paper will be accepted.
(c) Their benchmark still hasn’t been open-sourced. Crowdsourced academic research at least gets open-sourced in the end, so the people who contribute for love do it willingly. Once the work is used for a founder’s own business, contributors deserve to be informed, and to receive a reasonable explanation and compensation.
Note: the criticisms above are not my personal views; I’m only relaying what the Xiaohongshu post said.
(2) Publish a public benchmark first, then sell data
I don’t know much about marketing, but a lot of things work the same way. If there’s no demand, create demand. If people don’t feel anxious, make them anxious. Of course a benchmark has to make models perform badly. Otherwise, who would buy the data?
From academia’s point of view, if models already do too well on a benchmark, it suggests the problem being studied isn’t important, so performance has to be low there too.
So academia and startups alike have every motivation to make models look bad, and I’ve seen a pile of benchmarks that strike me as unreasonable. Either the verifier is too strict, so a model that gets the task right in a different way still scores low; or the task itself is flawed, leaving out ambiguous details the model was never told, so there are several valid readings, yet the model is expected to follow one particular one.
(3) Agent apps
Among companies building agent apps, some discover, just as they’re about to go under, that people will pay good money for their data, so they pivot on the spot and become data vendors. Others are doing fine, and alongside their main business they generate synthetic data from their user data and sell it.
(4) Free-token sites
They give you tokens for free, but they take your data. When something looks free, it’s worth asking what you’re giving up without noticing.
(5) API relay stations
Compared with free-token sites, relay stations (services that resell access to model APIs) charge users for tokens on one end and get paid for the data downstream on the other.
You pay for the tokens; it turns around, packages up your call logs, and sells them. It gets paid twice.
I heard that one model company went shopping for data and found it had bought its own: a relay station it was using had sold its data.
Besides selling data directly, there are other ways to profit, such as being a middleman.
People who already have connections can reach buyers directly.
Many others have no connections, but armed with an all-in, fearless, hard-grinding founder spirit, they reach out on their own, ask for introductions, and gradually find their way to buyers.
And then there are people who don’t know the industry, have no connections, and can’t sell. They just have a batch of data and have heard that data sells, and sells well, but they don’t know how to sell it. Fortunately, it’s fairly easy to find a middleman willing to buy it cheap. So they let the middleman take a cut: they hand over the data, and the middleman sells it to the labs.
I’ve tweeted before about what puzzles me here. Even with so many vendors flooding in, and with selling data apparently having no moat, why is this business still booming, with everyone seemingly still making money? And why isn’t in-house staff enough for the labs, so that they spend so much buying data from outside?
At first, I thought the answer was expert data: anything labeled by humans obviously has to be bought from outside.
But a lot of it is synthetic, and many small vendors have no relevant domain expertise and make synthetic data too. And as models get stronger, less and less data deserves to be called “expert data”; data hand-labeled by human experts may not even beat what the model generates itself. At that point, apart from vendors with truly top-tier experts, do the rest have any value at all? Mistral Large 4’s technical report, for instance, says the environments, tasks, reference solutions, and verifiers used in its post-training were mainly built and written by agents, and it doesn’t mention outsourced data or human annotation.
As I said, generating synthetic data has no barrier to entry. It used to take a sufficiently smart researcher; now, with LLMs, even someone who knows nothing about research and has no industry experience can learn to do it with an LLM’s help. So some labs that are short on money simply do it themselves.
Model improvement depends on compute and data. Some well-funded labs have allocated plenty of money to both, and once it’s allocated, why not spend it all? Compared with not buying data, buying from outside surely won’t make results worse. So why not?
Another consideration: even if they want more compute, it may not be easy to buy. Data is easy to buy, so they might as well buy more data.
Then there are the legal issues. Data is a gray industry, with plenty in it that isn’t legal. Labs don’t want to deal with that themselves, so vendors, who can operate at the edge of the law, act as what Chinese calls a “white glove”: a front that keeps the client’s hands clean.
Because the data business is so lucrative, people (including some researchers with polished reputations) are willing to do things by any means necessary. Take the case I mentioned earlier of an agent app that couldn’t keep going and turned to selling data. The two cofounders parted ways, and before the split, founder A had made a copy of the data for themselves (I suppose that’s what they call being prepared?). Later, thinking about selling data, founder A logged back into the server founder B maintained, a few months after the split, trying to “steal” more. Founder B caught it, and data ownership was eventually settled through legal means.
Some founders have also hinted that employees at companies or data shops could steal data from the inside. With profits this big, I, as a bystander (trying hard to stay out of it), have watched people around me do all sorts of outrageous things in the face of temptation and money.
None of these stories involve my own interests, but they’ve made me even less willing to go out of my way to help people. I’d seen outrageous behavior from professors and others more senior than me in academia, but rarely among my peers. These episodes, including the “Tian Keyu poisoning” case (a ByteDance intern accused of sabotaging the company’s model training), which I keep holding up as the textbook example in my writing lately (a classic never dies), made me realize I’m now senior enough, because my peers are old enough to pull off all kinds of outrageous stunts.
Whether it’s the “experts” labeling data or the people who saw the wave coming and jumped into the data business, it’s like a building about to collapse: no one wants it to fall, yet everyone is helping it fall faster.
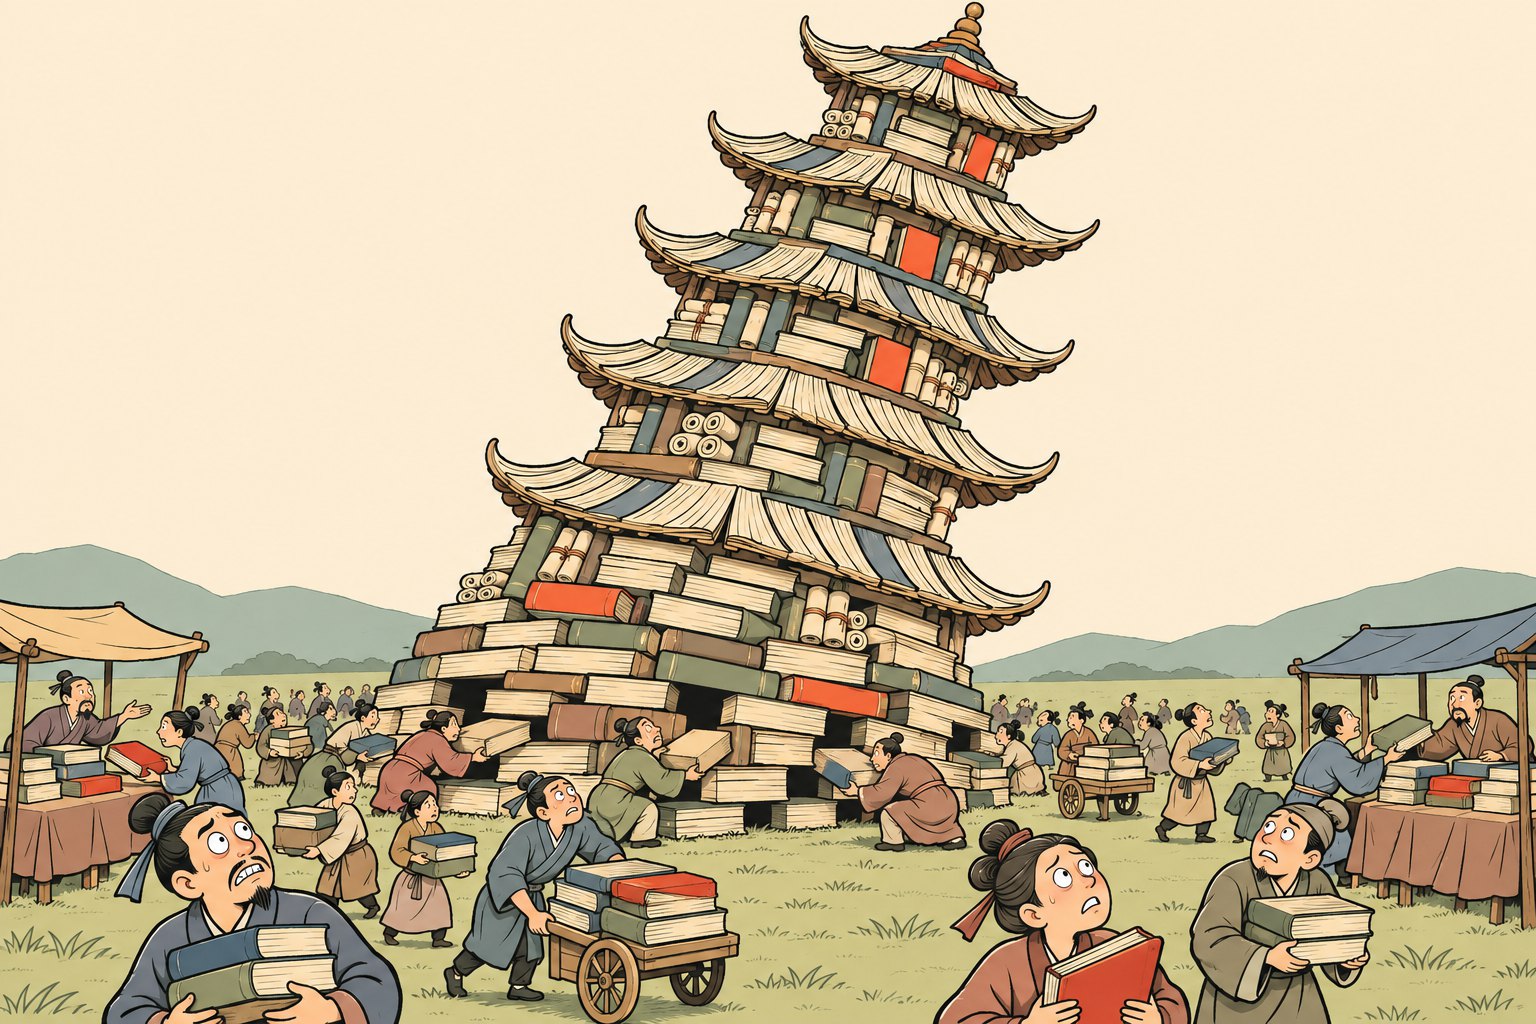
If you don’t sell data, someone else will. If you don’t help label it, some other expert will. Money you don’t make, someone else will, so why not make it yourself? It’s like everyone building stronger models: no one can stop. If one lab stops and the others don’t, won’t it just fall behind?
If labeling data as an expert, chasing benchmarks to sell data as a vendor, or deciding whether to get data by “stealing” are all things one can choose to do or not, then what about the company that once forced its employees to record their screens, and reassigned them to label data, all to improve its models? How much of that was their choice?